Comparing enterprise AI APIs on model quality is the fastest way to pick the wrong one. Capability converges within months, while the terms around the capability do not: quota tiers vary by an order of magnitude between accounts on the same platform, retention policies differ on whether prompts can be used for training, deprecation notice ranges from thirty days to a year, and only some providers let inference traffic stay inside a private network. Those four terms decide whether an application survives its first year in production. We have rebuilt integrations for clients twice because a model was retired with short notice, and never once because the model was not smart enough.
Overview: five things that decide an enterprise AI API choice
- Quota at launch, not quota on the pricing page. Default tokens per minute on a new account are frequently a fraction of the published ceiling, and raising them takes a support request with a business justification and a wait.
- What happens to the prompt after the response. Whether inputs are retained, for how long, and whether they can be used to improve the model, is a contractual question with very different answers across providers.
- Deprecation notice and version pinning. An application pinned to a version that gets retired needs re-evaluation work, and the length of the warning decides whether that is planned work or an incident.
- Network path. Public internet inference is fine for many workloads and disqualifying for some. Private endpoints and regional routing are available unevenly.
- Billing shape. Per token pricing looks comparable across vendors until you account for cached input rates, batch discounts, output token multiples and minimum provisioned throughput commitments.
This is written for CTOs and IT directors at firms between 50 and 500 people putting a first real AI workload into production, where the choice has to hold for at least two budget cycles. If the underlying cloud decision is still open, our comparison of AWS versus Azure is the better place to start.
Where enterprise AI API comparisons go wrong
Most published rankings of the best enterprise AI APIs measure capability on public benchmarks, and capability is the axis least likely to differ in a way your workload notices. A model that scores three points higher on a reasoning benchmark will not obviously outperform on summarising your support tickets, because your tickets are not in the benchmark and the benchmark is not your task.
Benchmark scores against your own prompts
Public benchmarks measure general capability across broad task distributions, and that is genuinely useful when you know nothing about a model. It stops being useful the moment you have fifty real examples from your own domain, because at that point you can measure the thing you actually care about.
The counter argument is that building an internal evaluation set costs engineering time most small teams do not have, and that benchmark rankings are a free approximation. That is fair, and the cost is smaller than it sounds. Fifty labelled examples and a scoring rubric is an afternoon, and it will separate candidate models more reliably than any leaderboard.
Where benchmarks retain real value is in narrowing the field before you spend that afternoon. Use them to pick three candidates, then let your own examples pick the winner.
Token pricing that hides the real bill
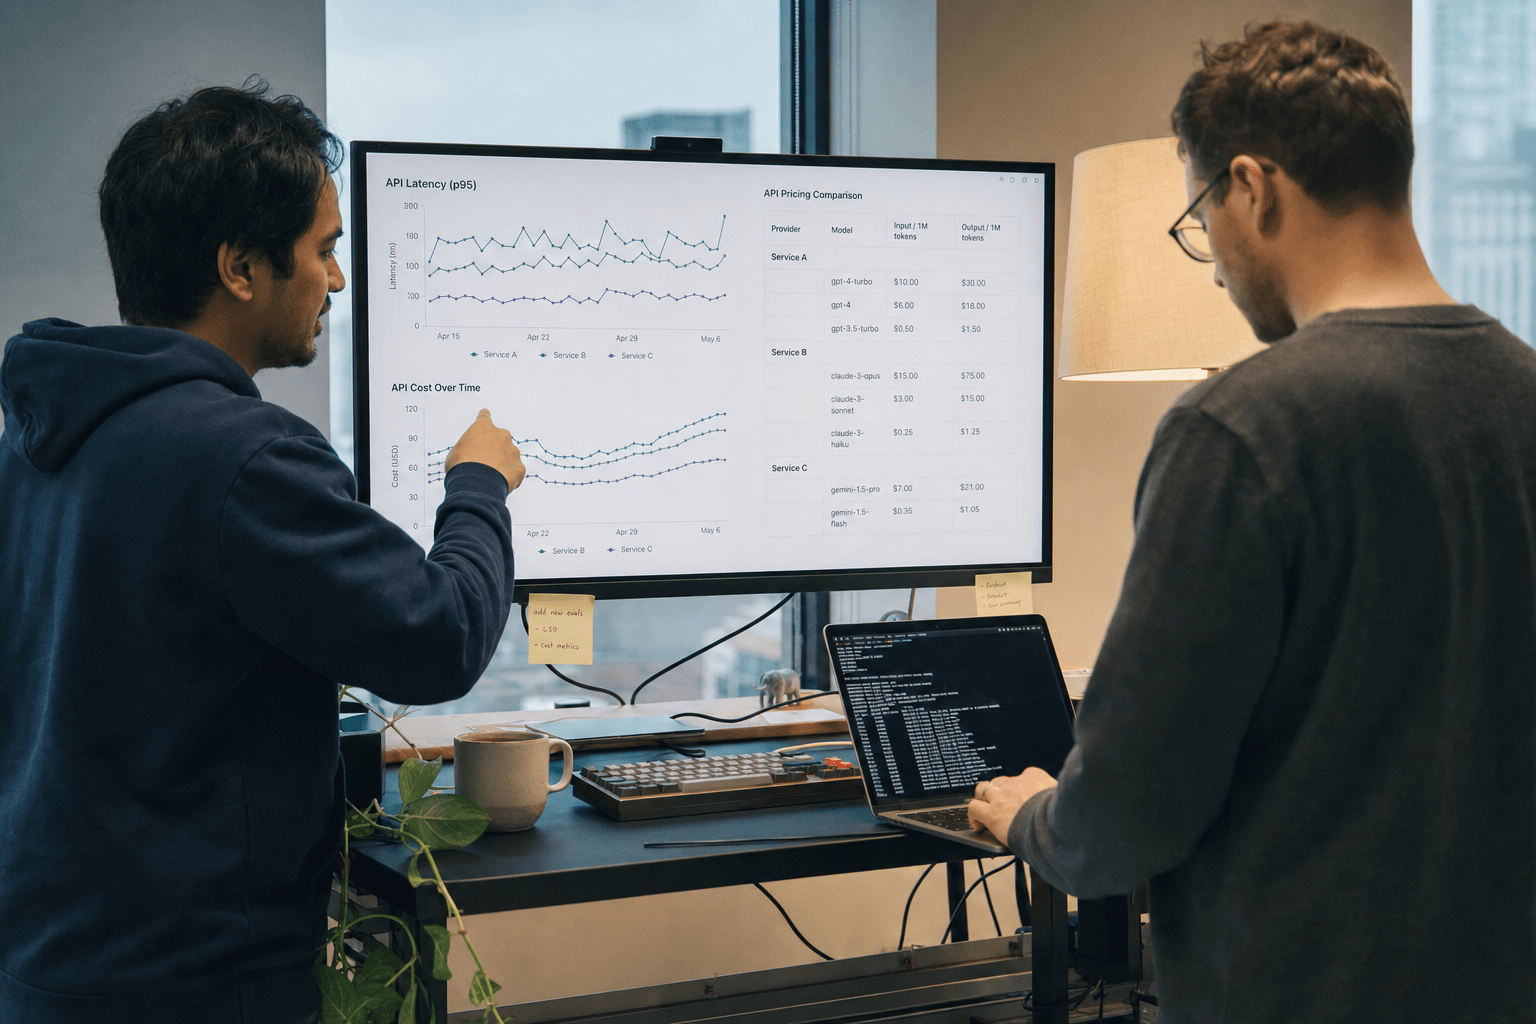
Headline pricing is quoted per million tokens and the real invoice depends on three multipliers most comparisons omit: output tokens usually cost several times input tokens, cached input is discounted heavily on some platforms and not offered on others, and batch processing carries its own rate.
A retrieval heavy workload that sends a large context and receives a short answer behaves completely differently from a drafting workload that sends a short instruction and receives two thousand words. The same two providers can swap places depending on which of those you are running.
The practical move is to take one week of representative traffic, count input and output tokens separately, and price that shape against each candidate rather than comparing the headline numbers.
Rate limits and quota tiers nobody reads until launch
Quota is the constraint that most often surprises a team in week one of production. New accounts start on entry tiers, the published maximums apply to accounts with spend history, and the gap between them is wide enough to make a successful launch look like an outage.
Some argue this is a solved problem because every provider has a quota increase form. It is solved on a timescale of days to weeks, which is a poor match for a launch date already committed to a business owner. Request the increase during the pilot, not during the rollout, and get the approved number in writing before the go live date is set.
The enterprise AI APIs most mid sized stacks land on
Enterprise AI API pricing and terms tend to push firms toward one of four options, and the choice is usually decided by where the data already lives rather than by the model. Understanding which of the four your existing estate favours removes most of the comparison work before it starts.
Azure AI Foundry and the tenant argument
Firms already running Microsoft 365 and Entra ID get identity, network policy, logging and billing continuity by staying inside the tenant, and that continuity is worth more operationally than a marginal capability difference. Private endpoints keep inference off the public internet, and the audit trail lands where the rest of the estate’s audit trail already is.
The drawback is model availability lag and regional capacity. A model released by a vendor is not immediately available in every Azure region, and capacity constraints in a preferred region are common at launch. Teams that need day one access to a specific model version sometimes cannot get it here. Our Azure work usually starts by checking regional availability against the workload before anything is committed.
AWS Bedrock and multi model routing
Bedrock’s argument is a single API surface across several model families, which matters most when you expect to switch models or route different tasks to different ones. For teams whose data already sits in S3 with IAM policies around it, the access control story is also simpler than integrating a fourth party.
The counter case is abstraction cost. A unified API exposes the intersection of what the underlying models support, so provider specific features arrive late or not at all, and debugging goes through an extra layer. Teams using one model deeply often find the direct API easier. AWS environments with existing data gravity are where this trade lands in Bedrock’s favour.
Google Vertex AI and data gravity
Vertex makes the strongest case where analytics already run on BigQuery, because the path from warehouse to model to application stays inside one permission model. Grounding a model against data you already hold there removes an entire integration.
The objection is ecosystem breadth outside that pattern. A firm without a Google data estate is buying a platform for a model, and at that point the direct API is usually simpler. Our guide to choosing between the three major clouds covers the broader version of this decision.
Direct vendor APIs and why teams still choose them
Going direct gets day one access to new versions, the full feature surface, and the shortest support path when something breaks. For a single model application, it is frequently the least complicated option available.
What it costs is a separate vendor relationship, a separate set of credentials to govern, and billing outside the cloud commitment the firm may already have negotiated. The security practices that make this workable are covered in our piece on Claude API security for enterprise deployments.
Contract terms that outlast the model choice
Data residency for AI workloads, retention and deprecation are the terms that will still matter in two years, long after the capability comparison has been made irrelevant by new releases. These are the questions to settle before the technical pilot, because they can disqualify an option regardless of how well it performs.
Retention, training use and residency
Ask three separate questions rather than one. How long are prompts and completions stored, can they be used to train or improve the model, and in which region does processing occur. Enterprise tiers generally answer these well, while consumer and developer tiers often do not, and the same brand can have very different answers across its own tiers.
For regulated work the residency answer is frequently the disqualifier, and it is worth confirming in the contract rather than the marketing page. The general principles we apply are the same ones in our cloud data security guidance.
Deprecation notice and version pinning
Pin to an explicit model version in production rather than an alias that silently moves, so behaviour does not change underneath you. Then find out, in writing, how much notice you get before that version retires. Thirty days is survivable for a simple integration and genuinely difficult for an application with a tuned prompt set and an evaluation suite to re-run.
The argument for tracking the alias is that you inherit improvements automatically and never do a migration. That holds for low stakes internal tooling and breaks for anything with an approved prompt or a compliance review attached, because the output changed without a change record. Pin in production, track the alias in a staging environment, and promote after the evaluation set passes.
Private networking and where the traffic actually goes
Inference over the public internet with TLS is appropriate for most workloads, and the firms that need more than that usually know it already: protected health information, controlled unclassified information, or a contractual requirement that traffic stay inside a virtual network. Private endpoints and service level networking are available on the major platforms and generally not on direct vendor APIs.
The cost of insisting on private networking everywhere is real. It adds routing complexity, it limits which regions and which models you can reach, and it makes local development harder. Applying it per workload rather than per firm keeps the constraint where the requirement actually sits, which is usually one or two applications rather than all of them.
Provisioned throughput versus pay as you go
Per token billing suits variable and exploratory traffic, and it becomes the wrong shape once a workload is steady and latency sensitive. Provisioned capacity buys reserved throughput at a committed monthly figure, which is cheaper per token at volume and gives predictable latency under load.
The trap is committing early. Provisioned capacity is sized in units that are difficult to reason about before you have production traffic, and an oversized commitment is a year of paying for headroom nobody uses. Run pay as you go until the traffic curve is boring, then size the commitment from measured peaks rather than forecasts.
Frequently Asked Questions
Which enterprise AI API is cheapest for a mid sized business?
Cost depends on the ratio of input to output tokens in your workload, not on the headline rate. A retrieval heavy application with large contexts and short answers can be cheapest on a provider with strong cached input pricing, while a drafting workload is decided almost entirely by output token rates.
Do I need a cloud platform to use an enterprise AI API?
No. Direct vendor APIs work from anywhere and are often the simplest route for a single model application. Platforms become worth their overhead when identity, private networking, existing data gravity or a negotiated cloud commitment are already in play.
How much notice do providers give before retiring a model version?
It varies widely and is worth confirming in writing before you build. Pin production to an explicit version rather than a moving alias, and treat a retirement announcement as scheduled engineering work with an evaluation pass, not as a configuration change.
Can prompts sent to an enterprise AI API be used to train the model?
Enterprise tiers generally exclude customer inputs from training and state a retention period, while developer and consumer tiers frequently do not. The answer differs across tiers of the same provider, so confirm it against the tier you are actually buying.
Is a public benchmark score a good way to compare AI APIs?
It is a reasonable way to narrow a field to three candidates and a poor way to pick the winner. Fifty real examples from your own domain with a scoring rubric will separate models on the task you care about far better than any general leaderboard.
Who is behind this guidance
Mindcore builds and runs AI integrations for small and mid sized firms across healthcare, legal, financial services and manufacturing, which means we spend more time on quota requests, retention clauses and version pinning than on model selection. The patterns above come from enterprise AI integration engagements where the technical pilot went well and the contract terms were what needed attention, and from the cloud security reviews that run alongside them.
Matt Rosenthal, our chief executive, focuses on how firms without large internal platform teams adopt new technology without accumulating commitments they cannot exit. His view on AI platform choice is that the model is the part you should expect to replace, so the surrounding terms are the part worth negotiating.
Pick the API your estate already argues for
The comparison that matters is short. Price one week of your own traffic by input and output tokens separately. Get your production quota approved in writing during the pilot. Confirm retention, training use and residency against the tier you are buying. Pin an explicit model version and learn the notice period. Then let the platform choice follow where your data and identity already live, because that is the integration you do not have to build twice.
If you want a second opinion on which of the four fits your estate, book a free strategy call and we will work through your traffic shape and contract requirements together.