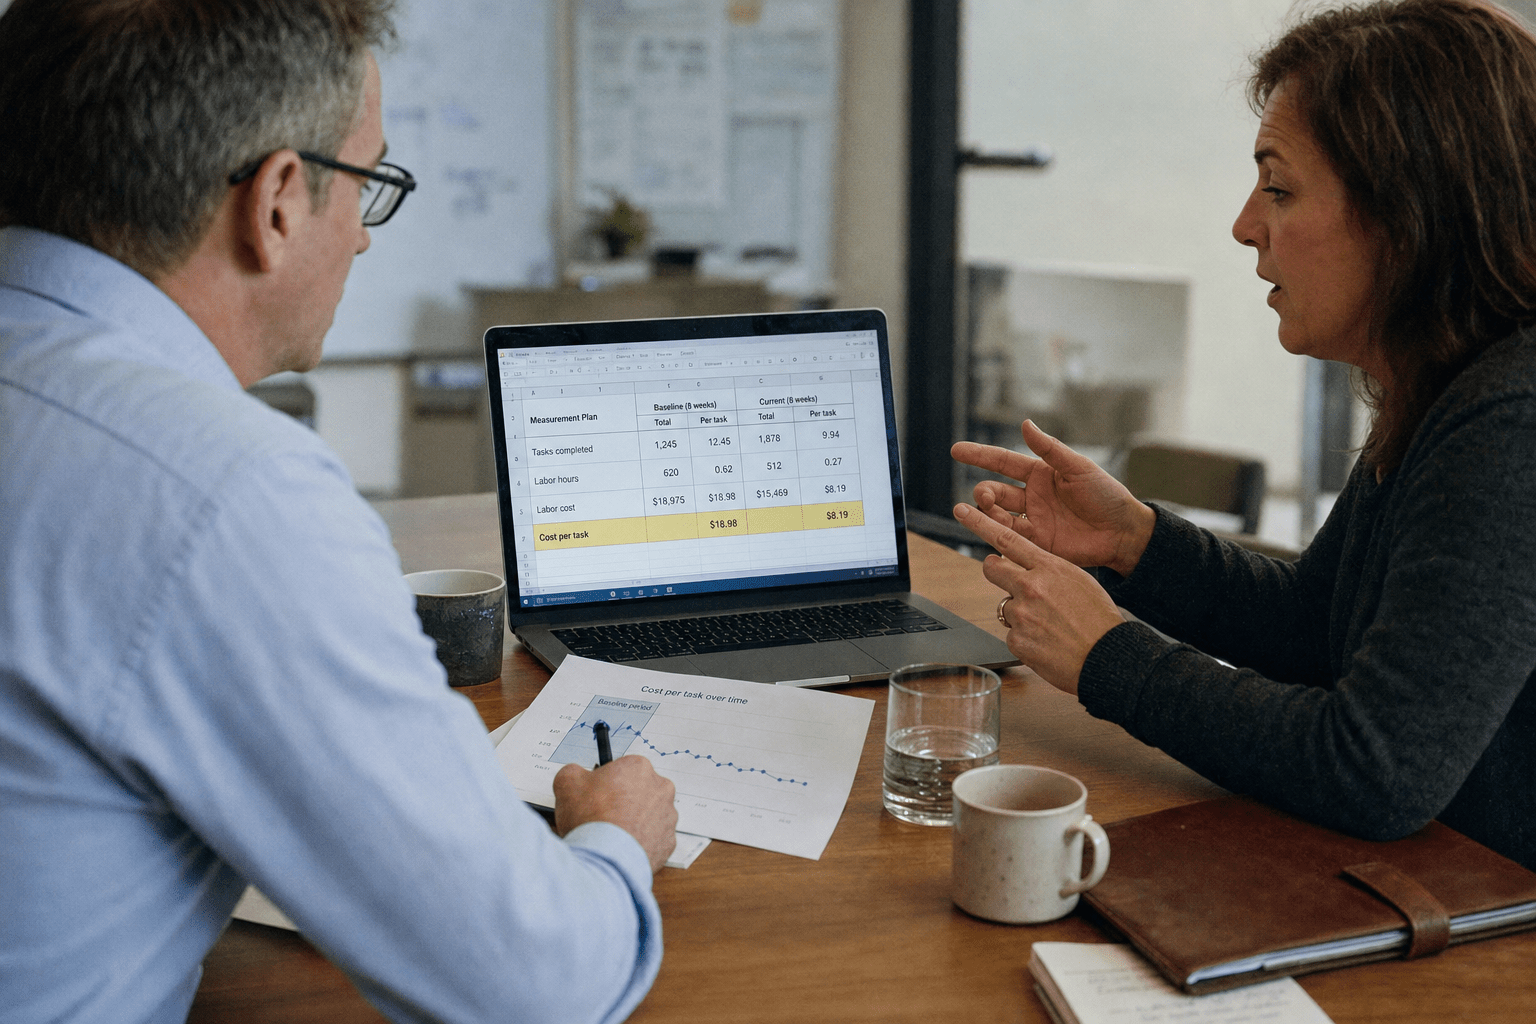
The best AI ROI metrics for enterprise leadership to track are cost per completed task, FTE hours per process, cycle time, error rate, and the financial line each of those rolls up into. What makes them defensible is not the metric itself but the baseline captured before deployment. Teams that start measuring after go-live have no before-state, so every later claim is an assertion rather than a finding. We spend 30 to 60 days measuring current performance before a single workflow moves, and that unglamorous month is what turns a renewal conversation from a debate into arithmetic.
The Five Things Leadership Should Measure
- Cost per completed task, not per call. Retries, failures, and human takeovers belong in the numerator or the number flatters itself.
- FTE hours per process, measured before and after. This is the figure a CFO can convert into money without argument.
- Cycle time on the specific process touched. Faster is only meaningful against a documented previous pace.
- Error and rework rate. Speed bought with errors is a cost transfer, not a saving.
- The financial line it rolls into. Every operational gain should terminate in revenue per head, cost per transaction, or margin.
Written for CFOs, COOs, and IT directors at 50 to 500 employee firms being asked what last year’s AI spend returned.
Why Most AI Business Cases Cannot Be Defended
Most AI business cases cannot be defended because they measure activity rather than outcome and they started measuring too late. We see the same report shape repeatedly: seats deployed, queries processed, users active, satisfaction survey. Not one of those tells leadership whether the business is better off, and none of them survives a finance review conducted by someone who was not in the room when the tool was bought.
Adoption Metrics Are Not Value Metrics
Counting deployed tools, processed queries, and active users measures whether people touched something. It is genuinely useful during rollout as an enablement signal and it is worthless as a value claim. The honest test is whether you could remove the tool and observe a business change. If the only consequence would be complaints, you have measured convenience, which is real and is not the number that justifies the invoice. Some leaders argue adoption is a valid leading indicator, and it is, provided somebody has committed in advance to what the lagging indicator will be and when it gets checked. Without that commitment, adoption quietly becomes the permanent metric because it is the one that always looks good.
The Baseline You Did Not Capture
Before any workflow moves, measure the current state: error rates, cycle times, FTE hours per task, and cost per transaction, over a window long enough to cover normal variation. Thirty to sixty days is the range we use. Skipping it is the most expensive shortcut in the whole program, because the alternative is reconstructing the before-state later from memory and partial reports, and everyone involved now has an interest in the answer. Reconstruction also tends to produce suspiciously round improvements, which is exactly what a sceptical CFO will probe. The discipline is the same one we apply to any service investment, covered in measuring the success of a managed IT partnership.
Total Cost Is More Than the Licence
The denominator is where business cases quietly go wrong. Total cost includes the platform, the underlying model consumption, integration engineering, the internal owner’s time, the training effort, and the ongoing evaluation work that keeps quality honest. Model consumption in particular scales with usage rather than headcount, so a successful rollout raises its own cost in a way a licence-based forecast does not anticipate. We build the denominator before the numerator for that reason, and it usually reorders the shortlist. The same discipline applied to service spend is in the cost of managed IT services and ROI.
The Four Levels a Metric Should Roll Up Through
A defensible AI measurement system connects four levels: the task, the process, the function, and the enterprise financial statement. Most programs measure the first level well, the second occasionally, and abandon the chain before it reaches anything a board recognizes.
Task Level, Where the Evidence Is Cleanest
At task level you can measure precisely: time to produce a draft, accuracy against a reviewed sample, rework rate, cost per completed unit. This level is where evidence is strongest and where the numbers are least contested, because the comparison is narrow and the confounders are few. It is also the level most likely to be quoted out of context. A 40 percent reduction in drafting time is a real task-level result and says nothing about whether the function delivered more, since the constraint may sit three steps downstream. Report task-level gains as task-level gains and resist the temptation to annualize them straight into a headline.
Process and Function Level, Where the Confounders Live
Process level aggregates tasks into something a manager owns: a claim handled end to end, a month closed, a ticket resolved. Function level aggregates further into an organizational unit’s outcome. This is where measurement gets genuinely hard, because other things changed during the same period. Headcount moved, a system was upgraded, seasonality arrived. We handle it by naming the confounders in writing at baseline time and agreeing which ones would invalidate the comparison. Doing that before the result is known is what separates measurement from advocacy, and it is a habit worth carrying across every technology decision, which is the theme of AI-powered decisions versus gut instinct.
The Enterprise Line, and When to Refuse to Draw It
The highest level connects the program to EBITDA margin, revenue growth, return on invested capital, or total shareholder return. For a very large deployment that connection can be real. For a mid-sized firm running three AI workflows, claiming a line to EBITDA is usually unserious, and a finance function will say so. The stronger move is to stop at the highest level you can genuinely evidence and say plainly why you stopped there. Credibility earned by declining to overclaim is worth more over a multi-year program than one flattering slide, and our note on quantifying security and operational benefits works through that discipline in an adjacent domain.
Quality Metrics Belong Beside Every Speed Metric
Every speed improvement should be reported next to a quality measure taken the same way, because speed on its own can always be manufactured. A drafting tool that halves production time while raising the rework rate has moved cost from one team to another and shown up as a win in the first team’s report. The pairs we insist on are cycle time beside error rate, volume handled beside escalation rate, and cost per completed task beside the proportion of tasks needing human correction. Each pair should be sampled by someone who does not own the program, which costs a few hours a month and removes the most common objection a review can raise. Where quality is genuinely subjective, as it is for written output, define a short rubric at baseline time and have two reviewers apply it to a sample before and after. The rubric will be imperfect and it will be consistent, which is the property that makes a comparison mean something.
The Attribution Problem Every CFO Raises
Attribution is the question of whether the improvement came from the AI or from something else that happened at the same time, and it is the first thing a competent finance partner asks. Having an answer ready changes the entire tone of the review.
Hold Something Back to Compare Against
The cleanest answer is a control: a team, region, or queue that keeps working the old way for a defined period. This is easier than it sounds in a mid-sized firm, because rollouts are usually phased anyway. Deliberately sequencing the phases so the later group functions as a comparison costs nothing and produces evidence nothing else can. The objection is fairness, since one team gets a useful tool later than another, and that is a genuine cost worth weighing against having a defensible number. We usually run the control for a single quarter, which is long enough to be informative and short enough to be tolerable.
Write Down the Counterfactual in Advance
Where a control is impossible, write down before deployment what you expect would happen without the tool, including any trend already in motion. A process improving 3 percent a quarter on its own will keep improving, and claiming that trend as an AI benefit is the single most common overstatement in these reviews. Recording the prior trajectory at baseline time makes the later subtraction honest and quick. It also protects the program, because a modest verified gain survives scrutiny while an inflated one invites an audit of everything else.
Separate One-Time Savings From Recurring Ones
A migration or cleanup assisted by AI produces a one-time saving. A workflow running continuously produces a recurring one. Business cases that blend the two produce a first-year figure that cannot repeat, and the second-year review is where that comes apart. Label each benefit as one-time or recurring in the model itself, which takes a column and prevents a year of awkwardness. Project-shaped AI work of that kind is worth reading about in AI tools for enterprise software migration projects, and the ERP analogue in our NetSuite ROI case study.
Set the Review Cadence Before Anyone Is Invested
Decide when the program gets judged, and against what threshold, while the decision is still cheap to make. A review date agreed at purchase is a neutral checkpoint. The same review proposed nine months later, after a team has built its workflow around a tool, arrives as a threat and gets negotiated rather than answered. We set two dates at the outset: a 90-day operational check on whether the metrics are even being captured correctly, and a review at the end of the first contract term against the thresholds written into the business case. The first one catches the common failure, which is that instrumentation was never wired up and nobody noticed until the number was needed. The second is the real decision point. Write down in advance what result would lead you to expand, what would lead you to hold, and what would lead you to stop, and have the budget owner sign that page. Programs with those three lines defined end cleanly when they should. Programs without them tend to continue by default, which is the most expensive outcome available and never appears in anyone’s business case as a risk.
Frequently Asked Questions
How long should we measure a baseline before deploying AI?
Thirty to sixty days for most processes, long enough to cover normal variation including a month-end or a seasonal peak if one falls inside the window. Shorter baselines get contested later because a sceptical reviewer can attribute the whole difference to an unusual starting period.
What is the single most useful AI ROI metric?
FTE hours per process, measured before and after, because finance can convert it into money without any interpretive step. Pair it with error and rework rate so the hours saved cannot have been bought by degrading quality, which is the usual hidden cost.
Can we prove AI caused the improvement?
Only with a control group or a written counterfactual recorded before deployment. A phased rollout gives you a control almost for free if you sequence it deliberately. Without either, you can show correlation honestly and should say that is what you are showing.
Should AI ROI roll up to EBITDA?
Only if the program is large enough for that connection to be genuine. For a mid-sized firm running a handful of workflows, stopping at function-level outcomes and explaining why is more credible than a line to EBITDA that a finance partner will dismantle in one question.
How do we account for model consumption costs that grow with usage?
Model them as variable rather than fixed, and forecast at realistic turn counts instead of headline per-seat pricing. A successful rollout increases consumption, so a business case built on licence cost alone understates the denominator exactly when the program is working.
Who Is Behind This Guidance
Our team runs technology programs for firms between 50 and 500 employees and sits in the review meetings where last year’s spend gets questioned, which is a different vantage point from the one that sells the project. That is why this article leads with baselines and attribution rather than benefit categories. The benefits are usually real. What is usually missing is the evidence that would let a finance function agree with you without taking it on trust. Matt Rosenthal, Mindcore’s CEO, keeps the practice focused on making technology investment legible to the people accountable for the number, which means a measurement plan that a CFO helped design rather than one presented to them afterward. That is the standard this is written to.
Build the Measurement Before the Deployment
Capture 30 to 60 days of baseline on the processes you intend to change. Build the denominator first, including model consumption, integration effort, and your internal owner’s time. Pick the highest level you can genuinely evidence and stop there deliberately. Sequence the rollout so a later group serves as a control, or write the counterfactual down before you start. Label every benefit one-time or recurring. Most firms we work with have a stronger case than they can currently prove, which is a measurement problem rather than a value problem and is fixable in a month if you start before the deployment rather than after. Leadership teams working on the decision-making habits underneath this will find our business owners leadership coaching relevant, and firms wanting the deployment and the measurement designed together should look at our enterprise AI integration practice. Bring last quarter’s numbers to a free strategy call and we will tell you what you can currently prove.