The best AI agent platforms for enterprise use in 2026 separate on three things almost nobody tests during a bake-off: what the vendor bills you for, whose identity the agent acts under, and what it costs to leave. Microsoft Copilot Studio, Salesforce Agentforce, Google Vertex AI Agent Builder, IBM watsonx Orchestrate, UiPath, and CrewAI all produce a convincing demo. They diverge sharply on billing unit, permission inheritance, and portability of the work you build. We judge them on those axes because they are the ones that change your invoice and your audit posture after month six.
The Five Things That Decide Which Platform You Should Run
- Your existing stack picks the shortlist, not the features. A Microsoft 365 tenant and a Salesforce org each make one platform dramatically cheaper to operate than the alternatives.
- The billing unit is the architecture. Per-conversation, per-action, and consumption pricing reward completely different agent designs, and one of them punishes multi-step work.
- Identity decides the blast radius. An agent running as a service principal with tenant-wide scope is a different risk object from one that inherits the calling user’s permissions.
- Orchestration is where the second year of cost lands. Single agents are easy. Handoffs between agents, with state, are where teams stall.
- Exit cost is real and rarely quoted. Prompts port easily. Connectors, evaluation history, and orchestration graphs usually do not.
This is written for IT directors and CTOs at 50 to 500 employee firms who have a pilot working and a renewal decision coming.
Why the Bake-Off Winner Is Often the Wrong Platform
The platform that wins your bake-off is usually the one that demos best on a clean task, and clean tasks are the least representative work an agent will ever do. We see the same sequence repeatedly. A team runs four platforms against a summarization task, everything succeeds, and the decision defaults to whichever interface felt nicest. Nine months later the invoice has tripled because the real workload turned out to be multi-step.
The Demo Task Hides the Billing Unit
Agent platforms bill on incompatible units, and the difference only appears under real traffic. Copilot Studio meters message packs. Agentforce charges per conversation with Data Cloud consumption underneath. Vertex AI Agent Builder bills the underlying model tokens plus the orchestration service. UiPath bills on robot and agent units carried over from its RPA lineage. A task that takes one turn looks identical across all four. A task that takes twelve turns, with tool calls between each, does not. Some buyers argue this resolves itself because vendors converge on consumption pricing eventually, which is partly true and has been partly true for three years running. Our position is narrower: model your actual turn count before you pick, because the unit you are billed on quietly dictates whether your engineers build chatty agents or terse ones.
Where Connectors Stop Being Free
Every platform ships a connector library, and the libraries look comparable in a feature matrix. The divergence is in what happens at the edge of the library. Copilot Studio reaches anything through Power Platform connectors, which is genuinely broad, but premium connectors carry their own licensing and Dataverse sits underneath as a dependency you are now operating. Agentforce is superb inside Salesforce objects and needs Data Cloud ingestion for anything outside them. Vertex expects you to bring your own integration layer and gives you strong primitives rather than a catalog. We map the five systems an agent must touch before we shortlist, because a platform that covers four of them elegantly and the fifth not at all is usually the most expensive option on the table.
The Identity Question Nobody Asks in Month One
Ask which principal the agent acts as. Copilot Studio agents can run with delegated user permissions or with an application identity, and the choice determines whether a user can extract records they could not otherwise reach. Agentforce inherits the running user’s Salesforce sharing rules, which is the strongest default in this group. Self-hosted frameworks give you a service account and total freedom, meaning the permission model is now yours to design. Our fuller treatment of the exposure sits in are AI agents safe for enterprise use, and the platform comparison above is really a comparison of default answers to that one question.
How the Major Platforms Actually Differ
The major platforms differ less in model quality than in the operating model they impose on your team, because nearly all of them now let you choose the underlying model anyway. What varies is where the state lives, who administers it, and which team owns the failure.
Microsoft and Salesforce: Gravity Beats Features
If your data and your users already live in one of these two, the native platform usually wins on total cost even when it loses on capability. Copilot Studio agents sit inside the tenant, respect existing conditional access, and are administered by people already trained on the admin center. Agentforce does the same for Salesforce-native organizations, with sharing rules as the permission spine. The counterargument is real: gravity is how you end up with an agent estate you cannot move. We treat that as a cost to price rather than a reason to avoid the platform, and we write the exit plan during procurement rather than during the dispute.
Google Vertex, IBM watsonx, and the Build-More Camp
Vertex AI Agent Builder and watsonx Orchestrate both assume a team that wants control over orchestration rather than a packaged experience. Vertex gives strong grounding and IAM that security teams recognize immediately. Orchestrate leans on a skill catalog and suits organizations with established process automation. Both demand more engineering than the two above and repay it with portability and observability. For firms of the size we work with, the honest test is whether one named engineer will own this in twelve months. If the answer is no, packaged wins, and we have watched several excellent Vertex builds decay after the one person who understood them changed roles.
Open Frameworks and the Operations Bill
CrewAI, LangGraph and similar frameworks are where the interesting multi-agent work happens, and they carry an operations bill most comparisons omit. You are now running the orchestration layer, the state store, the evaluation harness, and the upgrade treadmill. That is a reasonable trade for a team with platform engineers and an unreasonable one for a four-person IT department. The coordination patterns themselves are worth reading regardless of platform, which we cover in multi-agent systems and coordinating AI agents. Model choice sits underneath all of this and moves somewhat independently, a comparison we work through in Claude API versus OpenAI API for secure enterprise use.
UiPath and the RPA Platforms Coming the Other Way
UiPath and the process automation vendors arrive at agents from the opposite direction, and that history shows in both good and awkward ways. They bring mature scheduling, queue management, audit trails, and a deployment model built for unattended work at volume, which the newer platforms are still assembling. What they bring less naturally is conversational handling, because the lineage assumes a deterministic process rather than a negotiation with a user. For back-office work with defined inputs, invoice handling, claims triage, data reconciliation, that lineage is an advantage rather than a limitation. For anything customer-facing the fit is weaker. We have seen firms run UiPath for the process half and a conversational platform for the front half, and the pairing works better than either vendor’s pitch for covering both. Licensing is the part to model carefully, since the unit carries over from robot-based pricing and does not always map cleanly to agent work.
What to Measure During the Pilot
Measure the pilot on cost per completed task, escalation rate, and time to fix a broken agent, because those three predict the second year better than accuracy does. Accuracy on a curated set is the number every vendor volunteers and the one that transfers least well to production.
Cost Per Completed Task, Not Per Call
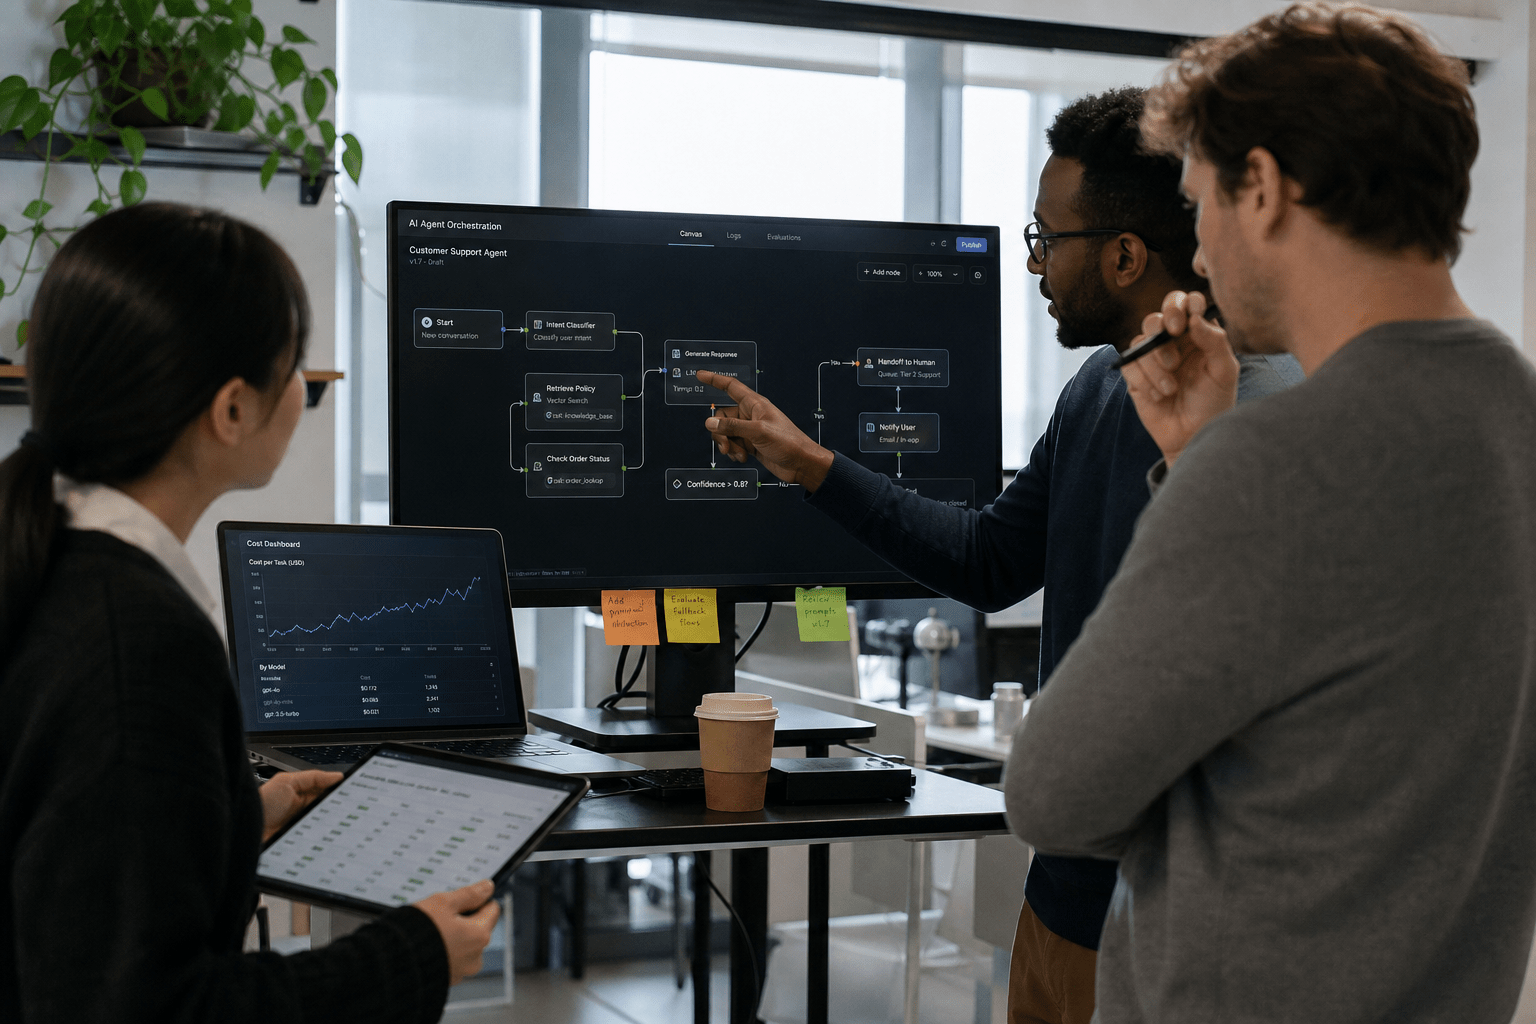
Instrument the pilot so you can divide total platform spend by tasks that reached a correct terminal state. Failed attempts, retries, and human takeovers all belong in the numerator. Teams that measure per-call cost consistently underestimate by a wide margin, because the retries are invisible in the vendor dashboard. This is the number we hand to a CFO, and it is the only one that survives contact with a renewal conversation.
Escalation Rate and the Handoff Path
Track how often the agent hands to a human and what the human then has to reconstruct. A platform with a clean handoff, full transcript, and preserved context turns a 60 percent escalation rate into a workable service. A platform that drops the thread makes a 20 percent rate feel worse. Test the handoff deliberately during the pilot rather than discovering it in production. Our guidance on the governance wrapper around all of this is in the AI agent governance guide.
Time to Repair a Broken Agent
When an agent starts failing, how long until someone can see why and ship a fix? This is an observability and tooling question, and it varies more than any other axis. Some platforms surface a full trace of tool calls and intermediate reasoning. Others surface an outcome. We time this during the pilot by deliberately breaking a connector and watching the clock, which has changed more platform decisions for our clients than any feature comparison.
The Data Residency and Logging Question
Find out where prompts, tool outputs, and traces are stored, and for how long. This decides whether the platform is usable for a healthcare or regulated finance workload before any feature discussion matters. Platforms inside your existing cloud tenant generally inherit the residency commitments you already hold, which is one of the quieter reasons gravity wins. Standalone vendors vary widely: some offer regional processing with logging retained centrally, which satisfies the letter of a residency requirement while leaving transcripts somewhere you did not expect. Ask specifically about trace retention rather than data residency in general, because traces contain the richest copy of whatever the agent touched. We also ask whether logging can be disabled per workflow, since the answer is often yes, and teams handling protected data usually want that switch available even if they leave it on for most agents. A platform that cannot answer this in writing is not ready for a regulated workload regardless of how well it performed in the pilot.
Frequently Asked Questions
Which AI agent platform is best for a Microsoft 365 organization?
Copilot Studio is usually the lowest-friction choice for a Microsoft 365 tenant, because agents inherit conditional access, live inside existing governance, and are administered by staff already trained on the tooling. Check the message-pack pricing against your expected turn volume before committing, since multi-step agents consume far more than the pilot suggests.
Do enterprise AI agent platforms lock you in?
To varying degrees, yes. Prompts and instructions port easily between platforms. Connectors, orchestration graphs, evaluation history, and any data ingested into a proprietary store generally do not. Price the exit during procurement and keep your agent definitions in version control you own rather than only in the vendor’s designer.
How much should a mid-sized firm budget for an agent deployment?
Budget for the platform, the underlying model consumption, and one named owner’s time, which is the line most teams omit. The platform fee is rarely the largest component past the first quarter. Model a realistic turn count per task, then multiply by the vendor’s actual billing unit rather than their headline price.
Can one platform run every agent use case?
Rarely, and forcing it usually costs more than running two. Customer-facing conversational agents and internal process automation have different latency, logging, and permission needs. Many of our clients end up with a packaged platform for the front office and a lighter framework for back-office automation.
What should we test that vendors do not demo?
Test the handoff to a human, the trace available when an agent fails, and the behavior when a connector returns an error rather than data. Those three account for most of the operational pain and appear in no sales demo we have sat through.
Who Is Behind This Comparison
Our team runs agent deployments for firms between 50 and 500 employees, mostly in managed IT, healthcare, and professional services, and we operate them afterward rather than handing over a slide deck. That second part is why this comparison weighs billing units and repair time over benchmark scores. We have moved clients off platforms that tested well and onto ones that operate well, and the gap between those two outcomes is where most of the cost lives. Matt Rosenthal, Mindcore’s CEO, keeps the practice focused on decisions a business owner can actually defend, so a platform recommendation has to survive a question about next year’s invoice rather than only a technical review. That is the standard this article is written to.
Choose the Platform You Can Still Afford in 2027
Start from your existing stack, shortlist two platforms rather than five, and run a pilot that measures cost per completed task, escalation quality, and repair time. Write the exit plan while you still have negotiating leverage. If you want a structured comparison to work from, our enterprise AI agent comparison guide lays out the evaluation grid, and our note on evaluating AI agent providers covers the vendor conversation itself. Teams building against a model API rather than a packaged platform will get more from our walkthrough of using the Claude API for enterprise automation at scale. Most firms we meet have already run a pilot and are stuck on whether it generalizes, which is a question about operations rather than models. Our enterprise AI integration practice exists for that step. Bring your pilot numbers to a free strategy call and we will tell you what the second year looks like.