Someone moves from finance to marketing on Monday. Their entitlements are updated the same morning, correctly, and every answer finance’s AI assistant ever gave them is still sitting in their chat history. That is the access control problem a shared AI deployment creates and a traditional permissions review does not catch, because the history is not in the systems anybody audited. Multi-team AI access control has to govern three things rather than one: live data access, the knowledge each team’s agent can retrieve, and the conversation record that outlives every change to both.
The Five Controls a Multi-Team Deployment Needs
- History is an access artifact. Past answers persist after entitlements change, and almost nobody has a policy for them.
- Scope knowledge per team, not per tenant. One shared index serving four teams gives each of them the others’ material.
- Decide partitioning before the second team. Retrofitting separation onto a shared agent is far harder than designing it.
- Watch service account drift. Integration accounts accumulate rights, and every user inherits whatever they hold.
- Joiner, mover, leaver needs an AI column. The mover case is the one existing processes handle worst.
Written for security leads and IT directors at 50 to 500 employee firms extending one AI deployment across several teams.
The History Problem Nobody Has a Policy For
Conversation history is a record of everything a person was told while they held their previous access, and it survives the entitlement change that should have ended that access.
What a Mover Keeps
When someone changes team, revoking their access to the source systems is routine and usually handled well. Their AI conversation history is a separate store, typically owned by the AI platform rather than by the systems the data came from, and it is rarely touched. The result is a person in marketing holding summarised finance material in a searchable archive, which is not a breach in any system’s log and is exactly what your access review was supposed to prevent. Decide the policy explicitly: retain, archive, or clear on role change. There is no universally right answer and there is a clearly wrong one, which is having no answer.
Search Makes Old History Newly Useful
Historical chat was harmless when nobody could find anything in it. Platforms that added search over conversation history changed that, and a person who has moved teams can now retrieve their own past answers as easily as current ones. If your platform gained that capability in an update, your existing decision about history was made under different assumptions and deserves revisiting. This is the same dynamic that makes enterprise search a governance event rather than a feature, and the identity-first design argument in future enterprise access control applies directly.
Leavers Are Easier and Still Get Missed
For a leaver the answer is straightforward: the history goes with the account, subject to whatever retention your records policy requires. The failure is procedural rather than conceptual, because AI platforms are often outside the offboarding checklist that covers email and file storage. Add the line. Checking whether departed staff still have accessible conversation history is a five-minute audit and a common finding, and it belongs in the same sweep as our cyber security audits.
Scoping Knowledge Per Team
A shared agent with a single knowledge base is the fastest thing to deploy and the hardest thing to correct once several teams depend on it.
One Index Is a Shared Index
When four teams’ documents go into one retrieval index, every team’s agent can surface every team’s material unless something explicitly prevents it. Vendors describe this as a unified knowledge base, which is accurate and sounds like a benefit. Decide per team what is genuinely shared, typically policy, process and reference material, and what stays partitioned, typically anything commercially or personally sensitive. That decision is cheap before the second team joins and expensive afterward, because unwinding it means rebuilding and re-testing every retrieval path.
Filter at Retrieval, Not at Presentation
Where a platform offers filtering, establish whether it happens during retrieval or after it. Filtering after retrieval means the restricted content was fetched and passed through the model before being hidden, which is a materially weaker control and one that behaves unpredictably under summarisation. Ask the vendor directly and treat a vague answer as an answer. The API-level mechanics of this are covered in Claude API security best practices.
Separate Agents Cost Less Than They Look
Running a distinct agent per team, each with its own scoped knowledge and tool list, sounds heavier than one shared deployment and is usually cheaper in practice once you count the governance work a shared one requires. It also contains the blast radius of a misconfiguration to one team. Where several agents need to coordinate, the design questions in multi-agent systems and coordinating AI agents apply, and our enterprise AI integration practice usually recommends separation at the second or third team rather than the fifth.
Identity Hygiene That Keeps Working
The controls that hold over time are the ones tied to your existing identity processes rather than maintained separately for the AI platform.
Drive Access From Groups You Already Maintain
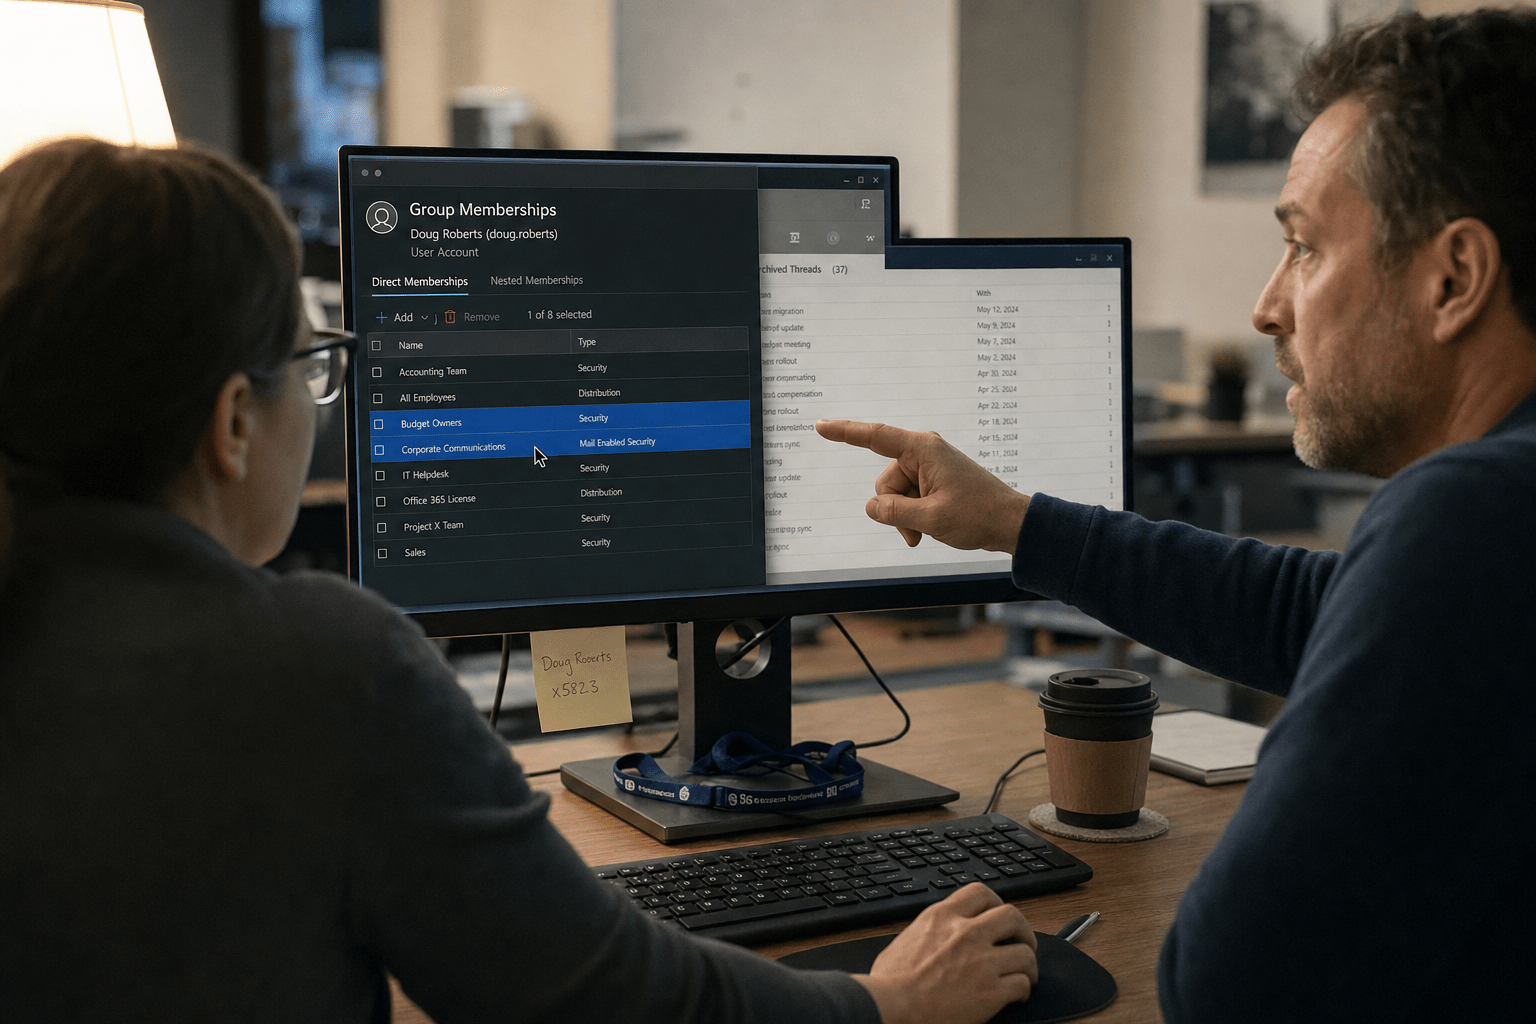
Bind AI access to the same directory groups that govern everything else, so a role change propagates without anyone remembering the AI system exists. Platforms that require their own user list guarantee drift, because a separately maintained roster is a roster nobody updates. Where the platform supports only its own model, script the reconciliation and run it monthly rather than trusting it to attention. The healthcare version of this discipline is in identity-driven access control in healthcare IT.
Audit Service Account Rights Quarterly
Integration accounts accumulate permissions during setup and troubleshooting, and nobody removes them afterward. For an AI system acting under a service identity, those rights are effectively granted to every user of the tool, which makes the quarterly review considerably more valuable than it is for a passive integration. Diff the current rights against what the documented workflows actually need and remove the difference.
Strong Authentication on the Interface Itself
The AI platform is now an access path to whatever it can reach, so it deserves the same authentication posture as any other route into your data, including multi-factor and conditional access where available. Teams occasionally exempt it as a productivity tool, which is reasoning from what it looks like rather than what it reaches. The baseline argument is in best practices for multi-factor authentication, and the exposure model behind it in are AI agents safe for enterprise use.
Proving It to Someone Who Asks
Access control that cannot be demonstrated is a design rather than a control, and multi-team AI deployments are asked to demonstrate it sooner than most systems.
Produce the Per-Team Access Matrix
Maintain a simple grid: each team down one axis, each data source and tool across the other, with the answer in each cell. It takes an afternoon to build and it answers, in one page, the question an auditor, an insurer or a customer’s security team will ask. Without it the answer is assembled from several consoles by whoever happens to understand the deployment, which is slow, inconsistent between askings, and dependent on one person remaining available.
Test Rather Than Assert Separation
Once partitioning is in place, verify it by asking one team’s agent for something only another team should hold. This takes minutes, produces evidence rather than a claim, and occasionally finds that a document is reachable through a path nobody mapped. Repeat it after any change to the knowledge base or the group structure, because both are edited more often than anyone documents, and a separation that held in March is not evidence about June.
Keep the Evidence With the Change
When you tighten a scope, remove a service account right, or clear history on a role change, record what changed and when alongside the access matrix. A year later the question is rarely what your controls are but when they came into effect, particularly if something happened in between. That record costs one line per change and is the difference between describing a control and demonstrating one.
Frequently Asked Questions
What should happen to AI chat history when someone changes team?
Decide explicitly between retaining, archiving and clearing, and write it into the mover process. The history contains answers derived from data the person can no longer reach, it usually sits outside the systems your access review covers, and having no policy is the only clearly wrong option.
Should each team have its own AI agent?
Usually yes by the second or third team. Separate agents with scoped knowledge and tool lists contain misconfiguration to one team and cost less in governance than a shared deployment requires. A single shared agent is fastest to launch and hardest to partition later.
Does filtering a shared knowledge base protect sensitive material?
It depends on where the filtering happens. Filtering during retrieval is a real control; filtering after retrieval means the content was fetched and processed before being hidden, which behaves unpredictably under summarisation. Ask the vendor which one they do.
How do AI platforms fit into joiner, mover and leaver processes?
Add them explicitly to all three, and give particular attention to the mover case, which existing processes handle worst because it involves changing rather than removing access. Leavers are conceptually simple and still missed, since AI platforms are often absent from the offboarding checklist.
How often should we review the AI system’s service account?
Quarterly. Integration accounts gain rights during setup and troubleshooting and lose them rarely, and for an AI system those rights are effectively extended to everyone using the tool, which makes the review more consequential than for a passive integration.
Who Is Behind This Guidance
Our team runs identity and access work alongside AI deployments for firms between 50 and 500 employees, and the history question is the one we find most often unanswered. Security teams handle the live-data side capably because it resembles work they already do; the conversation store is new, sits with a different owner, and falls between the AI project and the access review. We raise it before the second team joins because that is when partitioning is still cheap. Matt Rosenthal, Mindcore’s CEO, keeps the practice focused on making risk legible to the people accountable for it, which here means an access model a security lead can explain to an auditor without a diagram of the AI stack. That is the standard this is written to.
Decide History and Partitioning Before the Second Team
Write the policy for conversation history on role change and add AI platforms to all three sides of joiner, mover and leaver. Decide what is genuinely shared knowledge and what stays partitioned, and establish whether your platform filters during or after retrieval. Prefer a separate agent per team by the second or third one, bind access to the directory groups you already maintain, and put the service account on a quarterly review that diffs actual rights against documented need. Apply your normal authentication posture to the interface rather than exempting it as a productivity tool. Most firms we assess have sound live-data controls and no owner for the conversation store, which is a gap that only gets more expensive as more teams join. Bring your current access review to a free strategy call and we will show you which store it does not cover.