A clean application security review means very little for an AI deployment, because the questions it asks are about the wrong layer. Authentication, transport, patching and access control all still matter and all of them can be correct while the system remains wide open, since the new attack surface is the content the model reads and the set of actions it is allowed to take. Five questions belong in every AI review and appear in almost no standard one: what can the agent do, whose permissions does it use, what content can reach it, what happens to its output downstream, and who else is in the supply chain.
The Five Questions a Standard Review Never Asks
- What actions can it take, exactly? The tool list is the privilege model, and it is usually longer than anyone expects.
- Whose permissions does it act under? An integration account with broad rights turns every user into that account.
- What untrusted content can reach the model? Anything retrieved, forwarded or uploaded is an instruction channel.
- What consumes the output? Model output flowing into a system that trusts it is the classic injection boundary, moved.
- Who else is in the chain? The foundation provider, any connectors, and any extensions all see what you send.
Written for security leads, IT directors and risk managers at 50 to 500 employee firms reviewing an AI system before go-live.
Start With the Action Inventory
The single most useful artifact in an AI security review is a complete list of the actions the system can take, written down and signed off, because that list is the privilege model whether or not anyone has treated it as one.
Enumerate Tools, Not Features
Ask for every tool, function or connector the agent can invoke, including the ones enabled by default and never used. Feature descriptions hide this: a product that summarises documents may also be able to send email, create records or call an external service depending on what was switched on. We review the enabled list rather than the marketing list, and the usual finding is three or four capabilities nobody intended to grant. The coordination complexity behind multi-tool setups is covered in multi-agent systems and coordinating AI agents.
Separate Read Actions From Write Actions
Split the inventory in two and treat them completely differently. A read action exposes information; a write action changes state in a system somebody relies on, and the blast radius of a mistake is entirely different. For a first deployment we keep the write list to reversible operations and require an explicit approval to add anything irreversible, which is a policy decision rather than a technical constraint and is far easier to make before launch than after. The wider exposure model sits in are AI agents safe for enterprise use.
Ask What Happens When a Tool Fails
Error paths are where interesting behaviour lives. What does the agent do when a tool returns an error, an empty result, or unexpected data? Systems that retry indefinitely, that treat an error string as content, or that fall back to a less constrained path are common and rarely documented. Ask for the behaviour explicitly and test at least one failure during review rather than reading about it.
Identity Is Where the Real Exposure Sits
The permissions question determines whether a compromised or manipulated session can reach data the person in front of it never could, and it is answered very differently by different products.
Delegated Versus Application Identity
An agent acting with delegated user permissions can only reach what that user can reach, which contains the damage. An agent acting under an application or service identity is typically granted broad access so it works for everyone, and that turns any successful manipulation into access at the level of the service account rather than the user. Establish which model applies before anything else, because it changes the severity of every other finding in the review.
Trace the Effective Permissions, Not the Documented Ones
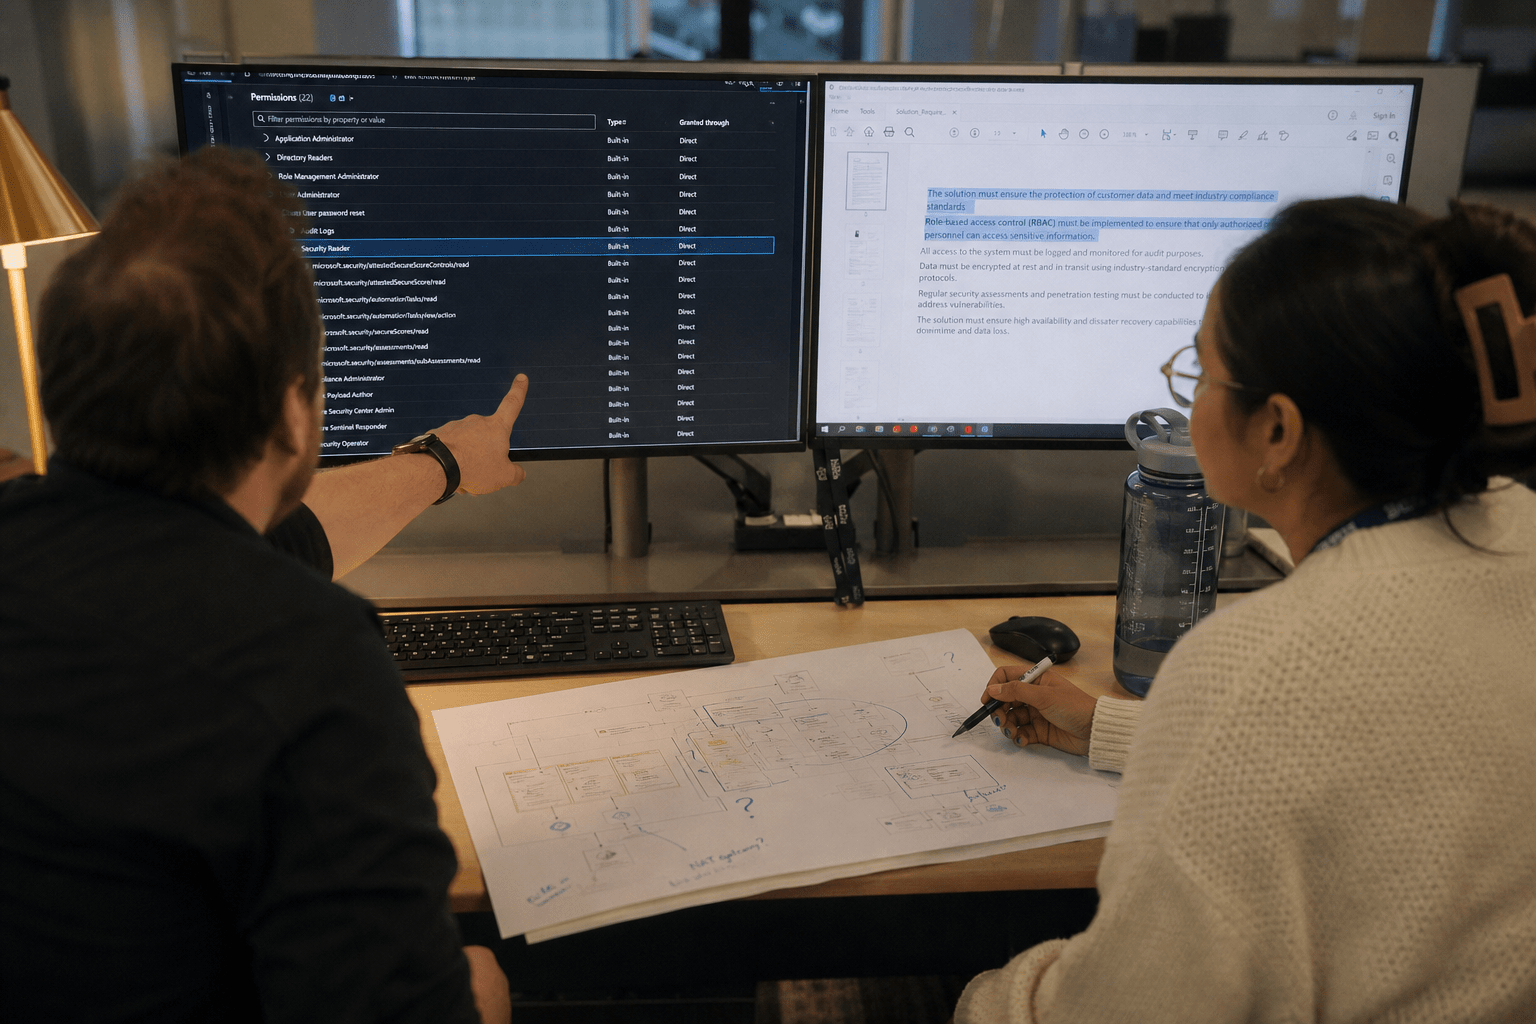
Documented scopes and effective access diverge regularly. Check what the service principal can actually reach in your environment rather than what the integration guide says it needs, since over-granting during setup is normal and nobody revisits it. This is ordinary audit work and it is the highest-yield hour in an AI review. Our cyber security audits apply the same approach to the wider estate.
Check the Logging Attribution
When the agent acts, whose name appears in the target system’s audit log? If every action is recorded as the service account, you have lost the ability to attribute anything, which matters during an investigation and matters to auditors. Good products carry the acting user through; weaker ones do not, and that is worth knowing before rather than during an incident.
The Content Channel Nobody Reviews
Anything the model reads can carry instructions, which makes retrieval, forwarding and upload paths part of the attack surface in a way that has no analogue in a traditional application review.
Map Every Path Untrusted Content Takes
List where content reaches the model from outside your control: retrieved documents, forwarded email, uploaded files, web content, and records written by customers. Each is a channel through which text can attempt to redirect behaviour, and the risk rises sharply when the system also has write actions available. The combination of untrusted input and a capable tool list is the configuration to scrutinise hardest, and our enterprise AI integration practice reviews the two together for that reason.
Test It Rather Than Asking About It
Vendors answer questions about injection resistance optimistically because the honest answer is partial for everyone. Test instead: place instruction-like text inside a document the system will retrieve and observe what happens. This takes an afternoon, produces a concrete result, and is far more informative than a questionnaire response. Where the result is uncomfortable, the mitigation is usually to narrow the tool list rather than to fix the model.
Treat Output as Untrusted Input
Whatever consumes the model’s output should validate it exactly as it would validate a user submission. Output flowing unchecked into a database write, a shell command, a URL or another system’s API is the classic injection boundary with the source changed, and it is the failure mode most likely to turn a content problem into a system problem. This belongs in the review of the consuming system as much as the AI one, and the API-level practices are in Claude API security best practices.
The Supply Chain Behind the Vendor You Contracted With
The fifth question is who else can see what you send, and the honest answer is usually longer than the contract implies.
The Model Provider Is a Party to Everything
Most AI products are built on a foundation model somebody else operates, which makes that provider a participant in every request regardless of whose logo is on the interface. Establish who it is, whether it changes without notice, and what the terms say about retention and training at that layer rather than only at the vendor’s. A vendor with excellent terms reselling a provider with weaker ones gives you the weaker ones in practice.
Extensions and Connectors Widen the Circle
Marketplace extensions, plugins and connector frameworks each add a party and an integration point, often installed by an administrator without a review because installing them is easy. Inventory what is actually enabled rather than what was approved, and treat each one as a supplier with access rather than as a feature. The cloud-era version of this lesson is in cloud security best practices and strategies.
Ask What Changes Without Telling You
The question that separates careful vendors from fast ones is what they can change unilaterally: the underlying model, the data region, the subprocessor list, the default tool scope. Get notice commitments in writing for the ones that matter to you. A system that was reviewed and approved in March can be materially different in June through changes nobody was obliged to announce, and that is a governance gap rather than a technical one.
Frequently Asked Questions
Does a SOC 2 report cover AI-specific risk?
No. It covers operational controls at the platform layer over a past window and says nothing about tool scope, identity model, injection resistance or output handling. Treat it as evidence about the vendor’s operations and run the AI-specific review separately.
What is the highest-yield hour in an AI security review?
Tracing the effective permissions of whatever identity the agent acts under. Documented scopes and actual access diverge often, over-granting during setup is normal, and the answer changes the severity of every other finding in the review.
How do we test for prompt injection without specialist tooling?
Place instruction-like text inside a document the system will retrieve, then observe whether behaviour changes. An afternoon of manual testing on your own content produces a more useful answer than any vendor questionnaire, and it tells you specifically which of your paths are exposed.
Should AI systems have write access at all?
Yes, where the write is reversible and auditable, such as setting a field or applying a tag. Irreversible or externally visible writes, including sending messages and anything with financial effect, deserve an explicit approval and are better deferred past the first deployment.
Who should run the AI security review?
Your existing security function, using an extended checklist rather than a separate process. The platform-layer questions they already ask remain valid; what they need is the five additional questions about actions, identity, content channels, output handling and the supply chain.
Who Is Behind This Guidance
Our team runs security reviews and AI deployments for firms between 50 and 500 employees, and doing both is why this checklist exists in the shape it does. Security teams we work with are good at the questions they have, and the gap is that nobody handed them the AI-specific ones, so a competent review passes a system that is wide open at the tool layer. We extend the existing checklist rather than replacing it, because a parallel process nobody owns is worse than a slightly longer one somebody already runs. Matt Rosenthal, Mindcore’s CEO, keeps the practice focused on making risk legible to the people accountable for it, which here means a review a security lead can defend without being an AI specialist. That is the standard this is written to.
Add Five Questions to the Review You Already Run
Get the complete action inventory and split it into read and write, keeping the first write list reversible. Establish whether the agent uses delegated or application identity, then trace the effective permissions in your own environment rather than reading the integration guide. Map every path untrusted content takes to the model and test one of them with instruction-like text rather than asking the vendor. Review whatever consumes the output as though the output were a user submission. Then list the supply chain: foundation provider, connectors, extensions. Most security teams we work with can add all five to their existing process in a single review cycle, and the first pass usually finds a capability nobody intended to enable. Teams wanting continuous quality monitoring alongside the security review will find continuous AI evaluation and risk control relevant, and our AI-enhanced security services cover the operational side. Bring your current review checklist to a free strategy call and we will mark what it is missing.