Ninety percent of your licences are assigned and a third of them were last used in July. That gap is the adoption problem, and no financial metric will surface it, because the spend looks identical either way. A CIO measuring AI adoption is asking whether the organisation is becoming able to use this, which needs depth of use, workflow coverage, abandonment cohorts and internal build capacity. Whether a particular deployment returned its cost is a separate question with a separate owner. Conflating the two produces a dashboard that satisfies finance and tells you nothing about capability.
The Five Adoption Signals Worth a CIO’s Attention
- Depth of use, not seat count. One person running a multi-step workflow weekly is a different signal from ten people asking one-off questions.
- Workflow coverage against the workflows that matter. Count the processes genuinely handled, not the tools deployed.
- The abandonment cohort. People who used it for three weeks and stopped know something your active users do not.
- Internal build capacity. How many people can create or modify a workflow without an external party is the capability number.
- Variance between teams. A healthy average across an unhealthy distribution is the most common reporting failure at this level.
Written for CIOs and IT directors at 50 to 500 employee firms two or three quarters into an AI program.
Why Seat Counts Mislead at Exactly This Stage
Seat counts mislead because assignment is an administrative act and use is a behavioural one, and the gap between them widens quietly after the launch quarter. We are usually brought in when a CIO suspects the reported numbers are flattering and cannot prove it. They almost always are, and the proof takes an afternoon of querying rather than a project.
Segment by Depth Before Reporting Anything
Split users into three bands: those who have never used it beyond a first session, those who use it occasionally for single questions, and those who run repeatable multi-step work through it. Report the three separately, permanently. The third band is the one that creates value and changes behaviour, and it is usually far smaller than the headline suggests. Watching band three grow month over month is the single most informative adoption view we produce for a CIO, and it is invisible in any report that counts active users as one number. Similar segmentation logic applies to workspace rollouts generally, covered in measuring the success of a secure workspace implementation.
Count Workflows Covered, Not Tools Deployed
Before deployment, list the processes you intended AI to handle. Afterward, count how many are genuinely running through it, meaning the old manual path is no longer the default. That ratio is your coverage. Firms frequently deploy three tools and cover one process, which reads as three successes in a tool-centric report and one in an honest one. Coverage also tells you where to invest next, because an uncovered process that was on the original list is a known gap rather than a new idea.
The Trained-But-Not-Using Population
Track the number of people who completed training and then did not use the tool within two weeks. This population is a training-design signal rather than an enthusiasm problem: it usually means the training taught the interface rather than the job, so nobody left knowing which of their own tasks to bring to it. The fix is redesigning training around three real tasks from the attendee’s actual week, which is more work to prepare and considerably more effective, as the adoption argument in training your team for effective adoption sets out.
The Metrics That Predict the Next Quarter
Three measures consistently predict where the program will be in three months, and none of them appears in a standard vendor dashboard.
Time to Second Use
Measure the gap between a person’s first use and their second. A short gap means the first use answered something real and they came back. A long gap, or none, means the first use was curiosity. Aggregate this across a cohort and you have a leading indicator that moves weeks before active-user counts do, which is enough warning to change enablement while it still matters. We watch it per team rather than per organisation, because the teams with long gaps are where the workflow fit is wrong.
Abandonment Cohorts and What They Tell You
Identify everyone who used the tool regularly for a period and then stopped, then ask a handful of them why. This is the most valuable twenty minutes available to a CIO in this program and almost nobody spends it. The answers cluster: the output needed too much correction, the workflow did not fit how the job actually runs, a colleague said something dismissive, or an early error destroyed trust. Each has a different remedy and only one of them is a model problem. The structured version of quality checking underneath this sits in continuous AI evaluation and risk control.
Internal Build Capacity
Count the people in your organisation who can create or meaningfully modify an AI workflow without external help. For most mid-sized firms the honest answer starts at zero or one, and that number determines whether the program compounds or stalls when the implementation partner leaves. Growing it from one to four changes the trajectory more than any additional licence, and it is a hiring and training decision rather than a technology one. Where several workflows interact, the coordination knowledge needed is the subject of multi-agent systems and coordinating AI agents.
The Shadow Usage You Are Not Counting
Every adoption figure a CIO reports counts the sanctioned tool, and in most organisations a meaningful amount of the actual AI use is happening somewhere else, on personal accounts, inside a browser extension somebody installed, or through a feature switched on inside software you already license. That population does not appear in your dashboard and it is not a rounding error. Two consequences follow for measurement. First, a low sanctioned-adoption number may be describing a preference rather than a rejection: people are using AI, they are just not using yours, usually because the sanctioned path is slower to reach or more restricted than the alternative. Second, the reason they chose the alternative is the most useful adoption finding available, because it names the friction precisely. We surface this by asking rather than by monitoring, since a survey that reads as enforcement produces silence and a conversation framed as improving the official tool produces detail. Where the answer is that the unofficial route is simply faster, the response is to fix the official one rather than to block the unofficial one, because blocking moves the usage further out of sight without changing the demand.
Reporting This to People Who Are Not You
A CIO’s adoption numbers get read by an executive team and a board, and the reporting choices determine whether the program keeps its support through the awkward middle quarters.
Show the Distribution, Always
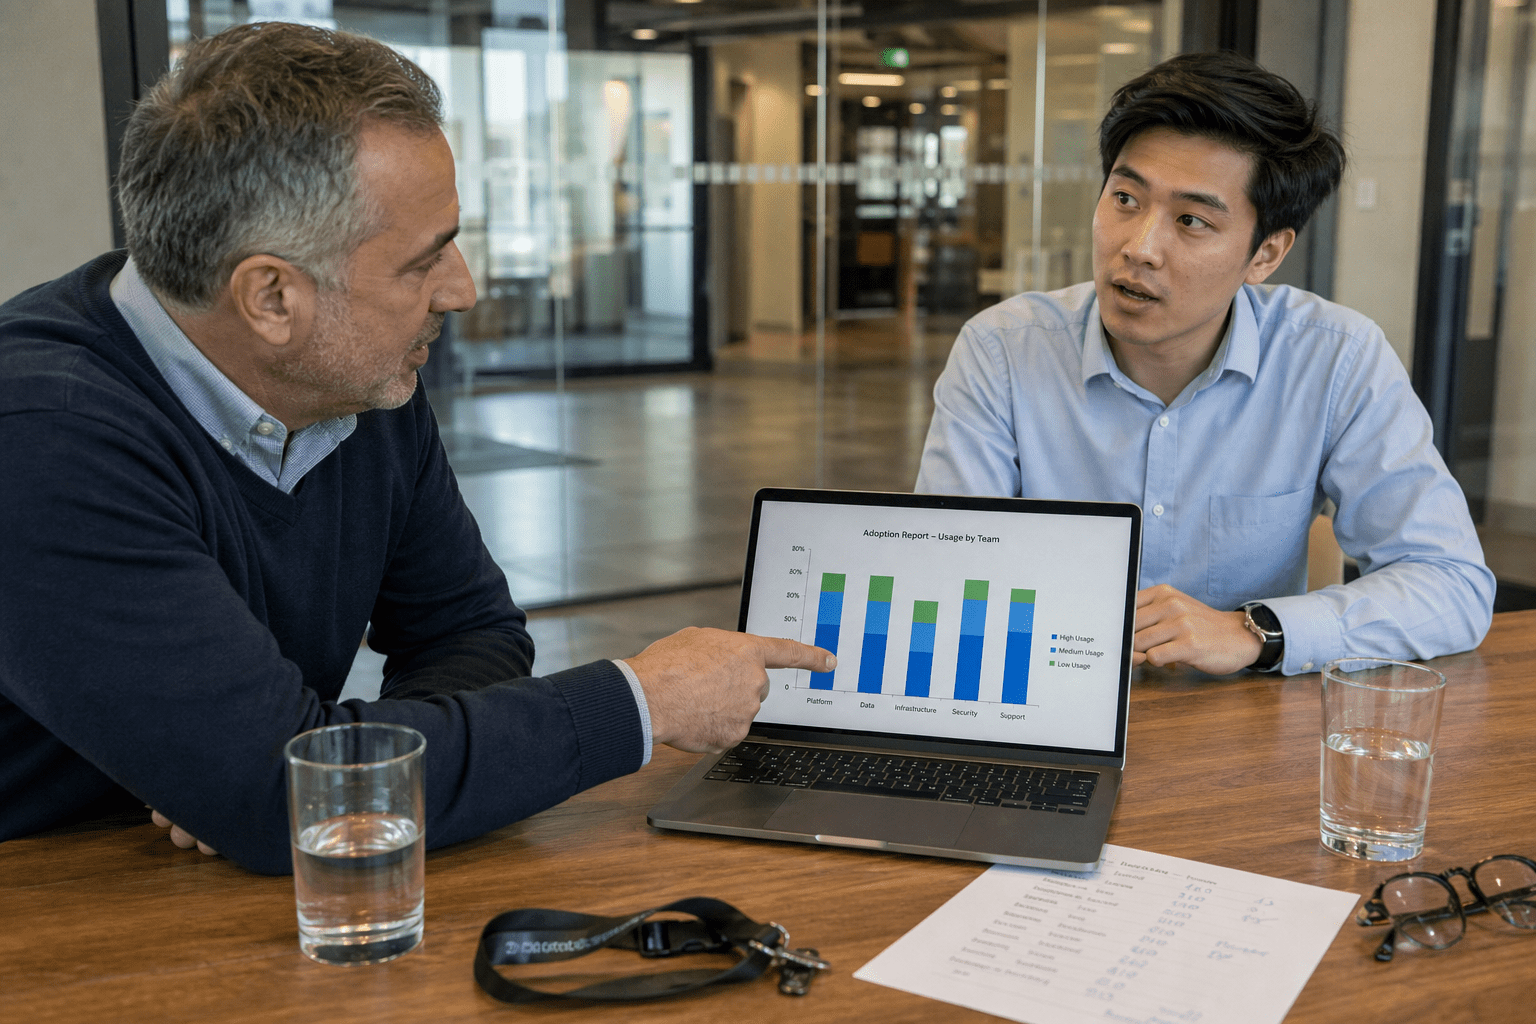
Report per-team figures rather than an organisational average, because the average conceals the exact thing you need to act on. A company at fifty percent depth-band-three adoption might have finance at eighty and operations at fifteen, and those two need entirely different interventions. Executives read distributions perfectly well when given them, and a flat average invites the wrong conclusion in both directions. The same principle governs service reporting generally, which we work through in measuring the success of a managed IT partnership.
Name the Maturity Stage Honestly
Describe where the program actually is: experimenting, a workflow or two in production, several in production with internal capacity, or embedded in how work is done. Naming the stage sets expectations correctly and prevents the mismatch where leadership believes the organisation is embedded while IT knows two workflows carry everything. CIOs in regulated sectors face this most acutely, since the adoption story and the assurance story are read together, a tension covered in secure workspace adoption for healthcare CIOs.
Report the Things That Are Not Working
A report with no problems in it reads as incomplete to any experienced executive, and it costs credibility precisely when you later need to report something genuinely difficult. Name the team with low adoption and say what you are doing. Name the workflow that was abandoned and why. This is easier when the metrics were agreed in advance, because the conversation is then about a number everyone accepted rather than about the choice of number.
Agree the Numbers Before the Program Needs Them
Metrics chosen while a program is healthy get accepted; metrics introduced once it is struggling get argued about, and the argument consumes the quarter you needed for the fix. Agree the set at the start with whoever will read it: the three depth bands, workflow coverage against the original list, time to second use, internal build capacity, and the per-team distribution. Write down what each one means precisely enough that two people querying the data independently land on the same figure, since most reporting disputes at this level are definitional rather than substantive. Then hold the set steady for at least three quarters. Changing metrics between reports destroys the only thing that makes them useful, which is comparability, and it reads to an experienced board as looking for a flattering number. If a measure turns out to be wrong, retire it explicitly and say why rather than quietly replacing it. The discipline costs nothing and it is what lets you report a bad quarter without the conversation becoming about the reporting.
Frequently Asked Questions
What is the most useful single AI adoption metric?
The proportion of users running repeatable multi-step work through the tool, reported separately from occasional and lapsed users. It is the band where behaviour has genuinely changed, it is usually much smaller than headline active-user figures suggest, and its growth rate is what predicts whether the program compounds.
How is adoption measurement different from measuring ROI?
They answer different questions for different owners. ROI asks whether a deployment returned its cost and belongs with finance. Adoption asks whether the organisation is becoming able to use AI, which is capability and behaviour. A program can show acceptable returns on two workflows while adoption is stalled everywhere else.
How often should a CIO review adoption numbers?
Monthly during the first three quarters, then quarterly once the pattern is stable. Monthly is frequent enough to act on a declining cohort while enablement can still change it, and infrequent enough that you are reading a trend rather than noise.
What does a healthy internal build capacity look like?
Several people across different teams who can create or modify a workflow without external help, rather than one specialist. One person is a dependency and a resignation risk. The number matters more than the depth of any individual’s skill, because distribution is what lets the capability survive normal staff turnover.
Should we survey users about AI adoption?
Sparingly, and target the lapsed users rather than the active ones. Active users tell you what they like; the people who stopped tell you what broke. A handful of short conversations with abandoners produces more actionable information than a wide satisfaction survey.
Who Is Behind This Guidance
Our team works alongside IT leadership at firms between 50 and 500 employees, and we are usually in the room when the second-quarter adoption numbers turn out to be softer than the launch suggested. That is a normal point in the curve rather than a failure, and the CIOs who navigate it well are the ones who instrumented depth and capability from the start instead of counting seats. We build the reporting with the leadership team rather than handing it over, because a metric somebody else chose is one nobody defends in a difficult meeting. Matt Rosenthal, Mindcore’s CEO, keeps the practice focused on making technology progress legible to the people accountable for it, which for a CIO means numbers that survive a board’s follow-up question. That is the standard this is written to.
Instrument Capability, Not Consumption
Split your users into never, occasional and repeatable bands and report the three separately from now on. Count workflows genuinely covered against the list you started with. Track time to second use per team as your leading indicator, and spend twenty minutes talking to people who stopped. Count how many people can build a workflow without outside help and set a target for that number. Report distributions rather than averages, name the maturity stage plainly, and include what is not working. Most CIOs we work with have more adoption than their reporting shows in one or two teams and considerably less across the rest, and seeing that split is what turns a stalled program into a targeted one. If you want the measurement designed alongside the next deployment, our enterprise AI integration practice covers both, and teams needing the underlying support model strengthened first should look at our IT support services. Bring last month’s usage export to a free strategy call and we will band it with you.