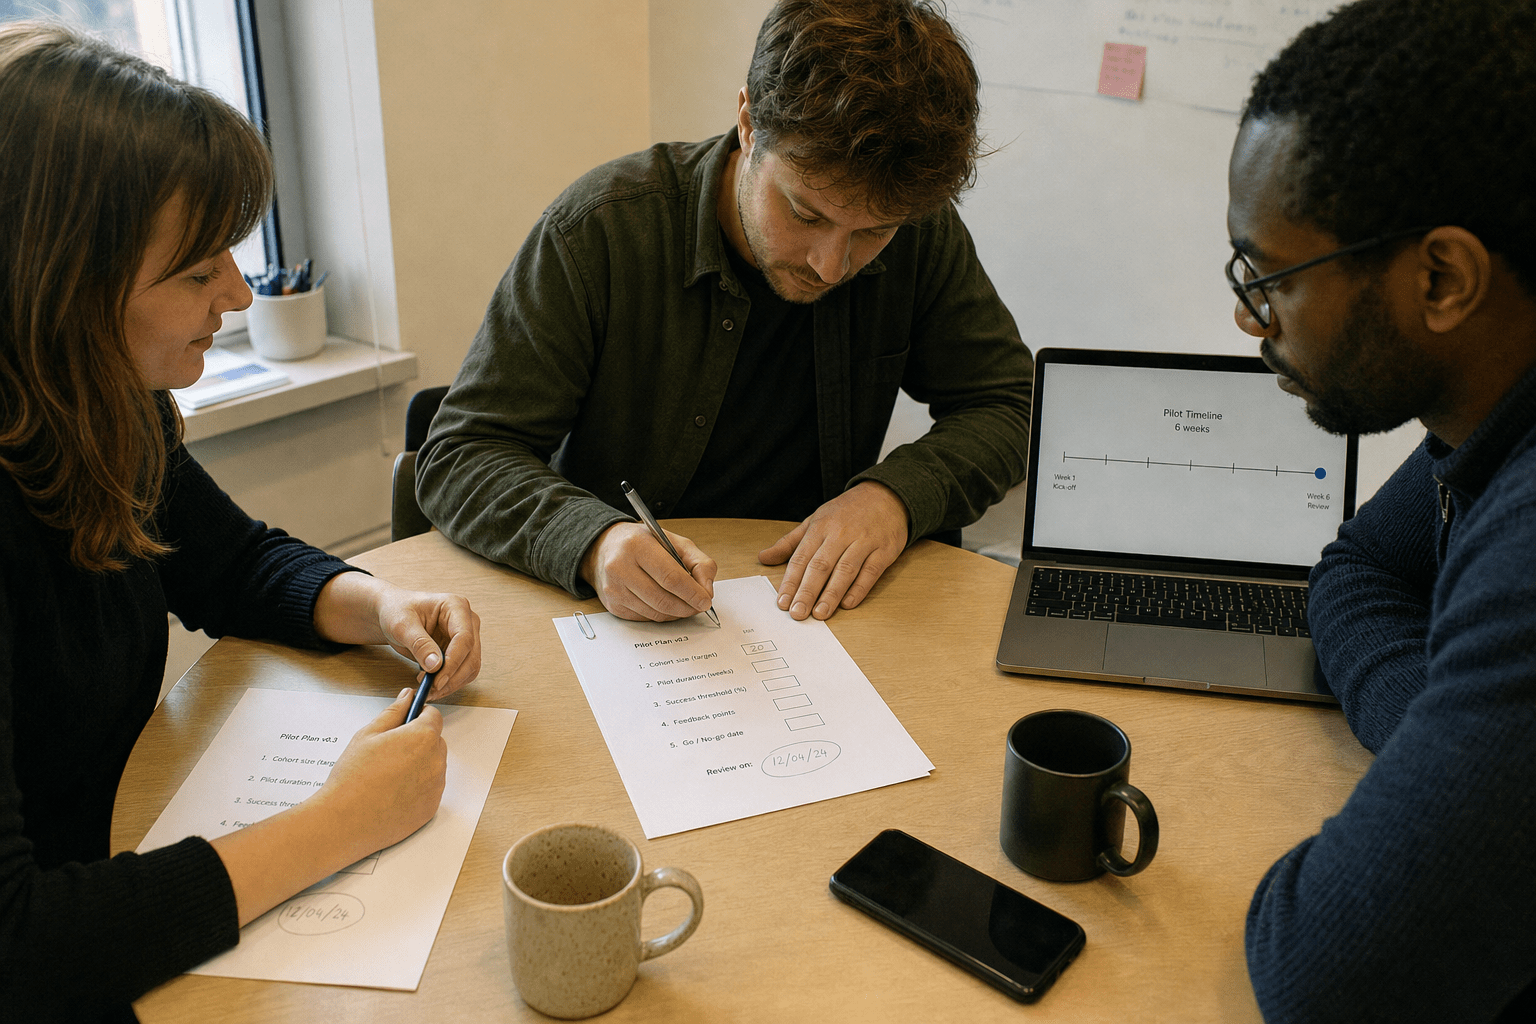
Ask what result would end your pilot and you usually get silence, then a sentence about learning. That is the whole problem. A pilot is an experiment with a decision attached, and one without a written stopping rule cannot produce a decision, so it produces an extension instead. The structures that work in 2026 fix three things before anyone touches a tool: which question this pilot answers, what result means adopt and what result means stop, and the date the decision gets made regardless of what the data looks like.
The Five Things That Make a Pilot Decidable
- One question per pilot. Feasibility, value, and operability are three separate experiments and mixing them answers none of them.
- Criteria written before the first run. Thresholds chosen after seeing results are a rationalisation, and everyone in the room knows it.
- A stop condition, not just a success condition. If no outcome would end this, you are not piloting, you are deploying slowly.
- A decision date that holds. Pilots without an end date become permanent, unsupported, and quietly load-bearing.
- Scope small enough to finish. A pilot spanning three teams and two systems is a project wearing a pilot’s budget approval.
Written for IT directors and innovation leads at 50 to 500 employee firms running their first or second AI pilot.
Pilot Purgatory and How Firms End Up There
Pilot purgatory is the state where a tool has been in trial for eleven months, a dozen people depend on it, nobody has approved it, and it sits outside support, procurement and security review. It is the most common outcome we encounter, and it happens through drift rather than decision.
Nobody Wrote the Ending
A pilot with no defined end has no natural moment to conclude, so it continues by default. Each month the question of whether to formalise it competes with more urgent work and loses. The tool meanwhile accumulates users, and the longer that runs the harder the eventual conversation becomes, because stopping now removes something people rely on. Write the decision date at the start and put it in a calendar that somebody owns. It is a two-minute act that prevents the most expensive failure mode in this category.
Unsupported Dependency Is the Real Cost
A tool in permanent pilot is usually outside the normal support path, which means nobody is on call for it, nobody patches it, and the licence sits on somebody’s expense claim. When it breaks the answer is that it was only a pilot, which is true and no comfort to the twelve people who now cannot do their work. This is the same exposure shape covered in are AI agents safe for enterprise use, arriving through the back door rather than through procurement, and our IT support services exist partly because informal dependencies keep becoming formal problems.
Extension Is a Decision Too
Where a pilot genuinely needs longer, extend it explicitly with a new date and a stated reason rather than letting it roll. An extension somebody approved is governance; an extension nobody noticed is drift. The distinction sounds procedural and it is what separates a program that can report its position from one that cannot. Project discipline of this kind is what our project management practice brings to technology work generally.
Pick One Question Per Pilot
Most failed pilots asked three questions at once and answered none cleanly, because the design that answers one well is wrong for the others.
Feasibility Pilots Are Short and Narrow
A feasibility pilot asks whether the technology can do this at acceptable quality on your data. It needs a small sample, a clear quality bar, and no organisational change whatsoever. Two to three weeks is usually enough, and the output is a number with a judgement attached rather than a business case. Running it with production integration and user training attached wastes weeks on scaffolding for something that may fail on the first question. Structured quality measurement here is the subject of continuous AI evaluation and risk control.
Value Pilots Need Real Users and Real Baselines
A value pilot asks whether the capability produces a business result worth paying for. That requires real users doing real work, a before-state captured beforehand, and long enough for novelty to wear off, which is typically six to eight weeks rather than two. The common error is running a value pilot on enthusiastic volunteers, which measures the ceiling rather than the expectation. Pick a representative group including at least one sceptic, and treat their experience as signal rather than as an obstacle.
Operability Pilots Ask Who Runs It on a Wednesday
The third question is whether your organisation can operate this: who fixes it, who updates the prompts, who reviews quality, what happens during holidays. This is the question that determines the second year and the one almost nobody pilots. Run it by having your own team operate the tool without vendor assistance for a defined period and recording what they could not do. The skills question underneath is covered in training AI agents for technical teams.
Writing Criteria You Cannot Argue With Later
Pre-registered criteria are the difference between a pilot and a demonstration, and the discipline is borrowed directly from experimental practice for good reason.
Numbers Before Data
Write the thresholds before the first run: what accuracy, what time saving, what error rate, what adoption. The number will feel arbitrary and that is acceptable, because an arbitrary threshold chosen in advance is more honest than a precise one chosen afterward. Where you genuinely cannot set a number, that is a signal the question is not yet sharp enough to pilot, and another week of definition will save a month of ambiguous results.
Define the Stop Condition Explicitly
State what result would mean stop, in the same document, at the same time. A pilot where every plausible outcome leads to continuing is not a test. This is the clause that gets resisted most and matters most, because the sunk cost of a pilot is small and the sunk cost of a half-deployment is not. Naming the stop condition early also makes stopping socially possible later, which is the actual barrier in most organisations.
Name Who Decides
One person, named at the start, with the authority to adopt or stop. Committee decisions on pilots default to extension because extension requires no agreement. The decider should have budget authority and enough distance from the build to say no without it reading as a personal defeat. Where several workflows or teams are involved, the coordination questions in multi-agent systems and coordinating AI agents apply to the governance as much as the technology.
What a Pilot Cannot Tell You
Knowing the limits of the instrument matters as much as running it well, and three questions are structurally outside what any pilot answers.
Novelty Inflates Every Early Result
People try harder with something new, and the first fortnight of any pilot is measuring enthusiasm alongside capability. The effect is real, it is large, and it decays on a timescale of weeks rather than days, which is the main argument for running value pilots past the six-week mark rather than declaring victory at three. Where a short pilot is unavoidable, discount the early numbers explicitly in the write-up rather than presenting them as the expected steady state, because the gap between week two and week ten is where most disappointed executives were originally misled.
Small Samples Hide the Rare Case
A pilot on two hundred items will not contain the awkward edge case that appears once in a thousand and causes the complaint. That is a property of sampling rather than a flaw in your design, and the honest response is to say which failure modes the pilot could not have surfaced rather than implying a clean run proves their absence. For anything touching customers or regulated decisions, pair the pilot result with a deliberate list of unexplored failure modes and a monitoring plan for the first months of production. The evaluation practices that catch these later sit in continuous AI evaluation and risk control.
Second-Year Economics Are Not in Scope
A pilot measures capability and early value at pilot volume. It says almost nothing about consumption cost at full volume, the maintenance burden after the third model change, or what happens when the person who built it moves on. Those belong in the adoption decision as separate estimates, flagged as estimates, rather than being implied by a successful trial. A pilot that succeeds on its own terms and a deployment that succeeds economically are two different claims, and conflating them is how a good pilot becomes a disappointing second year.
Frequently Asked Questions
How long should an AI pilot run?
Two to three weeks for feasibility, six to eight for value, and a defined operating period for operability. Longer than that without a decision point is drift rather than rigour, because the additional data rarely changes the answer and the organisational dependency keeps growing.
What if the pilot results are ambiguous?
Treat ambiguity as a result and apply your pre-registered rule, which for most organisations should default to stop rather than extend. An ambiguous result usually means the question was not sharp enough, and sharpening it and running a short second pilot beats extending a muddy one.
Should pilots use production data?
Feasibility pilots should use realistic data with appropriate controls, because synthetic data hides exactly the messiness that determines whether the tool works. Get the data-handling agreement in place before rather than after, since retrofitting permissions to a running pilot is where most privacy problems in this category originate.
Who should be in a value pilot group?
A representative mix including at least one sceptic and at least one person whose workflow is genuinely awkward. Enthusiastic volunteers measure the ceiling. The awkward workflow is the one that tells you whether this generalises beyond the easy case.
How do we avoid pilot purgatory?
Write the decision date and the stop condition before the pilot starts, give one named person the authority to decide, and put the date in a calendar somebody owns. Extensions are fine when explicit and approved; the failure is the pilot that continues because nobody scheduled the conversation.
Who Is Behind This Guidance
Our team runs technology pilots with firms between 50 and 500 employees, and we are frequently asked to help formalise something that has been in trial for the better part of a year with a dozen quiet dependencies on it. That experience shaped the emphasis here on endings rather than beginnings, because the beginning is the part organisations already do well. We insist on a written stop condition before starting, which occasionally costs us the work and consistently produces better outcomes for the clients who accept it. Matt Rosenthal, Mindcore’s CEO, keeps the practice focused on making technology decisions defensible to the people accountable for them, and a pilot without a decision rule cannot produce a defensible one. That is the standard this is written to.
Write the Ending Before the Beginning
Decide which single question this pilot answers and resist adding the other two. Write the success thresholds and the stop condition before the first run, accept that the numbers will feel arbitrary, and name one person with authority to call it. Put the decision date in a calendar that somebody owns. Keep the scope small enough to finish and pick a user group with a sceptic and an awkward workflow in it. Then, when the date arrives, actually decide, including the possibility of stopping something that half works. Most organisations we meet have run two or three pilots and concluded none of them formally, which is why the third one is harder to fund than the first. If you want the pilot designed with its decision rule attached, our enterprise AI integration practice starts there, and teams working on the enablement side will find training your team for effective adoption useful alongside it. Bring your current pilot to a free strategy call and we will help you write the ending it is missing.