Patch rings are the structure that turns an unreadable stream of advisories into a routine a two-person team can actually run. The volume is the problem. Dozens of vulnerabilities are confirmed as exploited in the wild in any given month, arriving on nobody’s schedule, alongside monthly vendor releases that can carry several hundred fixes at once. No small business can assess that individually, and the ones that cope are not reading more carefully. They have decided in advance which patches skip the queue, which wait for the window, and which machines go first, so that almost every advisory is handled by a rule rather than by a meeting.
The Five Decisions That Make Up a Cadence
Make these once and most of the volume becomes routine.
- What triggers an emergency patch. Confirmed exploitation in the wild is the usual line, and it should be the only one.
- How many rings you run. Two is enough for most small businesses, three if you have a genuinely critical production system.
- How long a patch sits in each ring. Days, not weeks, and written down rather than judged each time.
- Who composes the pilot ring. By application coverage rather than by who volunteers.
- What your rollback is. Per ring, decided in advance, because a bad patch at 8am is when nobody wants to be improvising.
Our patch management guide covers the process gaps that sit underneath all of this.
Why Patch Rings Beat Reading Every Advisory
A rule applied consistently outperforms a judgment made under time pressure on incomplete information, and patching is a near-perfect example of that trade. Reading advisories properly means understanding each vulnerability, whether your configuration is affected, and whether exploitation is realistic against your environment. Done well that is a specialist job and an hour per significant item. Done badly, which is how it is done in most businesses, it produces a decision based on the severity number and a vague sense of whether the product sounds important. A ring structure with a written trigger replaces that with something that runs whether or not anybody had time this week, and our note on implementing a vulnerability management process covers the scanning half that feeds it.
Use Confirmed Exploitation as the Only Emergency Trigger
Out-of-band patching should be reserved for vulnerabilities confirmed as exploited in the wild, because that is the one signal that reliably separates the handful that matter from the hundreds that do not. Most published vulnerabilities are never exploited. The small number that are tend to be catalogued quickly and publicly, which gives a small team a free prioritization feed maintained by people with far better visibility than you have. Everything else waits for the scheduled window. The objection is that a critical remote code execution flaw on an internet-facing system deserves urgency even without confirmed exploitation, and that is a fair carve-out worth writing into the rule explicitly. Keep it to that one addition, because every further exception dilutes the trigger until everything is urgent and nothing is.
Size the Rings for a Team That Has Other Work
Two rings, a pilot of twenty or thirty machines and then everything else, is the right structure for most small businesses, and adding rings adds delay rather than safety. Each ring costs you a soak period, so a three-ring structure with three days per ring means production waits nine days for a fix. That is defensible for a stable estate with a critical system and indefensible for a business where the main risk is not patching at all. Start with two, measure how often the pilot catches something, and add a ring only if it earns its place. There is a reasonable argument for more rings in environments with genuinely irreplaceable systems, and the test is whether your pilot has ever actually caught a problem. If it has not in a year, you have too many rings rather than too few.
Composing the Pilot Ring Properly
The pilot only works if it runs the software that would break, which means composing it by application coverage rather than by volunteers. This is where most ring structures quietly fail. The pilot gets populated with IT staff and a few enthusiastic early adopters, all of whom run a similar, modern, well-maintained set of applications. The patch sails through, goes to production, and breaks the practice management system that only the clinical team uses, or the accounting package nobody in IT has ever opened. The pilot proved that the patch works on machines nobody was worried about.
List Your Applications, Then Pick People to Cover Them
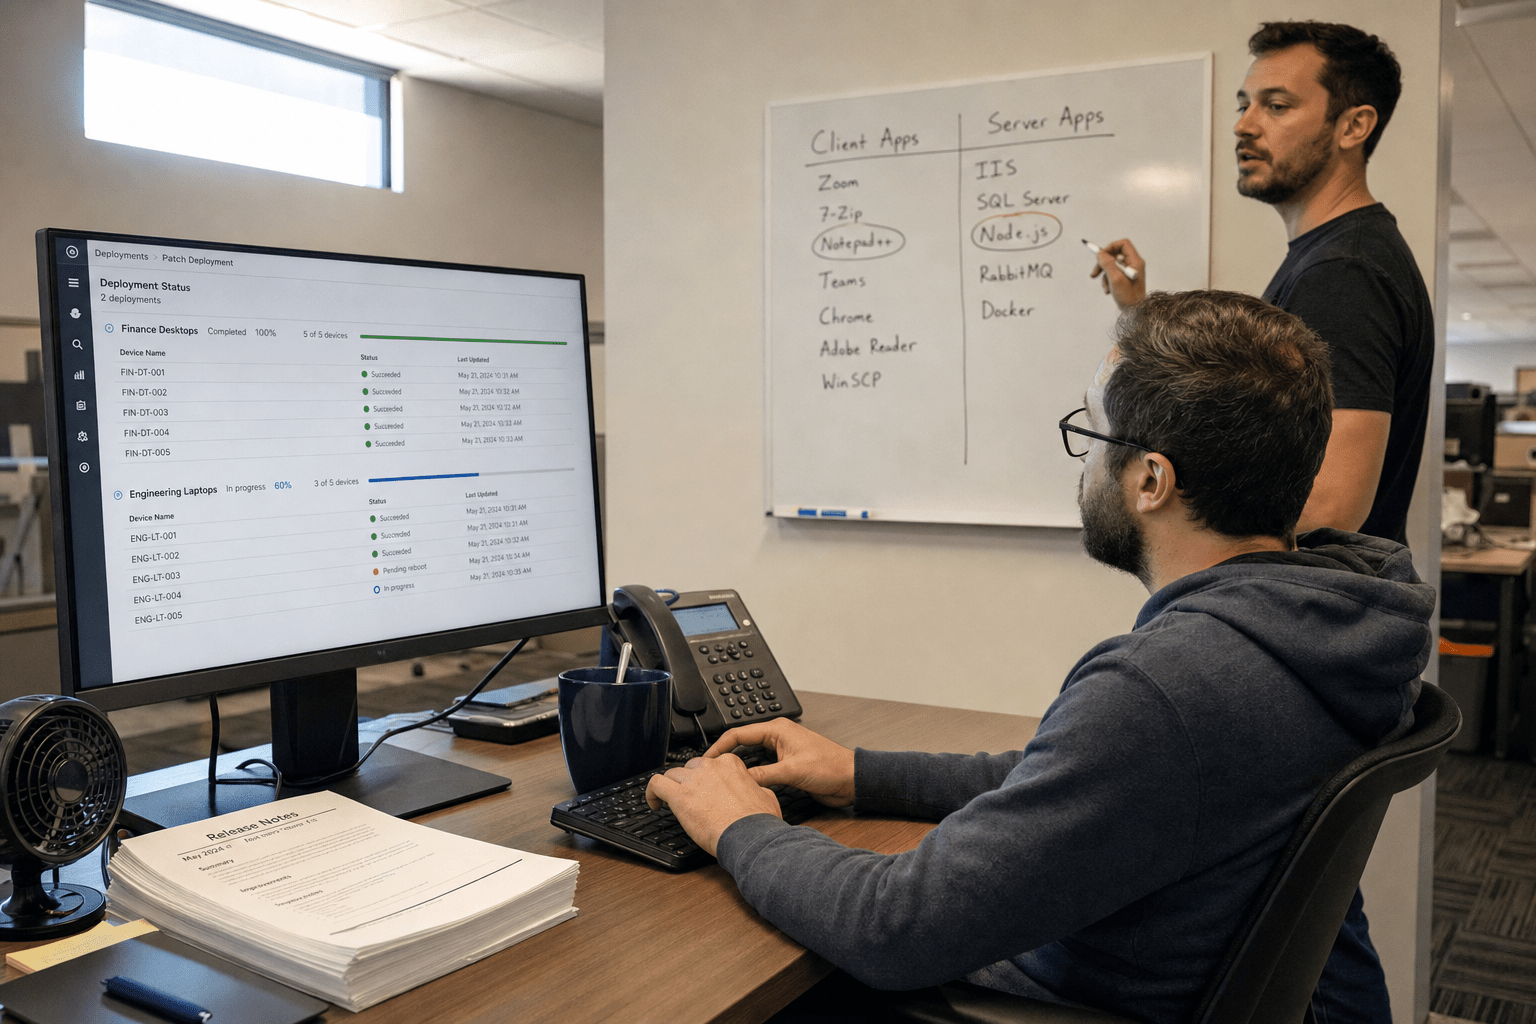
Work from an application list to a person list rather than the other way around, which usually produces a pilot of a dozen well-chosen machines rather than thirty arbitrary ones. Write down the software the business genuinely depends on, then identify at least one active daily user of each and put their machine in the pilot. Tell them why they are in it and what to report. That last part matters, because a pilot user who experiences a small problem and works around it silently has removed the entire value of the ring. Our note on testing, patching and vulnerability scanning covers the verification side. The counterargument is that putting a busy finance manager in the pilot risks disrupting the person you can least afford to disrupt during month end, which is true and is handled by scheduling around the cycle rather than by excluding the role.
Make Reporting a Problem Easier Than Tolerating One
A pilot only generates signal if the people in it can report an issue in seconds, so give them a direct route rather than your normal ticket queue. A named person, a dedicated channel, anything that takes less effort than living with a slightly slower application for a week. The failure mode here is entirely human: people do not report small degradations because reporting feels disproportionate, and small degradations are precisely the early signal a pilot exists to catch. Ask the pilot group directly after each cycle rather than waiting for reports, at least until the habit is established. The objection that this is heavy process for a small business is fair, and it takes one message in a group chat: anything odd this week.
The Emergency Path and the Way Back
The rule you will need at the worst moment is the one for going backward, so decide it while nothing is broken. For workstations, rollback usually means an uninstall and a reboot, which is slow across a fleet but well understood. For servers it more often means a restored snapshot, which requires that somebody took one before patching, which requires that it is part of the procedure rather than a good intention. Write both down per ring. Then decide who is authorized to invoke a rollback without convening anybody, because the cost of waiting for a decision is measured in the same hours as the outage.
Take the Snapshot Automatically, Not Diligently
Anything that depends on somebody remembering to snapshot before patching will eventually be skipped on the day it mattered, so it belongs in the automation rather than in the runbook. Most virtualization and backup platforms can take a pre-patch checkpoint as a scheduled step. Where that is not available, tie it to the patch job rather than to a person. And set the retention deliberately, because snapshots consume storage and get cleaned up by whoever is freeing space, sometimes before you know whether the patch was fine. A week is usually enough. Our note on the hidden line items in vulnerability management cost covers the storage and tooling side, since this is one of the places the real budget goes.
Write the SLA Down, Even If It Is Only for You
A written commitment on how quickly each class of patch reaches production converts an intention into something measurable, and measurable is what survives a busy quarter. Something simple works: confirmed-exploited flaws within seventy-two hours, everything else within the monthly window, critical internet-facing issues treated as exploited. If you have an IT provider, that belongs in your agreement with them and is worth checking against what the contract currently says, which our explainer on what an SLA should contain covers. If you handle it internally, write it anyway and report against it quarterly. The honest objection is that a target you miss is a record of missing it, and some managers would rather not create that. Our experience is that the number gets better once somebody is looking at it, which is the entire argument for measuring anything, and our vulnerability management guide and our comparison of scanning against penetration testing cover what to measure alongside it.
Decide What Falls Outside the Rings Entirely
Rings govern the machines your management tooling reaches, and every business has a population it does not, so name that population rather than discovering it during an incident. Network hardware, printers and scanners, the machine attached to a piece of equipment, anything a vendor manages on your behalf, and personal devices used for work all sit outside a typical deployment tool. None of them appear in your patch reporting, which means a dashboard showing full compliance is describing a subset of your estate without saying so.
Handle that population separately and deliberately: a list, an owner, and a review cadence measured in months rather than days, since the update mechanisms are manual and the release frequency is lower. What you are protecting against is not the unpatched printer itself so much as the quiet assumption that your reporting is complete. The objection is that this is a second process for a handful of devices nobody has ever had trouble with, and that is exactly the reasoning that leaves an internet-facing appliance running firmware from three years ago. Keep it proportionate by scoping it to devices that are reachable from outside or that hold credentials, and leave the rest to the annual hardware review.
Frequently Asked Questions
How many patch rings should a small business run?
Two is right for most: a pilot of twenty or thirty machines and then everything else. Each additional ring adds delay before production is protected, so add a third only if your pilot has genuinely caught problems.
What should trigger an out-of-band patch?
Confirmed exploitation in the wild, plus critical remote code execution on internet-facing systems. Keep the list that short, because every exception makes the trigger less meaningful.
How long should a patch soak in the pilot?
Days rather than weeks. Long enough to cover a normal working cycle for the applications in scope, which for most businesses means three to five days.
Who should be in the pilot ring?
Daily users of each application the business depends on, chosen by application coverage rather than by volunteering. A pilot made of IT staff tests software that was never at risk.
What if we have no capacity to run any of this?
Write the trigger rule and the two rings anyway, since the structure is what lets a small team act consistently. If it still cannot be sustained internally, it is a well-defined thing to hand to a provider with a measurable commitment attached.
Who You Are Taking This Advice From
Mindcore runs patch cycles for businesses where the same person handles the help desk, the backups, and the vendor calls, which is why we build two rings rather than five and write the trigger down in one sentence. We compose the pilot from application coverage rather than volunteers, tie the pre-patch snapshot to the job instead of to somebody’s memory, and report against the commitment quarterly so it stays real, and the guidance above comes from cycles we operate rather than from a framework document. Matt Rosenthal, who leads Mindcore, keeps the firm focused on routines that survive a bad month, which in patching means a rule simple enough to follow when nobody has time to think. You know which applications cannot break. Our job is to make sure the pilot actually runs them.
Your Next Move on Your Patch Cycle
Write one sentence defining what skips the queue, and make it confirmed exploitation plus critical internet-facing remote code execution, because that single sentence removes most of the weekly decision-making. Then build the pilot properly: list the applications the business genuinely depends on, find a daily user of each, and put those machines in the ring, telling them plainly what to report and to whom. Check whether a pre-patch snapshot happens automatically on your servers, and if it depends on somebody remembering, move it into the job this week. Write down how fast each class of patch should reach production and, if a provider handles it, compare that against what your agreement actually commits them to. None of this requires new tooling, and it converts a stream of dozens of exploited vulnerabilities a month from something nobody can keep up with into something that mostly handles itself. The firms that fall behind here are rarely the ones without a product. They are the ones where every advisory is still a decision. If you want help sizing the rings and setting the trigger, book a free strategy call and we will start with your application list.