The best AI document tools for loan underwriting are the ones that can show their work. Extraction accuracy matters and every serious product now handles a clean W-2 or a standard bank statement well. What separates a usable tool from an unusable one in lending is traceability: if an extracted figure feeds a debt-to-income calculation that produces a decline, somebody has to be able to explain that decline to the applicant, to a regulator, and to an auditor sampling files two years from now. A confident number with no provenance is not a time saving in a regulated decision. It is a liability with a fast turnaround.
Where Underwriting Time Actually Goes
Underwriting cycle time is consumed by conditions and exceptions rather than by reading documents. Five patterns account for most of it:
- Conditions are cleared one round trip at a time. Each request to the borrower costs days, and requests are issued as they are discovered rather than batched.
- Self-employed income takes an analyst. Two years of returns, a K-1, and add-backs are judgement work that a standard extraction model does not touch.
- The same document arrives in six formats. A bank statement can be a clean PDF, a bank export, a photograph, or a scan of a printout, and quality varies by lender channel.
- Stale documents expire mid-process. A pay stub valid at application ages out before closing, and nobody tracked the clock.
- Exceptions are undocumented. An overridden condition is approved verbally, and the file cannot later show why.
Extraction speeds up the reading, which was never the slow part. The tools worth buying attack the condition loop and the expiry clock. Related document-handling capability is covered in our piece on document processing tools.
Extraction Quality Where the Documents Are Difficult
Extraction is where products are demonstrated and where the differences are narrower than the marketing suggests. Our team probes three areas: the document types that actually cause trouble, what the tool does when it is unsure, and whether it validates figures against each other rather than reporting each in isolation.
The Documents That Break Standard Extraction
Difficult document handling is the honest measure of an extraction product. In favour of current tooling: standardised forms, typed statements, and clean digital PDFs extract at accuracy levels that genuinely reduce analyst time, and that is a large share of a conforming residential file.
Where it degrades: photographed documents at an angle, statements with transaction tables spanning pages, handwritten amendments to a lease, and business returns with attached schedules whose figures matter more than the face of the form. Self-employed and small business lending is disproportionately made of these. We ask vendors to run their model against fifty of our client’s own hardest files, not a sample set, and we look specifically at the multi-page table case, which is where silent errors concentrate because a table split across a page break often loses rows without any signal. Vision-based approaches have improved this materially, as our write-up on visual document processing discusses.
Uncertainty That Surfaces Instead of Averaging Away
Confidence reporting is the property that decides whether extraction is safe to build on. Supporting per-field confidence: a tool that reports low confidence on a specific figure and routes it for verification lets you automate the ninety percent that is certain while protecting the decision from the ten percent that is not. That is a genuinely good deal.
Against products that report a single document-level score: a document that is ninety-four percent confident overall tells you nothing about whether the one number driving the decision was the uncertain one. Worse, some tools normalise ambiguous readings into a plausible value rather than flagging them, so a smudged 3 becomes an 8 with no indication anything was inferred. We test for this deliberately by submitting deliberately degraded documents and checking whether the output distinguishes read from guessed. A tool that never says it is unsure is not confident, it is silent, and in a credit file that distinction is the whole risk.
Cross-Checking Figures Against Each Other
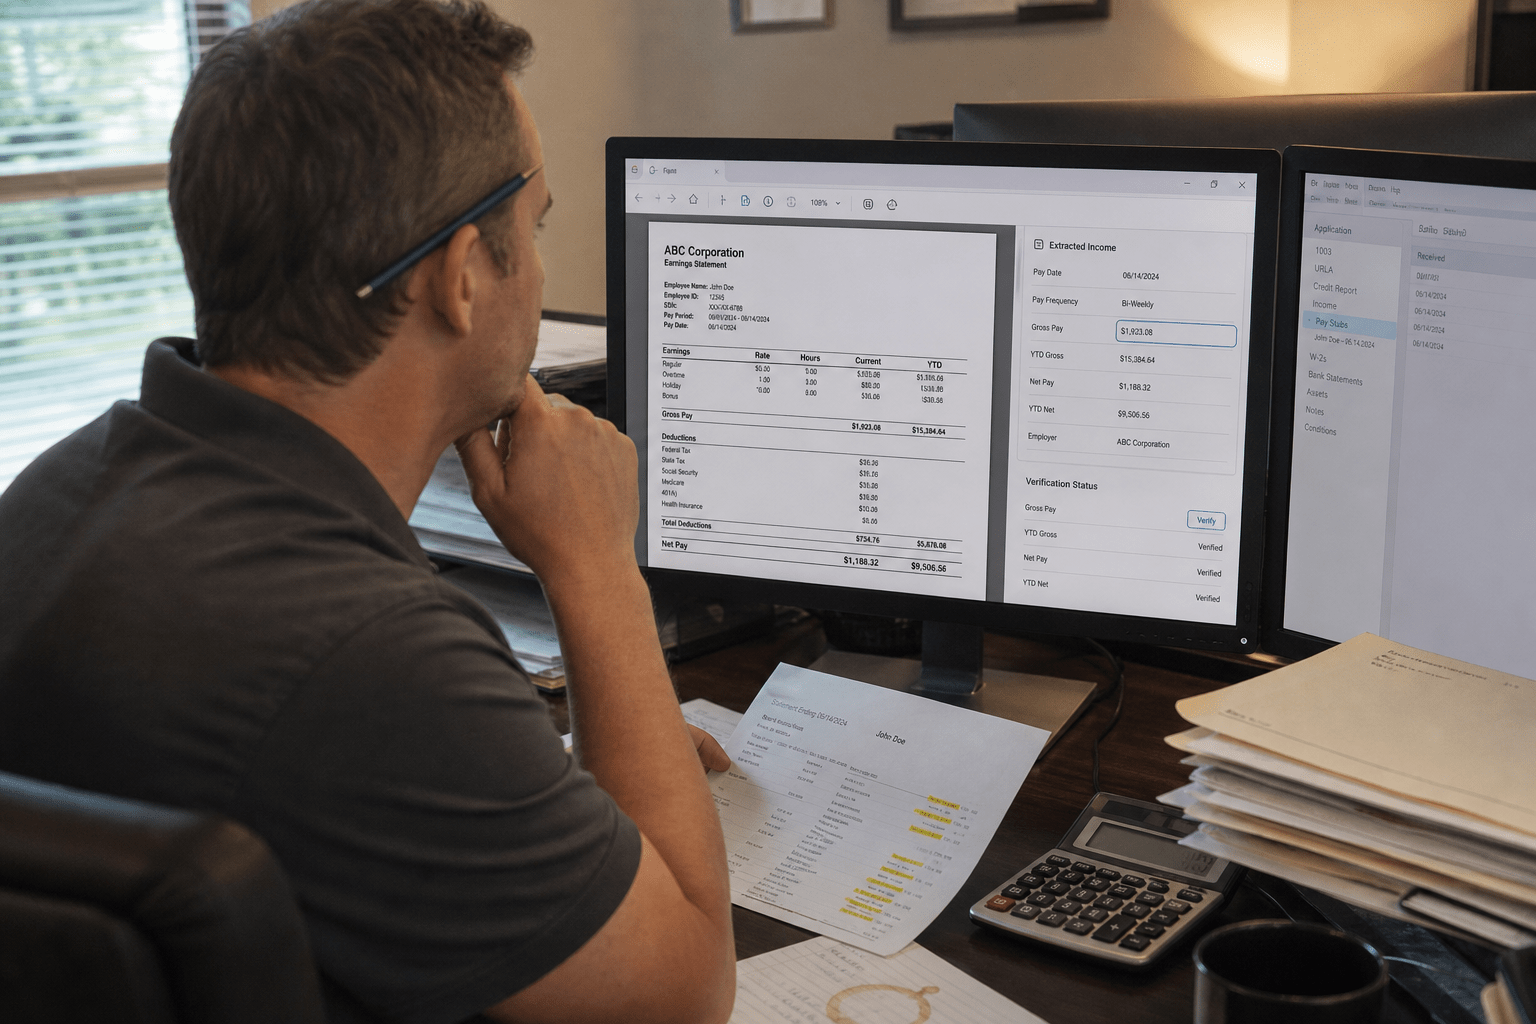
Internal validation is an underrated capability that catches both errors and fraud. Arguing for it: income stated on the application, income on the pay stub, deposits on the bank statement, and income on the tax return should be consistent, and an agent comparing all four flags the mismatch immediately rather than at a later review. Most extraction products report fields; fewer reconcile them.
The limitation is that legitimate mismatches are common. Commission income, a recent raise, a second job started mid-year, and irregular self-employment draws all produce genuine inconsistencies. A tool that treats every mismatch as suspicious generates noise that trains underwriters to dismiss its output. We configure reconciliation to flag with a suggested explanation and require a recorded disposition rather than blocking, which keeps the signal useful and the file documented.
The Regulatory Constraint That Shapes Everything
Lending decisions are regulated in ways that document processing in other industries is not, and this constraint should drive the product selection rather than being addressed afterward.
Explaining a Decline in Terms an Applicant Can Act On
Adverse action explainability is a legal requirement and a design constraint. In favour of transparent pipelines: when a decline traces to a specific figure from a specific document, the notice writes itself and it is accurate. The applicant learns something actionable, and the file supports the reasoning if challenged.
Against opaque scoring anywhere in the chain: a model that produces a risk score from a bundle of features cannot generate a specific reason, and a post-hoc explanation generated separately from the actual decision is not the reason, it is a plausible narrative. That distinction is one regulators have grown considerably less patient with. Our practical rule is that any component influencing an approval or decline must be inspectable, and anything opaque is confined to prioritising work queues rather than shaping outcomes. Formalising where a model may and may not influence a decision is the substance of an AI risk assessment.
Fair Lending and the Proxies You Did Not Intend
Disparate impact risk deserves explicit attention, because it arises without intent. Supporting careful design: a document tool extracting facts is comparatively low risk, since it reports what the paperwork says rather than inferring anything about the applicant.
The risk enters when extraction feeds automated decisioning that learns from historical outcomes. Address data, employer name, and even document format correlate with protected characteristics, and a model trained on past approvals learns whatever pattern those approvals contained, including the ones nobody intended. Firms handling this well monitor outcomes by segment continuously rather than validating once at deployment, and they keep the extraction layer separate from the decision layer so each can be audited on its own terms. Governance of that separation belongs alongside your general IT risk assessment practice.
Retention, Because Files Get Sampled Years Later
Evidence retention is the requirement people plan for last. Arguing for building it in: an examiner sampling a file from two years ago wants the document, the extracted values, the confidence at the time, and any human override with its reason. A tool that stores only the current state of a loan cannot produce that.
The counterargument is cost and complexity, and it is real, because retaining document images with a full extraction audit trail is not free. Our position is that this is not optional in lending and should therefore be a selection criterion rather than a later project. Verify retention duration, whether the audit trail survives a system migration, and whether you can export it in a usable form if you change vendors. A trail you cannot take with you is a trail you will lose exactly when a portfolio sale or a platform change makes it matter.
Batching Conditions Instead of Discovering Them One at a Time
Condition batching is where the cycle-time gain actually lives, and it is a sequencing change more than a technology one. In favour of upfront analysis: if a tool reads the whole submitted package on arrival and produces the full list of missing and insufficient items at once, the borrower receives a single request rather than four over three weeks. Each avoided round trip removes days, and the borrower experience improves in a way that shows up in pull-through rates.
Against expecting completeness on day one: some conditions cannot be known until earlier ones are cleared. A gift letter is only required once the deposit source is identified, and an appraisal condition depends on a report that has not been ordered. A tool promising a single definitive condition list at intake is describing a simpler product than lending actually is.
The realistic target is two rounds rather than one, and that is still a large improvement on the four or five many files take. We measure rounds per file as the primary metric for this capability, because it is unambiguous, the borrower feels it directly, and it cannot be improved by working faster on the wrong thing. Document expiry belongs in the same mechanism: a tool that knows a pay stub ages out on a given date can request the refresh alongside the next round rather than triggering a fifth one on its own.
How We Score AI Document Tools for Loan Underwriting
We score AI document tools for loan underwriting on four questions. Does it report confidence per field and route uncertain values rather than normalising them. Does it reconcile figures across documents and require a recorded disposition on mismatches. Can every value that influences a decision be traced to its source document and page. Does it retain that trail for your full examination window in an exportable form. Extraction accuracy on clean documents, the headline in every demonstration, is close to uniform across serious products and is not where the decision should be made.
There is also a sequencing point worth stating. Firms tend to buy extraction first and discover the condition loop is where the delay was, which is process automation rather than document AI, and sits closer to our intelligent process automation and broader AI agents work. The build-versus-buy framing is in our breakdown of automation tooling.
Frequently Asked Questions
Can AI fully automate underwriting decisions?
For narrow, highly standardised products some lenders do automate within tight parameters. For anything involving self-employment, unusual collateral, or a marginal file, the decision needs a human who can defend it. The regulated obligation to explain a decline does not transfer to a vendor.
How accurate is extraction on bank statements?
Very good on clean digital statements and noticeably worse on photographed or scanned ones, particularly where transaction tables cross page boundaries. Test against your own worst channel rather than a vendor sample, since intake quality varies enormously by how applications reach you.
What about self-employed borrower income?
Extraction handles the forms and does not handle the judgement. Add-backs, distributions versus salary, and the treatment of a partial year still require an analyst. Expect help with assembling and reading the documents, not with deciding what the income is.
Does using AI create fair lending exposure?
Extracting facts from documents is low risk. Exposure grows when outputs feed decisioning trained on historical outcomes, since proxies for protected characteristics enter through address, employer, and other correlated fields. Monitor outcomes by segment continuously rather than validating once.
How long do we need to keep the audit trail?
Match your examination and record retention window, which is commonly several years, and confirm the trail survives a vendor change. Retention that exists only inside a platform you might leave is not retention you can rely on.
Who Is Behind This Advice
Our team works with lenders on the infrastructure and controls around these platforms rather than on credit policy, which shapes what we notice. The recurring finding is that the extraction pilot succeeds and the programme stalls at the audit question, because nobody asked during selection how a decision would be reconstructed later. That question is cheap to answer before a contract and expensive afterward.
We have also seen the quieter failure, where a tool normalised an ambiguous figure rather than flagging it and nobody knew for months. Nothing alerted, the files looked complete, and the error surfaced during a routine quality review. Confidence reporting is not a nice-to-have in this setting, it is the control.
Matt Rosenthal leads Mindcore and pushes for systems that can still be explained a year later, which in regulated work is the difference between a tool you can keep and one you have to unwind.
Buy for Traceability, Not for Extraction Accuracy
The takeaway is worth applying before your next platform decision. In lending, the binding constraint on document AI is not how accurately it reads a pay stub but whether every figure influencing an approval or decline can be traced back to its source and explained years later. Test extraction against your own hardest files, especially multi-page transaction tables and photographed documents, and check specifically whether the tool distinguishes a value it read from one it inferred. Require per-field confidence and route uncertain figures rather than accepting a document-level score. Reconcile income across the application, the pay stub, the statements and the return, flagging with a suggested explanation and a recorded disposition rather than blocking. Keep the extraction layer separate from any decisioning layer so each can be audited alone, and monitor outcomes by segment on an ongoing basis. Confirm the retention window and that the audit trail exports if you change vendors. Do that and you get the analyst hours back without acquiring an explanation problem that surfaces during an examination. If you want a second opinion on whether your current stack could reconstruct a decision from two years ago, book a free strategy call and we will trace one file with you. A broader view of where these tools sit next to everyday software is in our piece on AI assistants versus classic office tools.