The best AI tools for RFP and proposal drafting are only as good as the answer library behind them, and most firms do not have one. What they have is a folder of past submissions, which is a different thing. Point a drafting tool at that folder and it will produce fluent, well-structured responses asserting a certification that lapsed in March, a headcount from two years ago, and a client reference who has since churned. That is a worse failure than a blank page, because a blank page gets written and a confident paragraph gets skimmed. Before evaluating any product, work out who owns the source answers and how often they are checked.
Why Proposals Are Late Even When Somebody Starts Early
Proposal deadlines are missed for reasons that have little to do with writing speed. Five patterns show up in the bid teams we work with:
- The bid decision is made too late. A week disappears deciding whether to respond, and the response is then compressed into the remaining time.
- Subject matter experts are the bottleneck. The technical answer needs the one engineer who is on a client site all week, and no amount of drafting capacity helps.
- The security questionnaire arrives as a surprise. A two hundred question annexe lands with the RFP and nobody assigned it, so it gets done last and badly.
- Answers are copied from the wrong bid. The most recent submission is not the most relevant one, and copying from it imports assumptions about a different client.
- Formatting eats the last day. Page limits, mandated templates, and font requirements consume the hours that should have gone into the win themes.
A drafting tool addresses the fourth and part of the third. It does nothing for the first two, which are usually the larger share. Knowing that before you buy prevents the disappointment that follows a tool doing exactly what it promised.
The Answer Library Decides Everything
Answer library quality is the whole game, and it is a content operations problem rather than a technology one. Our team looks at three things: whether canonical answers exist and are owned, how the tool handles a question the library does not cover, and how stale content is detected before it ships.
Curated Answers Versus a Folder of Old Bids
Curation is the difference between a library and an archive. In favour of building a real one: a set of canonical answers, each with an owner and a review date, gives the tool a single correct version of every recurring response, so the same question gets the same accurate answer whoever is drafting. Two hundred well-maintained answers cover the large majority of what recurring RFPs ask.
Against the shortcut everyone takes: pointing the tool at historical submissions is faster to set up and imports every error those submissions contained, including the ones that were wrong at the time and never caught. It also blends contradictory answers, since the same question was answered differently across three bids, and the model will produce a confident synthesis of positions your firm never held. We build the initial library by extracting recurring questions from the last ten RFPs, writing one correct answer for each with a named owner, and accepting narrower coverage in exchange for accuracy. The parsing side of that extraction is well handled now, as our piece on document processing tools discusses.
What Happens When the Library Has No Answer
Gap behaviour separates trustworthy products from dangerous ones. Supporting tools that flag rather than fill: when a question falls outside the library, the correct output is an explicit gap assigned to a named expert, not a generated paragraph. A tool that always produces something reads as more capable in a demonstration and is the one that puts an invented claim into a document with your signature on it.
The counterargument is that generated drafts for unknown questions save the expert time, and there is something to that when the output is clearly marked as unverified and routed for approval. The distinction that matters is whether the draft can reach the submission without somebody accepting it. We configure a hard rule that no unverified answer is included in an export, which some tools support natively and others cannot express at all. That single capability question eliminates a surprising number of products.
Catching Stale Content Before It Ships
Staleness detection is the maintenance capability that decides whether the library still works in two years. Arguing for automated review cycles: answers carry a review date and an owner, the tool surfaces anything overdue, and certifications with expiry dates are checked against those dates rather than against memory. Insurance limits, certification status, headcount, and client references are the four that go stale fastest and are exactly the four that get scrutinised.
Against relying on the mechanism alone: review reminders are ignored under deadline pressure like every other reminder, and a library where two thirds of answers are overdue provides false comfort. We attach the review to a person per subject area rather than to the bid team collectively, and we report the overdue percentage to whoever owns bids, because an unowned metric is not managed. The pattern is the same one that governs any content-driven automation, discussed in our comparison of AI agents and traditional automation.
Security Questionnaires Deserve Their Own Treatment
Security annexes have become the largest single component of many technology RFPs, and they behave differently from the rest of the document. They are factual rather than persuasive, they are frequently reused verbatim across bids, and a wrong answer has consequences beyond losing the deal.
Answering Accurately Rather Than Favourably
Accuracy discipline matters more here than anywhere else in a proposal. In favour of a controlled approach: security answers become contractual representations in many procurements, and an overstated control is a misrepresentation you may have to defend during an incident. A library where each security answer traces to evidence, and where the answer is written by whoever owns the control, produces submissions that survive scrutiny.
Against the pressure everyone feels: the temptation to answer yes to a control that is mostly in place is strong when the alternative is losing points on a scored questionnaire. Our position is that a partial answer with a remediation date scores better than people expect and eliminates the risk entirely, because evaluators are used to reading qualified answers and are not used to being lied to. Establishing what your controls actually are, so the answers are grounded, is what a cyber security audit produces.
Reusing Answers Across Frameworks Without Losing Meaning
Cross-framework mapping is where these tools genuinely shine. Supporting it: the same underlying control gets asked about differently by an ISO-aligned questionnaire, a SOC-aligned one, and a client’s bespoke spreadsheet, and a tool that maps a canonical answer onto each phrasing removes a large volume of tedious rework.
The limitation is that mapping is not equivalence. A question about encryption at rest and a question about key management overlap and are not the same, and a mapping that treats them as interchangeable produces an answer that reads as responsive and does not address what was asked. Evaluators notice, and it costs points precisely because it looks like a copied response. We review mapped answers for any question the library has not seen in that exact form, which is more work than the tool implies and far less than answering from scratch.
Chasing Experts Without Becoming Annoying
Subject matter expert throughput is the constraint no drafting tool removes, and how you manage it decides whether deadlines hold. In favour of automating the chase: an agent that assigns each gap to a named expert with a deadline derived from the submission date, then reminds them proportionally as it approaches, removes the bid manager’s least popular job. It also produces a record of who was asked and when, which turns a recurring problem into a visible one.
Against automating it thoughtlessly: experts are usually senior, busy, and not part of the bid team, and an automated reminder cadence that treats them like a ticket queue produces resentment and slower responses. We tune the cadence to two touches before escalation and make the first one carry everything needed to answer, including the question, the previous answer if one exists, and the exact deadline. An expert who can respond in four minutes from their phone usually does.
The larger fix is upstream and worth saying plainly. If the same three experts are the bottleneck on every bid, the answer is to convert their recurring answers into library content they approve once, not to chase them faster. Each conversion permanently removes a dependency, and after two or three bid cycles the chase list is short enough to manage by hand.
How We Score AI Tools for RFP and Proposal Drafting
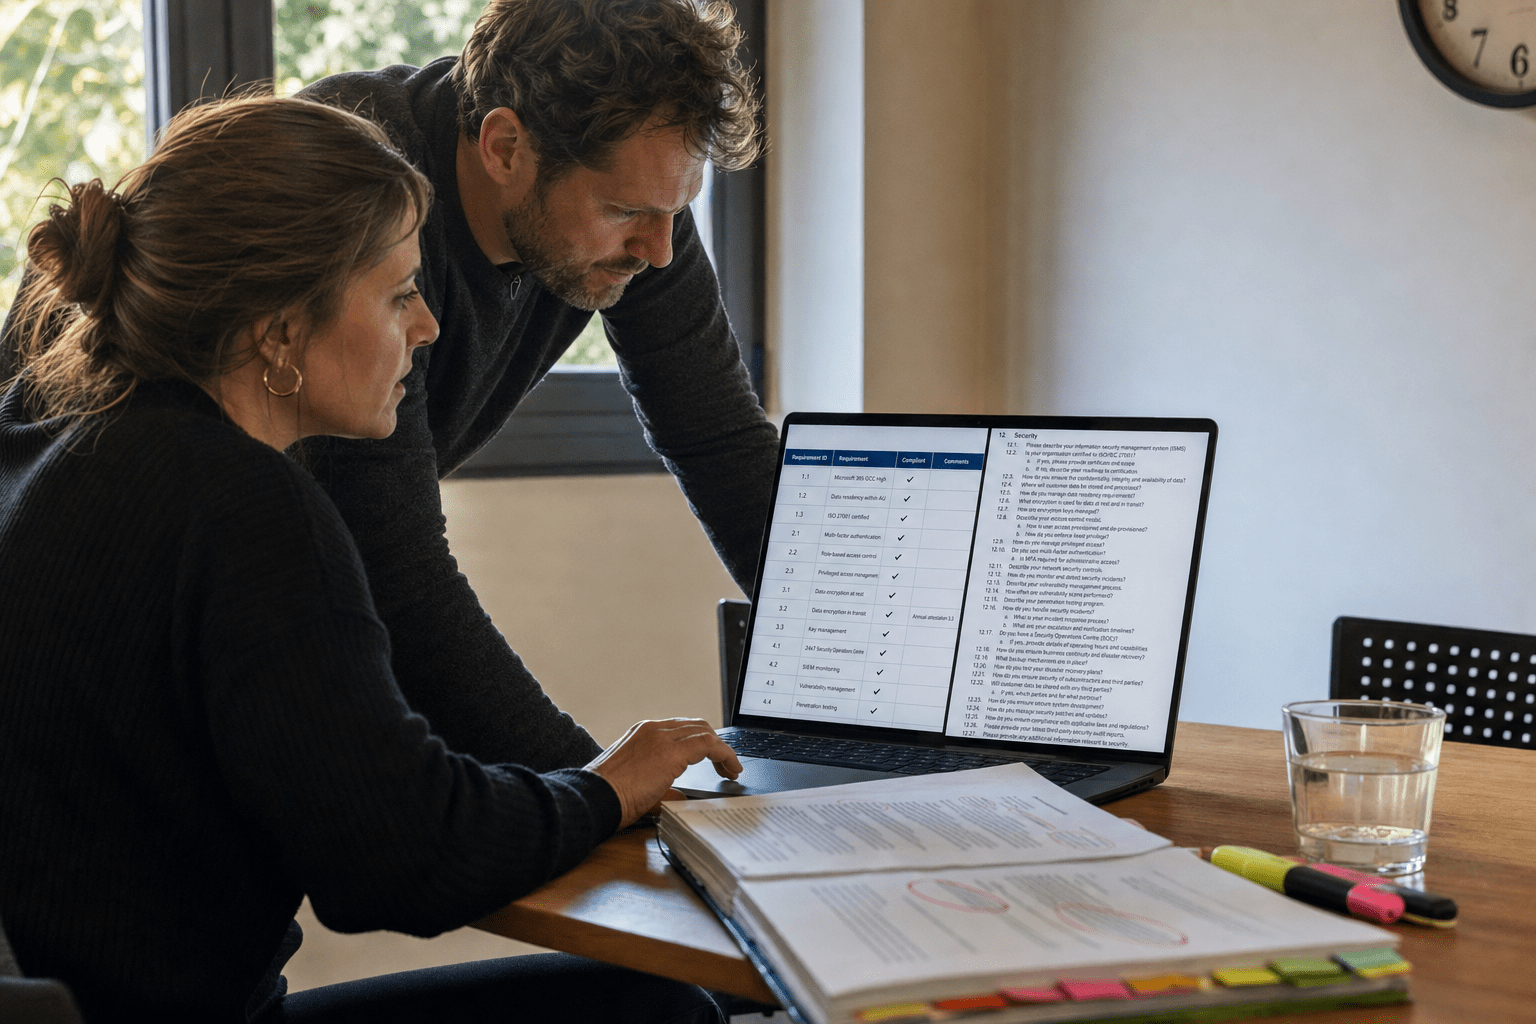
We score AI tools for RFP and proposal drafting on four questions. Does it hold curated answers with owners and review dates, rather than indexing a folder of past bids. Can it be prevented from exporting an unverified answer, as a hard rule rather than a warning. Does it produce a compliance matrix mapping every requirement to where it is addressed, since that is what evaluators check first and what disqualifies submissions. Does it respect the mandated template and page limits natively, because reformatting on the last day is where the hours actually go.
Drafting fluency, which is what demonstrations showcase, is not a differentiator any more. Every serious product writes acceptable prose. The differences are in library governance and export control, which are unglamorous and decide whether the tool is an asset or a liability. Fitting it into how bids actually move is standard enterprise AI integration and intelligent process automation work, described under our AI agents services.
Frequently Asked Questions
Will AI writing make our proposals sound generic?
It will if the library is generic. The differentiating content in a bid is the win theme and the client-specific reasoning, which stays human work. Tools handle the recurring factual sections, which is where the volume is and where sounding distinctive was never the point.
How large does an answer library need to be?
Around two hundred curated answers covers most recurring questions for a firm bidding regularly. Extract them from your last ten submissions rather than trying to anticipate what might be asked, and expand when a genuine gap appears twice.
Can these tools handle the security questionnaire?
They handle the reuse and the cross-framework mapping well. They should not be trusted to answer a control question the library has not covered. Route those to whoever owns the control, and require evidence behind each answer.
What about page limits and mandated templates?
Check this explicitly before buying. Some products export into a client template cleanly and some produce content you then reformat by hand, which removes much of the saving. Ask to see an export into a template you supply rather than one of theirs.
Does this help with the bid or no-bid decision?
Only indirectly, by making it cheaper to respond. The decision itself needs commercial judgement about fit and win probability. If your problem is responding to too many unsuitable RFPs, a drafting tool will help you produce more losing bids faster.
Who Is Behind This Advice
Our team completes security questionnaires as a respondent and reviews them as an assessor of other people’s suppliers, which is an unusual vantage point. Reading them from the evaluation side changed how we advise clients to answer: qualified, evidenced answers stand out favourably, and confident blanket claims invite the follow-up questions nobody wants during a competitive process.
We have also watched a firm deploy a capable drafting tool over an uncurated archive and submit a proposal citing a certification that had lapsed. Nobody was careless. The paragraph read well, it matched what the firm believed about itself, and it was eighteen months out of date. That is the specific failure this technology introduces, and curation is the only defence against it.
Matt Rosenthal leads Mindcore and pushes for automation built on a maintained source of truth, because a fast system drawing on stale facts produces mistakes faster than a slow one.
Build the Library Before You Buy the Tool
The takeaway is worth acting on before your next bid cycle. Proposal automation delivers against a curated answer library and actively misleads without one, so start there: extract the recurring questions from your last ten submissions, write one correct answer for each, and give every answer a named owner and a review date. Insist that any tool you evaluate can be stopped from exporting an unverified answer as a hard rule, not a warning, and ask to see an export into your own client template rather than the vendor’s. Treat the security annexe as its own workstream, answer it accurately rather than favourably, and require evidence behind each control claim. Watch the overdue-review percentage and report it to whoever owns bids, since certifications, insurance limits, headcount and references are what go stale and what get checked. Do that and the recurring sections stop consuming the week, leaving the time for the win themes that actually decide the outcome. If you want a second opinion on whether your current answers would survive an evaluator reading them closely, book a free strategy call and bring your last security questionnaire. A wider view on where these tools fit alongside everyday software is in our piece on AI assistants versus classic office tools, and the build-versus-buy framing is in our breakdown of automation tooling.