The best AI agents for fraud detection are the ones whose decision authority matches the team that has to live with them. Detection rate is the number vendors lead with and it is rarely the binding constraint. In a finance function of two or three people, an agent that flags everything and decides nothing simply relocates the work: the fraud is still caught, and now somebody reviews forty alerts a week they do not have time for. An agent permitted to hold a payment pending verification catches more and introduces a new failure mode, where a legitimate supplier goes unpaid because a model was uncertain. Scope the authority first and the product comparison gets much simpler.
Why Fraud Alerts Stop Working in a Small Finance Team
Fraud detection fails in smaller organisations for operational reasons rather than analytical ones. Five patterns account for most of it:
- Alert review has no owner. The controller checks alerts when there is time, which means not during month end, which is when unusual payments are easiest to hide.
- Everything is unusual in a small dataset. A firm making thirty payments a month has no stable baseline, so novelty-based scoring flags routine business constantly.
- The costly frauds do not look anomalous. A changed supplier bank account on a familiar invoice for a normal amount passes every statistical test because it is statistically normal.
- Approval is a formality. Dual authorisation exists on paper, and the second approver clicks through because the first one already checked.
- Nobody records the outcome. Alerts are dismissed without a reason code, so the system never learns and nobody can tell whether it is working.
The last point compounds all the others. Without recorded outcomes there is no way to measure whether an agent is earning its place. Our piece on how SMBs lose money to cyber-enabled fraud covers the loss patterns that sit behind these alerts.
Deciding What an Agent Is Allowed to Do on Its Own
Decision authority is the design question, and it comes before any vendor conversation. An agent can observe and flag, it can gather evidence and assemble a case, it can require an extra verification step, or it can block an action outright. Those are four very different products with very different risk profiles, and most tools are sold without the distinction being made explicit. We map each one against what the client can absorb operationally before looking at detection quality at all.
Flag Only, and Who Actually Reads the Flags
Flag-only agents are the safe default and the most commonly abandoned. In favour: they cannot cause an operational incident. A false positive costs somebody two minutes, nothing is held, no supplier is inconvenienced, and the finance team stays in control of every decision. For a firm with genuine review capacity, this is the right starting posture and often the right permanent one.
Against, and this is the failure we see most: flag-only shifts the entire cost onto attention, which is the scarcest resource in a small team. Alert volumes that look modest on a slide are not modest to a controller closing the month. Within a quarter the alerts are being cleared in batches without real review, and the organisation now has a fraud control that produces evidence it was ignored, which is materially worse than not having it. Before choosing flag-only, we make somebody name the person who reads the queue and the day of the week they do it. If that question has no answer, flag-only will fail.
Verification Agents, Which Add a Step Rather Than a Judgement
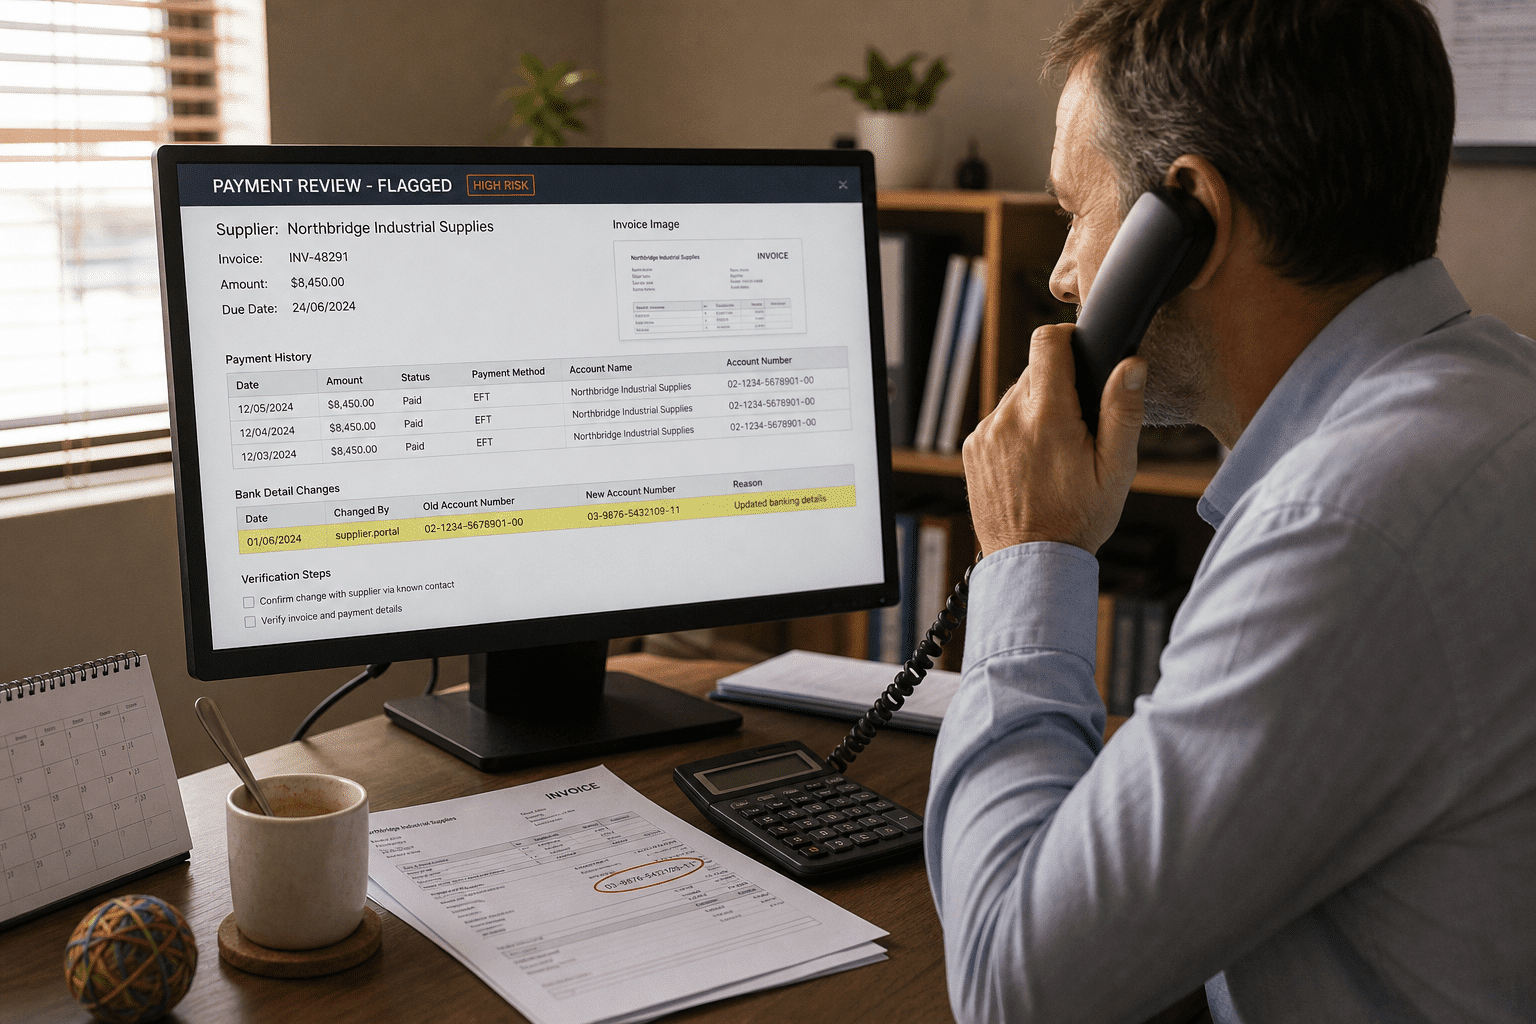
Verification agents occupy the most useful middle ground for payment fraud, because they act without deciding. Supporting them: an agent that detects a supplier bank detail change and automatically triggers a call-back to a known number, using a contact record it did not take from the invoice, addresses the single most expensive SMB fraud pattern without needing to be right about intent. It does not judge whether the change is fraudulent. It requires the verification that policy always said should happen and which, under time pressure, does not.
The counterargument is friction. Every genuine bank change now takes an extra day, and suppliers dislike it. Our position is that this is friction in exactly the right place, and the cost is bounded and predictable, unlike the loss it prevents. The pattern also survives a wrong model, which flagging does not: if the agent is over-sensitive you get extra call-backs rather than missed payments or ignored alerts. The details of that fraud pattern are in our write-up on wire transfer fraud in vendor payments.
Blocking Agents and the Risk You Are Accepting
Blocking authority is where most organisations should slow down. In favour: for high-velocity, low-value transaction fraud, such as card-not-present abuse in an online storefront, human review is not possible at the rate required, and an agent that declines transactions autonomously is the only workable design. If your fraud arrives in volume, blocking is not optional.
Against, for the payables case: a blocked supplier payment has consequences that propagate through a business in ways a declined card transaction does not. Terms get suspended, deliveries stop, and the finance team spends a day unwinding it. We advise clients to grant blocking authority only where three conditions hold: the volume genuinely defeats human review, the cost of a false block is small and reversible, and there is a fast override path that does not require the person who is on holiday. The broader risk framing sits in our piece on autonomous workflow agents, and formalising it is what an AI risk assessment is for.
What Fraud Agents Are Genuinely Better At Than Rules
Rules engines remain excellent at the frauds you have already seen, and this is worth saying plainly because agentic tooling is often sold as replacing them. It does not. A rule that holds any payment over a threshold to a new payee is cheap, explainable, and never drifts. Where agents add real value is in the work around the decision rather than the decision itself.
Assembling the Case File Before a Human Looks
Case assembly is the most underrated capability and the one that pays back fastest. Supporting it: when an alert fires, an agent can pull the payment history for that supplier, the invoice, the email thread that requested the change, the sender domain age, and whether the same bank detail appears on any other account, then present all of it as one summary. The reviewer makes the same decision they would have made, in four minutes instead of forty.
The limitation worth naming: the agent assembles what it can reach, and the most useful signal is often in a mailbox or a document store it has not been granted access to. An incomplete case file that looks complete invites a confident wrong decision. We require the summary to list what it could not retrieve, in the same view, because a reviewer who knows the email thread was unavailable behaves differently from one who assumes there was none. Finance-side automation of this kind is covered in our article on AI agents for finance.
Learning From Outcomes You Have to Actually Record
Outcome learning is the mechanism that separates a system improving over time from one slowly decaying. Arguing for it: an agent that captures why each alert was dismissed builds a picture of what normal looks like in your business specifically, and false positive rates fall measurably over a couple of quarters. This is where the machine learning framing earns its keep.
Against relying on it happening by itself: outcome capture is a habit change for the reviewer, and habits under deadline pressure lose. If closing an alert requires selecting a reason from a list, the list gets used for a month and then everything becomes other. We keep the taxonomy to four or five options, make it a single click, and review the distribution monthly, because a sudden spike in other is the early sign the control is decaying. Detection quality itself is well covered in our existing piece on AI powered fraud detection.
Explaining a Decision Months Later
Explainability matters here for a practical reason rather than a philosophical one: fraud decisions get revisited. A supplier disputes a held payment, an insurer asks why a transaction was released, or an auditor samples your controls and picks the one week you would rather they did not. In favour of tools that retain the reasoning: a record showing which signals fired, what the agent retrieved, and who overrode it converts an argument into a document. That record is also what lets you tell a genuine model failure from a reviewer who clicked through.
The counterargument is that model-based scoring is not naturally explainable, and vendors know it, so many produce a plausible narrative after the fact rather than a true trace. A generated explanation that was not the actual basis for the decision is worse than no explanation, because it is convincing and unfalsifiable. We ask whether the explanation is derived from the same features that drove the score, and if the vendor cannot answer that clearly, we treat the explainability claim as marketing.
For a smaller firm the workable minimum is modest: retain the input snapshot, the score, the threshold in force that day, and the human action taken. Those four fields answer almost every question that gets asked later, and they do not require the vendor to solve interpretability.
How We Score AI Agents for Fraud Detection
We score AI agents for fraud detection on four questions. What decisions can it make without a human, and can that boundary be configured per transaction type rather than globally. Does it assemble evidence, and does it disclose what it could not reach. Does it capture outcomes in a form that feeds back. Can you reconstruct, months later, why it acted on a particular transaction, because that reconstruction is what you will need if a decision is ever challenged.
Detection rate appears nowhere on that list, which surprises people. The reason is that published detection rates are measured on the vendor’s population, and your fraud profile is not theirs. A firm whose exposure is supplier impersonation gains nothing from a model tuned on card testing. Establishing your own profile first is ordinary AI readiness work, and the automation itself is intelligent process automation applied to a control function.
Frequently Asked Questions
Do we need an AI agent if we already have dual authorisation?
Dual authorisation stops opportunistic internal fraud and does poorly against supplier impersonation, because both approvers are looking at an invoice that appears genuine. An agent that verifies bank detail changes against an independent contact record addresses the gap the second approver cannot see.
How many alerts should a small finance team expect?
If the answer is more than a handful a week, the configuration is wrong for your size. Tune toward high-value, high-confidence patterns rather than broad anomaly scoring. A queue nobody finishes is a control that has already failed.
Should the agent be allowed to hold payments?
Only where a false hold is cheap and quickly reversible, and where somebody other than one named person can release it. For most payables functions, triggering a verification step is a better fit than blocking, because it survives the agent being wrong.
What data does a fraud agent need access to?
At minimum, payment history, supplier master data, and the invoice. The valuable additions are the email thread requesting any change and the domain age of the sender. If those are out of scope, the agent will assemble weaker cases and should say so on every summary.
How do we know it is working?
Track outcomes, not alerts. Count confirmed frauds prevented, false positives, and the share of alerts closed without a recorded reason. That third number is the health indicator, since it measures whether anybody is really reviewing.
Who Is Behind This Advice
Our team has implemented these controls in finance functions small enough that the controller is also the person who chases the supplier when a payment is held. That perspective shapes the advice: the elegant answer on a whiteboard is frequently the one that gets switched off in November because it made a difficult month worse. The deployments that survive are scoped narrowly, aimed at the two or three fraud patterns the business actually faces, and owned by someone with the authority to override them.
We have also seen the other failure, where a firm bought sophisticated detection and left it in flag-only mode with nobody assigned to the queue. Eighteen months of alerts, none reviewed. The tooling was excellent and the control did not exist.
Matt Rosenthal leads Mindcore and pushes for controls that a business will still be operating a year after they are installed, which usually means fewer of them, aimed better.
Scope the Authority Before You Compare Products
The takeaway is worth settling before you take a single vendor demonstration. Decide what an agent may do on its own, per transaction type, and write it down: observe and flag, assemble a case, require a verification step, or block. Name the person who reads the queue and the day they do it, and if that has no answer, choose verification over flagging. Grant blocking authority only where volume defeats human review and a false block is cheap to reverse. Require every case summary to disclose what it could not retrieve. Keep the outcome taxonomy short enough that it gets used, and watch the share of alerts closed as other, because that number tells you whether the control is alive. Do that and the product comparison narrows to two or three genuine candidates rather than a field of similar detection claims. If you want help mapping your own fraud profile before you shortlist anything, book a free strategy call and we will start with your payment history.