The best AI code review tools for security-conscious teams in 2026 are the ones developers have not muted. That sounds like a low bar and it is the one most of this category fails. Static analysis has been able to find injection flaws and unsafe deserialisation for twenty years. What changed is not detection capability, it is whether anyone reads the output.
The mechanism is simple and it is worth stating plainly, because it decides your purchase. A developer who opens ten findings and disagrees with eight of them stops opening findings. From that point the tool costs money, produces reports, and prevents nothing. A tool surfacing fewer issues that are consistently real prevents more defects in practice than a thorough one that has been filtered into a folder nobody reads.
Overview: five things that decide whether AI code review works
- False positive rate governs adoption. Measure it on your own repositories before you buy, not on a vendor benchmark.
- Where your source code goes is a contract question. Some tools send code to a third-party model, and your client agreements may already forbid that.
- Context-aware review beats pattern matching on the findings that matter. Business logic flaws are invisible to signature-based scanning.
- Pull request integration decides whether it is used at all. A finding raised at review time gets fixed; one in a weekly report does not.
- Fix suggestions need the same scrutiny as the code they replace. An accepted suggestion is code you now own.
Written for engineering leads, CTOs and technical owners at software teams of three to fifty developers, and for the businesses commissioning custom software who want to know what to ask for.
False positive rate is the number that predicts adoption
False positive rate predicts whether a tool is still in use in six months, and it is measurable before purchase. Take three repositories that represent your real work, run each candidate tool, and have a senior developer triage the findings into genuine, arguable and wrong.
The ratio you get is specific to your codebase, your language mix and your framework choices, and it will not match any published figure. A tool that performs well on a modern typed codebase can be noisy on a decade-old codebase with unusual patterns, and the reverse happens too.
Triage the sample properly, once
This is a few hours of a senior person’s time and it is the highest-value hours in the whole evaluation. Have them record not just whether a finding was real, but whether it was worth fixing, because those are different questions and the second one is what developers actually apply.
A finding that is technically correct and describes a code path that cannot be reached in your deployment is a true positive and a waste of attention. Tools vary widely in how well they distinguish those, and the difference does not show in detection statistics.
Severity ratings are frequently wrong for your context
Every tool assigns severity, and severity is assigned without knowing that this service is internal-only or that this input is already validated upstream. Treat vendor severity as a starting sort order, not a priority list.
The practical arrangement is to define your own severity mapping once, based on what is internet-facing and what touches sensitive data, and apply it over the top. That mapping is the same one that should be driving your cybersecurity audits, so it is usually work you have already done or should do anyway.
Where your source code goes is a real question
Most AI code review products send code to a model, and where that model runs varies. Some process entirely within your infrastructure, some use a hosted service under a commercial agreement, and some use general-purpose providers under terms that permit training on submitted content.
For a team building software under client contracts, this is frequently already answered by an agreement somebody signed. Many development contracts prohibit disclosing source to third parties without written consent, and connecting a hosted review tool is a disclosure whether or not it feels like one.
Get the three answers in writing
Ask where processing happens, whether code is retained after analysis, and whether submitted code can be used to improve the vendor’s models. All three should be unambiguous in the contract rather than described on a marketing page.
Teams working under defence, healthcare or financial obligations often find the answer rules out most of the market, which narrows the shortlist usefully rather than being a problem. The supply chain framing in our piece on defence supply chain security mistakes applies directly, and so do the documentation duties covered in our HIPAA Security Rule compliance guidance.
Self-hosted is viable and it costs something
Self-hosted analysis removes the disclosure question entirely and brings its own operational cost: infrastructure to run, models to update, and someone to own it. For a three-developer team that is usually too much. For a team under strict client obligations it is often the only workable answer.
The middle option worth asking about is a hosted service with contractual guarantees on retention and training, deployed in a region you specify. That is where most of this market has settled, and the same residency and access questions apply as to any other hosted platform, which we cover under cloud security.
What these tools find that older scanners do not
The genuine advance is in findings that require understanding intent rather than matching a pattern. An authorisation check present on one endpoint and absent on a sibling endpoint. A validation routine applied inconsistently. A function whose name promises sanitisation and whose body does not deliver it.
Traditional static analysis cannot see those, because there is no signature for a missing check. That class of defect is also the one that produces real incidents, since injection flaws in mainstream frameworks are increasingly caught by the framework itself.
It is weaker on your business rules
The corresponding limitation is that no tool knows your domain. A model cannot know that a refund above a certain value requires a second approval, or that this customer identifier must never appear in a log line. Those are the highest-consequence rules in most applications and they need a human reviewer who knows the business.
The workable split is to let the tool cover the mechanical and pattern-level layer thoroughly, and reserve human review time for logic that carries money, personal data or access decisions. That is a better use of review capacity than having a person re-check things a scanner already handles.
Dependency findings need separate handling
Most products bundle dependency scanning, and dependency findings behave differently. They arrive in volume, they are usually accurate, and the majority describe vulnerable code paths your application never calls. Handling them in the same queue as code findings is what buries both.
Treat them as a separate workstream with its own cadence, prioritised by reachability rather than by advisory severity. Teams that merge the two queues end up ignoring the merged queue.
Integration decides whether it is used
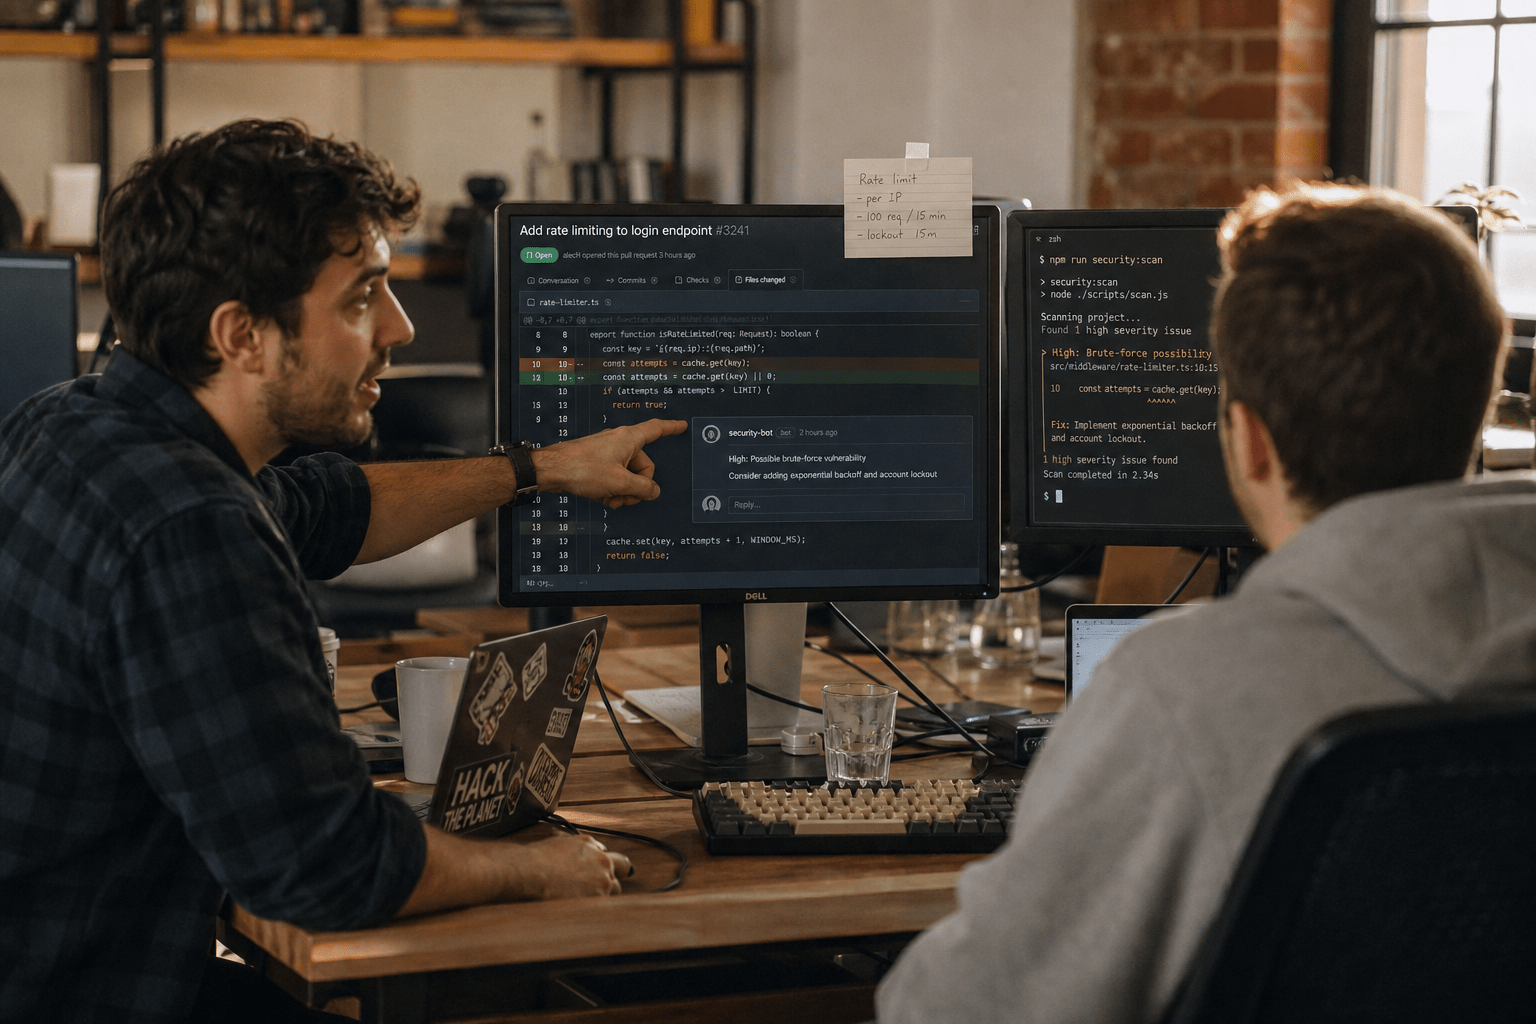
A finding raised inside a pull request, at the moment the author still has the change in their head, gets fixed. The same finding in a weekly report gets triaged into a backlog and expires there. That difference is larger than any capability gap between the leading tools.
So the integration question comes before the capability question: does it comment inline on pull requests in the platform you actually use, can it be scoped to changed lines rather than the whole file, and can it be configured to block a merge only on the categories you consider severe.
Blocking rules should start empty
Do not switch on merge blocking during evaluation. Run in advisory mode, watch what it would have blocked, and confirm those would have been correct calls. Blocking on day one against an untuned rule set is how a tool acquires a reputation internally that it never recovers from.
Once you do enable blocking, keep it to a small, defensible set: hardcoded credentials, known injection patterns, disabled certificate validation. Everything else advises. We apply the same graduated approach when introducing controls into working environments, as described in our piece on secure workspace solutions.
Accepting a fix suggestion is accepting code
Most of these tools now propose fixes as well as finding problems, and a proposed fix is a genuine time saver on mechanical issues. It is also code that becomes yours the moment it is merged, with your name on the commit and your liability attached.
Suggestions are usually correct on narrow, local changes and less reliable where the fix requires understanding how the function is used elsewhere. A suggested change to an authorisation helper can be locally correct and break a caller three files away.
Review suggestions as you would a junior developer’s pull request
That is the right mental model and it holds well. Read it, understand why it works, check the callers, and reject it if you cannot explain it. A team that accepts suggestions without that scrutiny is outsourcing judgement to something that has no view of the consequences.
For organisations commissioning software rather than writing it, the equivalent question for a supplier is what their review process is and how AI-assisted changes are validated. Our guidance on custom software development covers what to ask a development partner, and the tooling question now belongs in that conversation.
A practical evaluation sequence
Pick three representative repositories. Run each shortlisted tool and have a senior developer triage findings into genuine, arguable and wrong. Establish where code is processed, whether it is retained, and whether it can train a model, in writing. Confirm inline pull request integration on your platform. Run advisory-only for a month with no blocking. Then decide.
Teams distributed across home and office setups have an additional consideration, since review tooling touches source from wherever developers work, which overlaps with the exposures in our piece on hybrid work security costs. Where this sits alongside broader detection work, it belongs in the same programme as AI-enhanced security rather than as an isolated developer tool.
Frequently Asked Questions
Does AI code review replace a security audit?
No. These tools review code, and a security audit covers configuration, infrastructure, access control, dependencies and process. They are complementary, and an audit will typically ask whether you run code analysis at all, so having it strengthens the audit rather than substituting for it.
What false positive rate is acceptable?
Rather than a target number, use the developer test: after triaging a real sample from your own repositories, would your team still open the findings in month six. If a senior developer disagreed with most of what they read, the tool will be muted regardless of what it detects.
Can we use a general-purpose AI assistant for code review instead?
Technically yes, and the review is unstructured, unrepeatable and undocumented, which matters if anyone ever asks what your process is. The larger issue is contractual: pasting client source into a general assistant is a disclosure your agreements may already prohibit.
Should AI findings block a merge?
Only for a small, defensible set such as hardcoded credentials, known injection patterns and disabled certificate validation. Start advisory-only, watch what would have been blocked, and add categories once you have confirmed those calls were right.
Are the suggested fixes safe to accept?
Treat them as a junior developer’s pull request. They are usually sound on narrow local changes and less reliable where the fix depends on how a function is used elsewhere. Read it, check the callers, and reject anything you cannot explain.
Who is behind this guidance
Our team works with development groups and with the businesses that commission software from them, which means we see both the tooling decision and the contractual obligations sitting behind it. We have run the triage exercise where a well-regarded scanner produced a majority of findings a senior developer would not act on, and we have also had the awkward conversation with a client whose development agreement prohibited exactly the hosted analysis their team had already connected. Both are why this article puts the sample triage and the contract question ahead of any feature comparison.
Matt Rosenthal, our CEO, applies a consistent test to security tooling: if the people who have to act on it have stopped reading it, the control does not exist regardless of what the licence says. That is why adoption is treated here as the primary criterion rather than a secondary concern, and it shapes how we recommend introducing analysis into a working team.
Triage a real sample before you compare feature lists
The teams getting value from AI code review in 2026 did not choose on capability. They ran the candidates against their own repositories, had a senior developer say honestly which findings were worth acting on, settled where their source code was allowed to go, and ran advisory-only long enough to earn the right to block anything. The tool that survived was frequently not the one with the longest feature list.
If you are evaluating now, the decisive question is not which tool finds more. It is which one your developers will still be reading six months from now, and a few hours of triage on your own code answers it.
Book a free strategy call and we will look at your code review process and obligations with you.