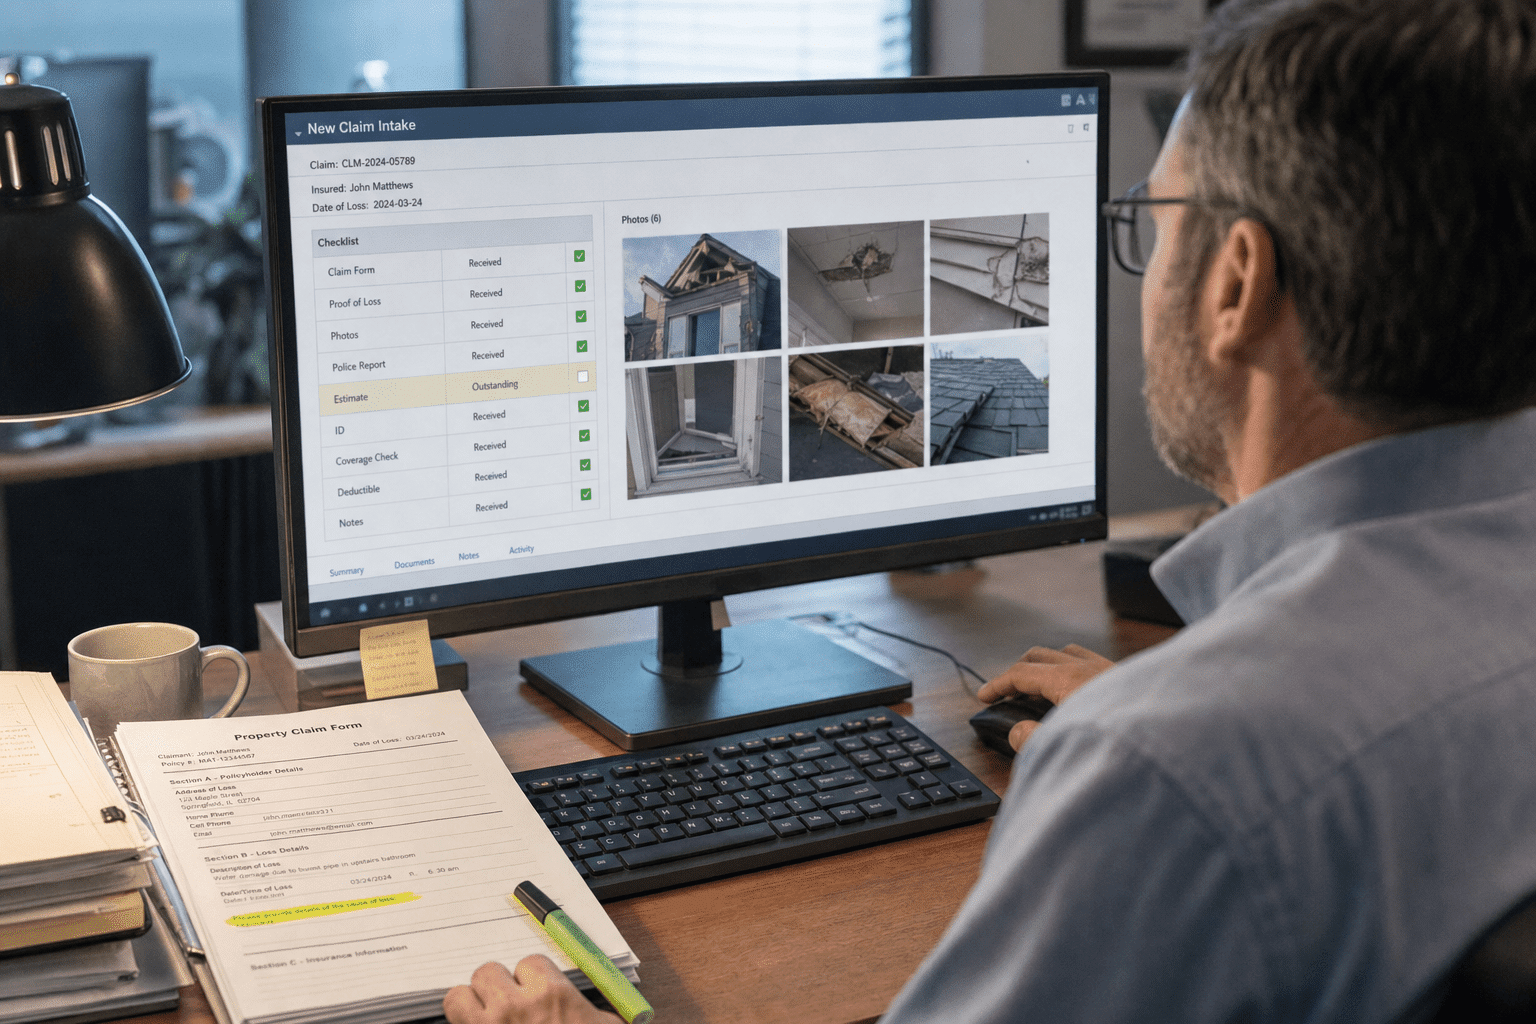
The best AI agents for claims processing are the ones that fix intake, because that is where the cost actually sits. Cycle time is the headline metric and it flatters automation: shave two days off adjudicating a complete file and the dashboard improves, while the file that arrived without a police report or with an unreadable photograph still waits three weeks for someone to chase it. Incomplete intake drives rework, rework drives leakage, and leakage is the number that shows up in loss ratios. Buy for document completeness at first notice and for the handoffs afterward, and cycle time improves as a consequence rather than as a target.
Where a Claims Operation Actually Loses Money
Claims operations lose money in places that a cycle-time dashboard does not show. Five patterns account for most of it in the mid-sized carriers and brokers we work with:
- Files enter incomplete and nobody notices for days. The gap is discovered when an adjuster picks the file up, not when it arrived.
- The same information is collected three times. Intake, the adjuster, and the vendor each ask the claimant for the same document because none can see the others’ record.
- Coverage is verified late. Work proceeds on a claim that policy terms would have limited, and the effort is unrecoverable.
- Subrogation opportunities are spotted after the recovery window. Nobody was reading for third-party liability at intake, and by settlement it is too late.
- Reserves are set once and never revisited. The initial estimate ages badly and the correction lands as a surprise in a quarter nobody planned for.
None of these is an adjudication speed problem. Every one of them is an information problem at or near intake, which is where agent tooling has the most room to help. Sector context sits on our insurance industry page.
Fixing First Notice of Loss Before Anything Downstream
First notice of loss determines the cost of everything that follows, because a file that starts complete moves and a file that starts short circulates. Our team treats intake as the place to spend the automation budget, and we look at three capabilities in particular: whether the agent can tell that a document is missing, whether it can read the documents that did arrive, and whether it can ask the claimant for the gap without a human drafting the request.
Knowing a Document Is Missing, Not Just Reading the Ones Present
Completeness checking is a different capability from document extraction, and products conflate them constantly. In favour of requirement-driven intake: an agent that knows a residential water damage claim needs a plumber’s report, photographs of the affected rooms, and a schedule of damaged contents can compare that requirement list against what arrived and generate a precise gap list within minutes of submission. The claimant receives one clear request while the incident is fresh in their mind, which is the moment they are most able to respond.
Against assuming this comes standard: most document AI is built to extract from what it is given and is silent about absence, which is the same could-not-see versus is-not-there confusion that undermines any inspection system. A tool reporting successful processing on a file missing half its evidence has told you nothing useful. We ask vendors to show the requirement model, per claim type, and to demonstrate a file with a missing document rather than a complete one. If the demonstration only ever uses complete files, that is the answer.
Reading Photographs, Handwriting, and the Documents Claimants Actually Send
Extraction quality on real claimant submissions is lower than any demo suggests, and planning around that is more useful than hoping. Supporting current tooling: typed documents, structured forms, and clear photographs of damage are handled reliably now, and that covers a decent share of volume in commercial lines where submissions come from brokers rather than individuals.
Where it degrades sharply: photographs taken in poor light, handwritten incident notes, documents photographed at an angle with a thumb over one corner, multi-page PDFs assembled in the wrong order, and screenshots of screenshots. Personal lines intake is full of these. The workable design accepts that a proportion of submissions will route to a human and measures that proportion honestly, rather than forcing everything through and accepting silent extraction errors. We set the confidence threshold so that a wrong extraction is rarer than a routed file, because a mis-read policy number costs far more to unwind than a two-minute manual review.
Asking the Claimant for the Gap Without Sounding Like a Robot
Closing the loop with the claimant is where agents earn goodwill or destroy it. In favour of automating the request: speed matters enormously here. A gap request sent within the hour gets a response rate that a request sent in four days does not come close to, and that difference compounds through the whole claim.
The counterargument is tone, and it is not a small point. A claimant who has had a fire or a car accident receives a templated demand for four documents and reads it as an insurer being difficult. We have seen a well-built automation measurably increase complaint volume for exactly this reason. The fix is not to slow it down but to write the messages properly, acknowledge the situation in the first line, explain why each document is needed, and offer a human contact in the same message. That is a copywriting exercise, done once, and most implementations skip it. Our piece on AI agents in customer service covers the same tension in other settings.
Triage, Reserves, and the Handoffs Between Them
Once a file is complete, the value shifts from collecting information to routing it. This is the part most products describe as intelligent triage, and it is genuinely useful when scoped to segmentation rather than decision-making.
Segmenting Simple Files From Complex Ones
Segmentation is the highest-return triage capability and the least risky. Arguing for it: a straightforward claim within policy limits, with complete documentation and no injury or third party, follows a different path from one with any of those complications, and an agent can make that separation reliably from structured data alone. Routing the simple ones to a fast lane frees experienced adjusters for files that reward their judgement, and that reallocation is where the operational gain actually comes from.
Against pushing it further into adjudication: the temptation is to let the fast lane settle automatically, and that is where segmentation turns into a decision the agent is not equipped to make. A claim can look simple on every structured field and carry a fact in a free-text note that changes everything. We keep automated settlement to a narrow band with a hard value ceiling, and we sample settled files monthly rather than trusting the classification indefinitely. The risk framing is in our write-up on autonomous workflow agents.
Flagging Subrogation While the Recovery Window Is Open
Subrogation identification is the capability with the clearest financial return and the one most often missing. Supporting automated reading for recovery potential: an agent scanning the incident narrative for a third party at fault, a defective product, or a premises liability angle can flag files at intake rather than at settlement. Recovery attempted early succeeds far more often, and the flag costs nothing when it is wrong.
The limitation is that narrative quality drives everything. A two-line loss description gives the model nothing to work with, and the flag rate collapses on exactly the files where intake was rushed. That circles back to the first point: better intake makes every downstream capability work better, which is why we sequence intake first rather than buying the triage module because it demos well.
Keeping Reserves Honest
Reserve accuracy is a quieter problem and a good fit for continuous review. In favour: an agent comparing a file’s current facts against historical outcomes for similar claims can flag when a reserve looks stale, which catches the slow drift that produces quarter-end surprises. It does this without needing authority to change anything, which makes it easy to adopt.
Against over-trusting it: reserve models trained on your history encode your past reserving behaviour, including where it was systematically wrong. If the operation has historically under-reserved a category, the model learns that as normal and stays quiet. We treat reserve flags as a prompt for review rather than a verdict, and we validate the model against categories where we already know the answer before extending it. Integration into the claims system is standard enterprise AI integration work, and the wider workflow automation sits under intelligent process automation.
Vendor Handoffs, Where Files Go Quiet
Third-party handoffs are the least automated part of most claims operations and a reliable source of delay. Supporting agent involvement: when a file goes to a loss adjuster, a repair network, or a medical reviewer, the agent can hold the expected turnaround, notice when it lapses, and chase without anybody remembering to diarise it. Files that go quiet for three weeks at a vendor are common, and almost none of that delay is anyone’s deliberate choice.
Against treating it as solved: vendors mostly do not integrate. Chasing happens by email, and an agent parsing free-text replies to work out whether an inspection has been booked will get it wrong some of the time. A confidently wrong status is worse than an empty one, because the file looks progressed. We configure these agents to record only what they can verify, an inspection date extracted from a confirmation, for example, and to mark everything else as unconfirmed rather than inferring progress from a friendly reply.
The measurable version is simple and worth having even without integration: track time-at-vendor per file as a first-class metric. Most operations cannot currently produce that number, and once they can, the two or three vendors responsible for the bulk of the delay become obvious immediately.
How We Score AI Agents for Claims Processing
We score AI agents for claims processing on four questions. Does it model requirements per claim type, so it can identify an absent document rather than only reading present ones. Does it report extraction confidence per field and route low-confidence items rather than guessing. Does it write to your claims system natively, since a recommendation that needs rekeying is not automation. Does it retain the evidence and reasoning behind any routing or flag, because a denied claim gets scrutinised and the file has to explain itself.
Cycle time and straight-through processing rate, the two figures every vendor leads with, are consequences rather than criteria. A high straight-through rate on a book of clean commercial submissions says more about the book than the product. Getting a realistic picture starts with the same groundwork as any deployment, which our guide to integrating AI agents and our AI agents services both cover, and the finance-side equivalent is in our piece on AI agents for finance.
Frequently Asked Questions
Will AI agents replace claims adjusters?
Not in any deployment we have run. They remove document chasing, data entry, and the routing decisions that do not need judgement, which is most of an adjuster’s day and none of the part that requires experience. Headcount tends to shift toward complex files rather than fall.
What claim types automate well?
High-volume, low-variance types with structured evidence automate best, such as glass, simple property damage, and routine commercial lines. Injury claims, anything with a liability dispute, and long-tail claims resist automation because the decisive facts live in narrative and negotiation.
How do we handle a wrong extraction?
Design for it rather than around it. Set confidence thresholds so uncertain fields route to a human, and audit a sample of high-confidence extractions monthly. The dangerous failure is not a routed file, it is a confidently wrong policy number nobody checked.
Can an agent decide to deny a claim?
We advise against granting that authority. A denial is a regulated communication that must be explainable and is frequently challenged. An agent can assemble the evidence and draft the reasoning, and a person should own the decision and the letter.
Where should a mid-sized carrier start?
Start at first notice of loss with completeness checking. It is the cheapest capability to deploy, it improves every downstream step, and it produces a measurable change in rework within a quarter, which makes the next investment easier to justify.
Who Is Behind This Advice
Our team has implemented claims automation in operations where the adjusters were already at capacity and the backlog was the reason for the project. The lesson that repeats is that automating adjudication on clean files makes a good metric better and leaves the backlog roughly where it was, because the backlog was never clean files. Moving the same budget to intake completeness changed the numbers that mattered within one quarter.
We also spend real time on the claimant-facing wording, which sounds like a minor detail and is not. The same automation, with messages written carefully rather than generated from a template, produced fewer complaints and a higher document return rate.
Matt Rosenthal leads Mindcore and pushes for automation aimed at the constraint a business actually has rather than the one that is easiest to measure.
Start at Intake, Not at Adjudication
The takeaway is worth acting on before your next system evaluation. Claims automation pays back where files enter the operation, not where they leave it, so start with completeness at first notice of loss. Ask vendors to model requirements per claim type and to demonstrate against an incomplete file rather than a tidy one. Set extraction confidence thresholds so uncertain fields route to a person, and audit the confident ones anyway. Write the claimant messages properly, once, because tone at that moment shapes both response rates and complaints. Use segmentation to free experienced adjusters rather than to settle automatically, keep any automated settlement inside a hard value ceiling, and flag subrogation at intake while recovery is still possible. Treat reserve flags as prompts rather than verdicts. Sequenced that way, the cycle-time number improves on its own, and the leakage number, which is the one attached to real money, improves with it. If you want a view on which of your claim types are genuinely ready for this, book a free strategy call and bring a month of intake files.