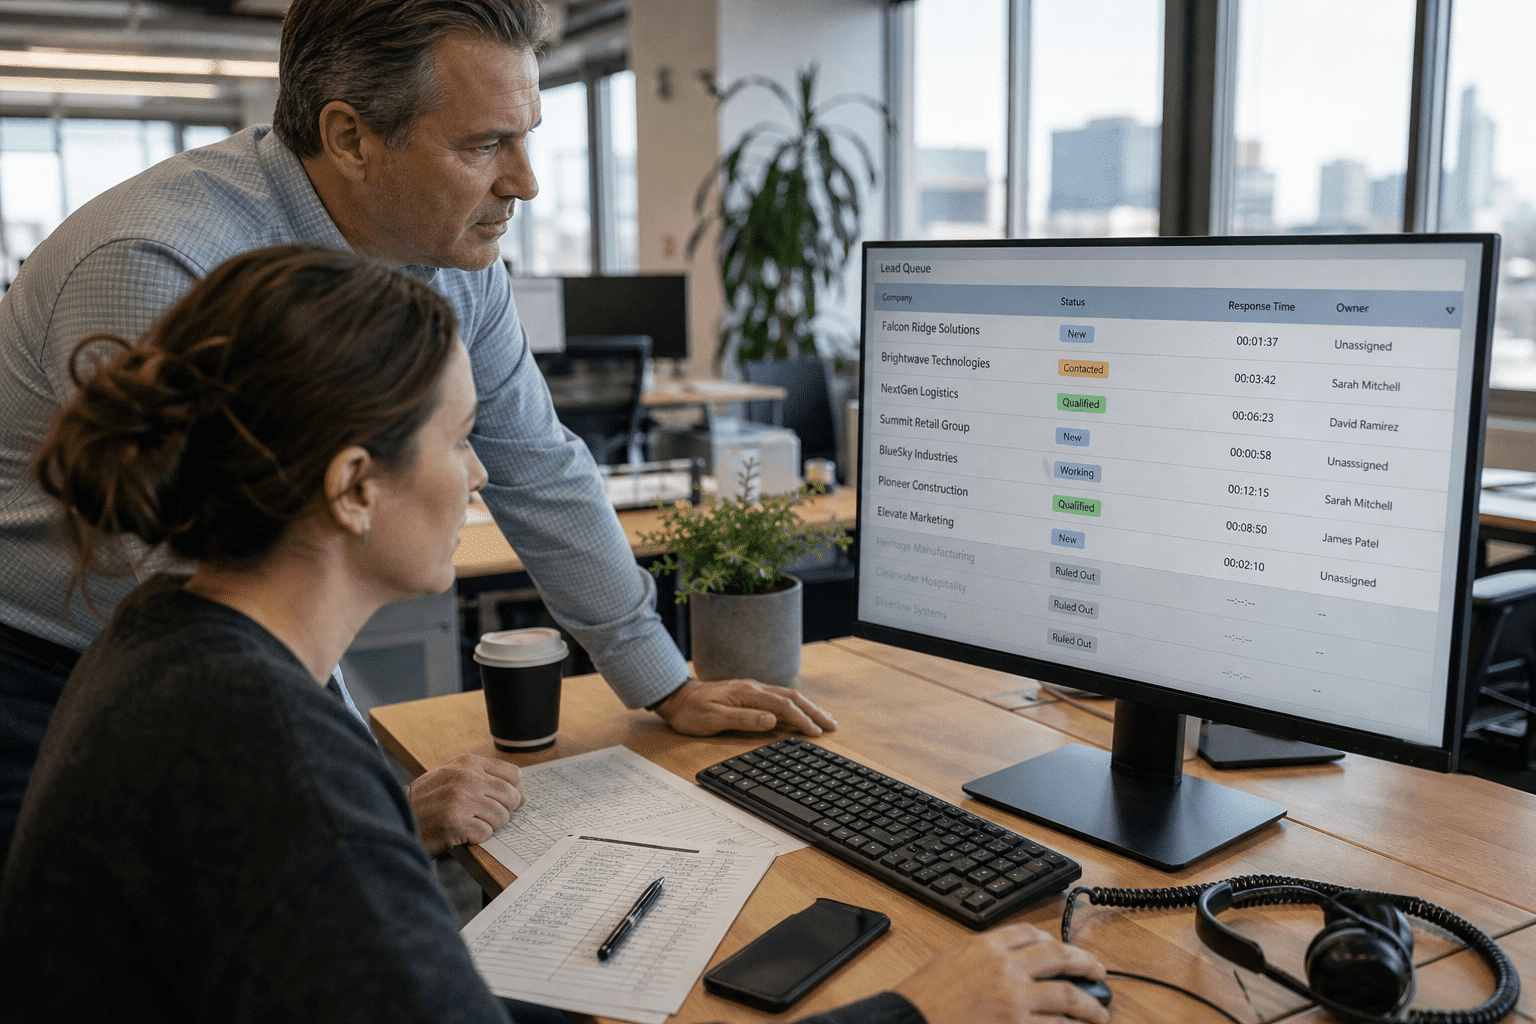
The best AI agents for lead qualification are the ones that disqualify confidently and shorten time to first contact. Scoring is the feature everyone demonstrates, and a better-ordered list is worth surprisingly little on its own. If a two-person sales team can work thirty leads a week and receives ninety, ranking those ninety means the same sixty go untouched, just in a different order. Removing thirty that were never going to buy, and reaching the remainder within minutes rather than the next afternoon, produces a change you can see in the pipeline. Judge these products on how well they say no, and on how fast they act.
Why Lead Scoring Rarely Changes Anything
Lead scoring projects underdeliver for reasons that have little to do with the model. Five patterns recur across the sales operations we see:
- Sales and marketing disagree on what qualified means. Marketing scores on engagement, sales qualifies on budget and timing, and the handoff argument repeats weekly.
- The score has no consequence. Leads are ranked and then everybody works their own list anyway, so the ranking is decoration.
- The data behind the score is stale. Firmographic enrichment ages fast, and a headcount figure from two years ago is scoring a company that has since halved.
- Speed is ignored. A well-scored lead contacted two days later converts far worse than an unscored one contacted in ten minutes.
- Nothing is learned from losses. Closed-lost reasons go unrecorded, so the model keeps optimising toward whatever historically got attention rather than what closed.
The fourth point outweighs the rest in most businesses. Our piece on AI agents in sales covers the wider funnel; this one stays on the qualification step.
Disqualification Is the Output Worth Paying For
Disqualification is the capability with the clearest return and the one vendors talk about least, because saying no is a harder sell than finding hidden gems. Our team frames the buying question around three things: can it rule leads out on verifiable grounds, can it enrich reliably enough to trust those grounds, and can it act quickly on the ones that survive.
Ruling Out on Facts Rather Than Behaviour
Fact-based disqualification is safer and more defensible than behavioural scoring. In favour: some criteria are binary and checkable. The company sits outside your service geography, operates in an industry you cannot support, has five employees when your smallest viable customer has fifty, or is a competitor doing research. An agent that verifies those against external company data removes leads with near-zero risk of discarding a real buyer, and the removal is explainable to a sales manager who challenges it.
Against extending this to behavioural signals: a lead that has not opened three emails is not disqualified, it is unengaged, and treating the two the same throws away pipeline. We have seen a model taught that low engagement means low intent quietly suppress an entire segment of buyers who research silently and arrive ready. Keep hard disqualification to verifiable facts, and let behaviour influence ordering rather than exclusion. The distinction sounds fussy and it is the difference between a tool that saves time and one that costs revenue nobody attributes to it.
Enrichment Data and How Fast It Rots
Enrichment quality decides whether fact-based rules are trustworthy, and it decays faster than most teams assume. Supporting modern enrichment: coverage of company size, sector, technology stack, and funding events is genuinely good for mid-market and larger companies, and an agent that checks a lead against that data catches obvious mismatches immediately.
The problem sits at the small end, which is where many businesses sell. Coverage of firms under twenty staff is thin and often years out of date, so a rule excluding companies below a headcount threshold will exclude real prospects whose record simply has not been updated. We handle this by treating missing or low-confidence enrichment as unknown rather than as failing the rule, which keeps those leads in the queue for human eyes. It costs a little review time and prevents the failure mode where the agent silently deletes a category of customer. That is the same absent-is-not-zero discipline that any well-built automation needs, and it is discussed more broadly in our piece on autonomous workflow agents.
Speed to First Touch, the Number That Actually Moves
Response time is the highest-leverage variable in the whole qualification stage. Arguing for automating first contact: the drop in connection rates between a response inside five minutes and one the next morning is dramatic, and no amount of scoring recovers it. An agent that acknowledges a form submission immediately, asks two qualifying questions, and books a slot in a real calendar captures interest at its peak, and it does so at 9pm and on Saturdays when nobody is at a desk.
The counterargument is quality of interaction, and it deserves respect. An automated first touch that reads as automated can cost you a serious buyer who concludes nobody is home. The version that works is short, states plainly that it is arranging a conversation rather than pretending to be a person, and hands over cleanly. We have found that transparency raises response rates rather than lowering them, which surprises people who assume the goal is to sound human. Related patterns are in our write-up on AI agents for customer engagement.
Making the Handoff Survive Contact With a Sales Team
A qualification agent lives or dies on what happens at the handoff, and this is organisational as much as technical. The best model in the world produces nothing if the salesperson receiving the lead does not believe it.
Agreeing What Qualified Means Before Configuring Anything
Definition alignment has to happen first, and it is the step most projects skip in their hurry to configure. In favour of doing it properly: writing down the four or five conditions that make a lead worth a salesperson’s hour, and getting both marketing and sales to sign it, turns the agent into an enforcer of an agreed rule rather than a third party with an opinion. Disputes then concern the definition, which is productive, instead of the tool, which is not.
Against over-formalising: definitions that run to twenty criteria cannot be operated or maintained, and they encode this quarter’s strategy into a system that outlives it. We keep the list short enough to recite from memory and revisit it quarterly. A definition nobody can recall is a definition nobody applies, and the agent’s output then gets overridden case by case until it is ignored entirely.
Routing With a Clock On It
Routing is where qualification either converts into activity or evaporates. Supporting automated routing with an SLA: assigning a qualified lead to a named person with a response deadline, and escalating when the deadline passes, is straightforward to implement and closes the most common leak in the funnel, which is the lead that was assigned to someone on holiday.
Against unlimited escalation: a routing system that reassigns aggressively teaches salespeople that ignoring a lead makes it someone else’s problem. We set one escalation, to a manager rather than to another rep, and we report the rate rather than only acting on it. The report is the useful part, because a persistent escalation pattern is a staffing or territory problem that no routing rule can fix. Wiring this into an existing CRM is ordinary enterprise AI integration work.
Feeding Outcomes Back Without Adding Admin
Outcome capture is what stops the model drifting, and it competes directly with a salesperson’s time. In favour of automating it: much of the signal is already implicit in CRM activity, so an agent can infer that a lead went cold from an absence of logged interaction rather than requiring anyone to fill in a form.
The limitation is that inferred outcomes are coarse. Knowing a lead went cold is far less useful than knowing it went cold because the budget moved to next year, and no inference recovers that reason. We ask for one structured field on close, with five options, and we accept that anything more elaborate will not be filled in reliably. The wider automation context sits in our overview of ways AI agents streamline operations and in our intelligent process automation work.
Inbound and Outbound Need Different Rules
Applying one qualification model to inbound and outbound leads is a common configuration error with an expensive symptom. In favour of separating them: an inbound lead has already expressed intent by arriving, so the useful question is fit and timing. An outbound contact has expressed nothing, so intent signals are absent by definition and scoring them on engagement guarantees near-zero scores across a list that may contain your best future customers.
We have watched a single blended model quietly suppress an entire outbound programme. The scores were technically correct and operationally useless, because the model was reporting that people who had never heard of the company were not currently interested. The team read that as the list being poor and rebought data, which changed nothing.
Against maintaining two models: it is more configuration to keep current, and small teams struggle to maintain even one. The compromise we usually land on is one model with source as a first-class input and different thresholds per source, which is simpler to operate than two systems and avoids the blending failure. Whichever route you take, check what your candidate product does here before buying, because several popular tools assume inbound and offer no clean way to express the difference.
How We Score AI Agents for Lead Qualification
We score AI agents for lead qualification on four questions. Can it disqualify on verifiable facts and show its evidence, so a challenged decision can be reviewed. Does it treat missing enrichment as unknown rather than as a failed criterion. Can it act inside minutes, including outside business hours, since response time outweighs ranking accuracy. Does it write cleanly into your CRM as the system of record, because a parallel scoring database becomes a second version of the truth within a month.
Model sophistication is not on the list, and deliberately so. A transparent rules-and-enrichment agent that a sales manager can inspect will outperform an opaque scoring model in practice, because it gets trusted and therefore used. Adoption beats accuracy at the volumes most mid-market teams operate at. Our general deployment guidance is in five steps to integrating AI agents, and the capability set is described under AI agents services.
Frequently Asked Questions
How much of our lead volume should an agent disqualify?
There is no target figure, and setting one is a mistake. The right rate falls out of your criteria and your traffic mix. What matters is that every disqualification is explainable and that you sample them monthly to confirm the agent is not excluding a viable segment.
Will an automated first response put buyers off?
Not if it is honest about what it is. A short message that states it is arranging a conversation and books a real slot performs well. Attempts to pass as a person perform badly, because buyers notice and conclude the company is being evasive.
Do we need enrichment data to make this work?
For fact-based disqualification, yes, and its coverage sets your ceiling. If you sell to very small businesses, expect thin data and design the rules so that unknown keeps a lead in the queue rather than removing it.
Should the agent contact leads outside business hours?
Yes for acknowledgement and scheduling, which is where the response-time advantage is largest. Hold substantive conversations for working hours, since a lead that gets an automated exchange at midnight and no human contact until Tuesday is worse off than one that got a prompt acknowledgement.
How long before we can tell it is working?
Allow one full sales cycle plus a few weeks. Shorter than that and you are measuring activity rather than outcomes. Track time to first touch and disqualification accuracy from week one, since both are observable immediately and both predict the later numbers.
Who Is Behind This Advice
Our team has put these agents into sales operations small enough that the person running marketing is also the person doing the follow-up. That vantage point shapes the recommendation: the deployments that stick are the ones where the definition of qualified was agreed in a room before anybody configured a rule. The ones that fail are technically fine and get overridden until they are switched off.
We also see the version where a firm buys sophisticated scoring and leaves response time untouched. Six months later the leads are beautifully ranked, the first contact still happens the next afternoon, and conversion has not moved at all. The scoring was never the constraint.
Matt Rosenthal leads Mindcore and pushes for automation aimed at the bottleneck a business actually has, which in sales is almost always speed and capacity rather than insight.
Fix Response Time, Then Worry About Ranking
The takeaway is worth testing against your own funnel this month. Lead qualification pays back through confident disqualification and fast first contact, not through a better-ordered list. Write down the four or five conditions that make a lead worth an hour, and get both sales and marketing to sign them. Let the agent rule out only on verifiable facts, treat unknown enrichment as unknown, and keep behavioural signals in the ordering rather than the exclusion. Automate acknowledgement and scheduling so first touch happens in minutes at any hour, and be plain that it is automated. Route to a named person with a clock and one escalation, then report the escalation rate rather than just acting on it. Capture one structured reason at close and nothing more elaborate. Measure time to first touch and disqualification accuracy from the first week. Done that way the pipeline change shows up inside a cycle, and it shows up because the team is reaching more of the right people sooner rather than because a score improved. If you want a second opinion on where your funnel is actually leaking, book a free strategy call and bring last quarter’s lead log.