The best AI integration platforms for enterprise IT stacks in 2026 are chosen on six connectors, not four hundred. Every vendor in this space leads with the size of its connector library, and a large library tells you the platform can authenticate to a great many systems. It tells you almost nothing about whether it can do the specific thing you need in the six systems you actually run.
Depth is the property that matters and it is never on the marketing page. A connector that reads records is trivially different from one that writes them, and one that writes standard fields is meaningfully different from one that writes your custom fields, handles your validation rules and respects your approval workflow. Projects fail at that level of detail, months after the platform decision, when the connector turns out to be read-only for the object that mattered.
Overview: five things that decide whether an integration platform works
- Depth on your six systems beats breadth across four hundred. Test the connectors you will actually use.
- Error handling is the operational half nobody demonstrates. What happens when a target system is down decides your Monday mornings.
- System of record ownership has to be settled before anything is wired. Two systems both authoritative is a data quality problem waiting.
- Observability separates a platform from a script collection. You need to see what ran, what failed and what it changed.
- Open protocols reduce lock-in and are not yet uniform. Ask what happens to your logic if you leave.
Written for IT directors, systems architects and technical owners at organisations of fifty to a thousand people connecting business applications rather than building product.
Connector depth is the evaluation that matters
Connector depth determines whether the platform can do your job or only the demonstration version of it. The evaluation is unglamorous: list the six to ten systems you need connected, and for each one write down the specific operations required.
Not “connects to the CRM” but “creates an opportunity with our three custom fields populated, respecting the validation rule on close date, and attaches a file”. That level of specificity is what separates a platform that works from one that gets 80 percent of the way and stops.
Build one real integration during evaluation
Ask each shortlisted vendor for a trial and build your single most complex integration in it. Not the easy one. The one involving the awkward legacy system and the custom fields.
This takes a few days and it is the only reliable predictor. Every platform handles the straightforward case, and the difference between them is entirely in how they handle the difficult one. A vendor unwilling to support a genuine build during evaluation is telling you something about post-sale support too.
Custom fields and validation rules are where it breaks
The specific failure to test for is whether the connector exposes your customisations. A generic connector built against a vendor’s standard object model may be unaware of the fields your business added, which are frequently the fields carrying your actual process.
Validation rules are the second trap. An integration writing a record that your target system rejects for a rule the connector did not know about fails at run time rather than at build time, and often silently. This is the same class of problem we describe in our piece on local business AI integration challenges.
Error handling is the half nobody demonstrates
Demonstrations show the working path. Production is mostly the other one: a target system down for maintenance, a rate limit reached, a record locked, a malformed payload from an upstream change nobody announced.
What the platform does then decides how much of your week this consumes. Does it retry with sensible backoff. Does it queue and resume, or drop. Does it alert a human, and with enough detail to act. Can you replay a failed batch after fixing the cause without duplicating everything that already succeeded.
Replay capability is worth more than it sounds
The ability to reprocess a failed batch cleanly is the difference between a twenty minute recovery and a day of manual reconciliation. Ask specifically whether replay is idempotent, meaning re-running it does not duplicate records that already landed.
Anyone who has manually unpicked three hundred duplicate records created by a well-intentioned retry understands why this is near the top of the list. It also belongs in your continuity planning, since an integration failure during a wider outage is exactly when you least want manual reconciliation, as covered under business continuity planning.
Alerting has to reach a person who can act
Integration failures notoriously alert into a mailbox nobody reads. Confirm that failures route to a channel your team monitors, with enough context to diagnose without opening the platform.
An alert saying an integration failed is not actionable. One naming the integration, the record, the target system and the error is. That difference determines whether failures get fixed the same day or discovered a fortnight later when someone notices missing data.
Settle system of record before you wire anything
The question that causes the most durable damage is the simplest: for each piece of data, which system is authoritative. When a customer address exists in the CRM, the accounting system and the support platform, one of them has to win.
Organisations that skip this build bidirectional syncs that fight each other. A change in one system propagates, gets overwritten by a stale value from another, and propagates back. The symptom is data that changes on its own and nobody can explain, and it is genuinely hard to unpick later.
Write it down as a table
One row per data domain, one column for the authoritative system, one for which systems receive it. Customers, products, pricing, contacts, invoices. It takes an afternoon and it prevents the whole class of problem.
Bidirectional sync should be the exception, chosen deliberately with conflict resolution rules, rather than the default because the platform offers it. This documentation belongs alongside the rest of your system records, which is the discipline our piece on documenting your IT systems sets out.
Observability is what makes it a platform
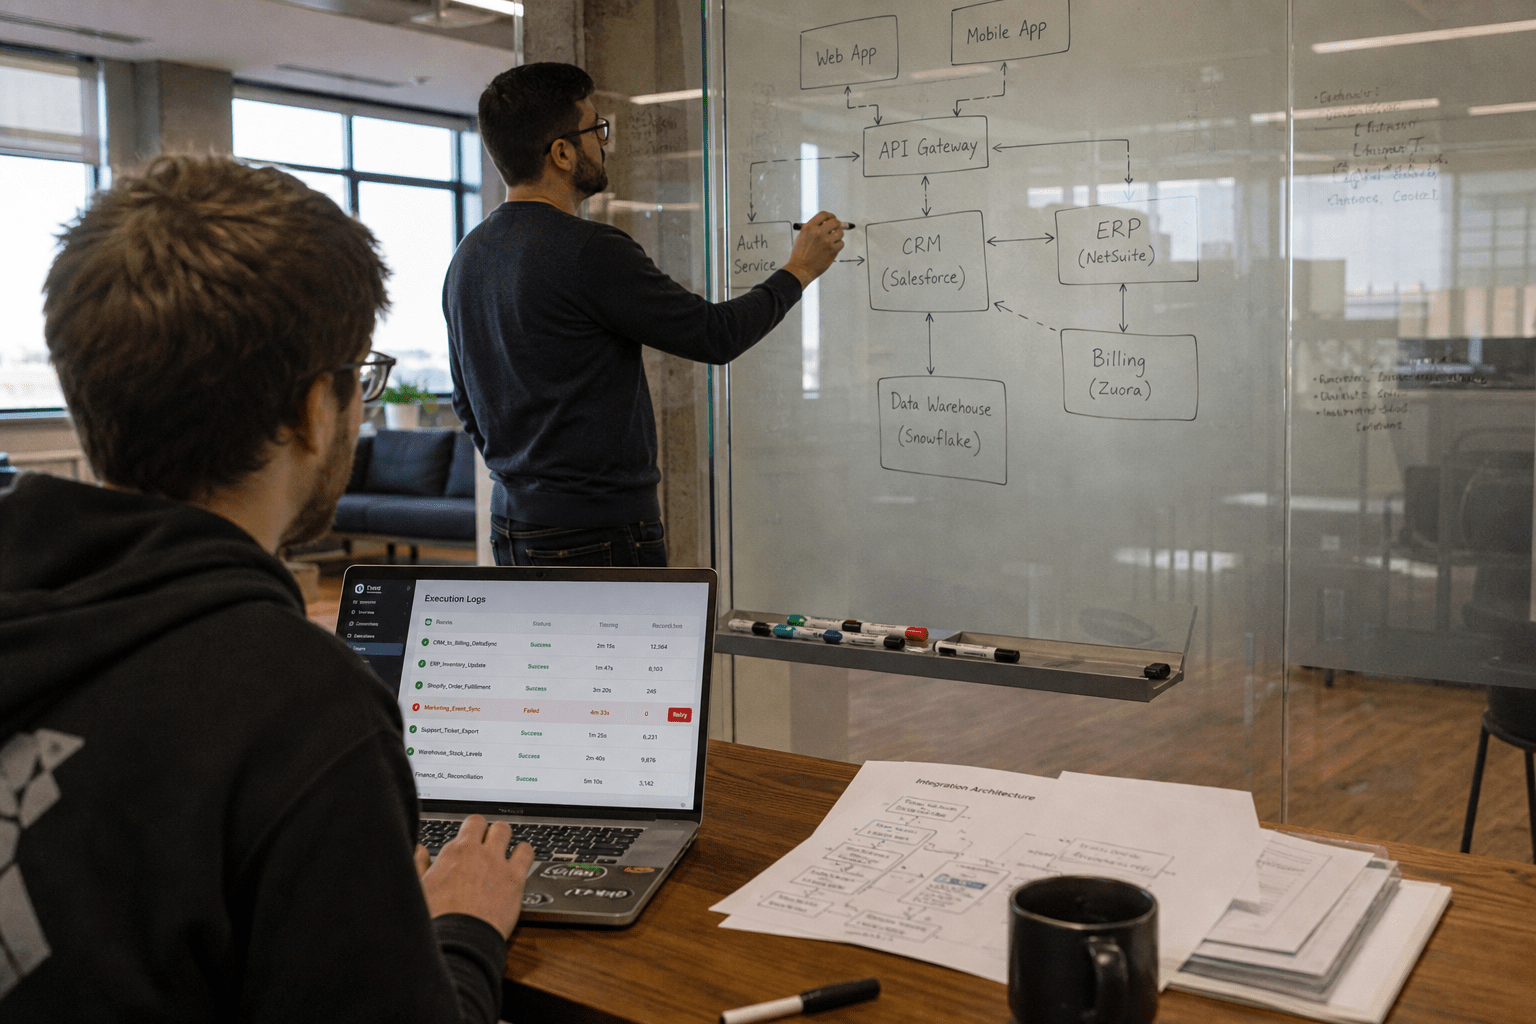
A collection of scripts moves data. A platform lets you answer questions about what happened: which integrations ran today, how many records each moved, what failed, and what a specific record’s journey was when somebody asks why a value is wrong.
That last one is the test. When a colleague reports that a customer’s address is wrong in the accounting system, can you trace where the value came from and when. If the answer requires reading logs across three systems, you have scripts with a user interface.
Ask about retention and search
Execution history retention varies widely and matters more than people expect, because integration problems are frequently reported weeks after they started. Thirty days of history is thin when a quarterly process fails.
Confirm you can search execution history by record identifier rather than only by time. Being able to ask what happened to this specific invoice is the query you will actually run, and some platforms cannot answer it. The security dimension of that audit trail is covered in our piece on AI integration security.
Open protocols and what happens if you leave
A newer development worth understanding is the emergence of open protocols for connecting AI systems to business applications, which reduce the need for a bespoke connector per pairing. Our explainer on Claude MCP and connecting AI to real business systems covers the mechanism.
Support is real and uneven. Where a platform supports an open protocol, a connector you build has value beyond that platform, which is a genuine reduction in lock-in.
Ask the exit question during the sale
The useful question is what you take with you if you leave. Integration logic expressed in a proprietary visual builder is not portable, and a two-year investment in it is a two-year investment in that vendor.
Nobody enjoys asking this during a purchase and the answer is informative in both directions. It belongs in the same assessment as the rest of your vendor due diligence, which our piece on AI vendor review blind spots sets out.
Who runs it after go-live
Integration platforms need an owner. Someone has to watch failures, update connectors when a target system changes its API, and review what has accumulated. Without that, the platform quietly degrades: integrations built for projects that ended keep running, credentials expire, and the failure alerts nobody reads pile up.
For organisations without a dedicated integration team, that ownership realistically sits with whoever runs the platform layer, which is part of managed IT services rather than something to leave with whoever built the first integration. The build work itself is what we handle under AI agents.
A practical evaluation sequence
List your six to ten systems and the specific operations you need in each. Build your hardest integration during a trial. Test the failure path deliberately by taking a target system offline. Confirm replay is idempotent. Write the system of record table before wiring anything. Check execution history retention and whether you can search by record. Ask what is portable if you leave. Name the owner before go-live.
The step that pays for itself immediately is building the hard integration during evaluation. It is a few days of work and it converts a decision based on a connector list into one based on evidence.
Frequently Asked Questions
How many connectors do we actually need?
Almost always fewer than ten, and depth on those matters far more than the size of the library. Write down the specific operations you need in each system, including custom fields and validation rules, and evaluate against that list rather than against a logo page.
What breaks most often in production?
Upstream changes nobody announced and target systems being temporarily unavailable. Both are normal, so the question is what the platform does about them: whether it retries sensibly, queues rather than drops, alerts someone who can act, and lets you replay a failed batch without creating duplicates.
Should we build integrations ourselves instead?
Custom code is reasonable for one or two stable integrations and becomes expensive past that, because you are then building your own observability, retry logic and alerting. A platform earns its cost mainly through those operational features rather than through the connectors.
What is the most common architectural mistake?
Not deciding which system is authoritative for each piece of data before wiring anything. Bidirectional syncs then fight each other, values change on their own, and the cause is genuinely hard to trace afterwards. One table with one row per data domain prevents it.
Do open protocols remove vendor lock-in?
They reduce it where supported, because a connector built to an open protocol has value beyond one platform. Support is uneven in 2026, so ask specifically what happens to your integration logic if you leave, particularly where that logic lives in a proprietary visual builder.
Who is behind this guidance
Our team works across the integration layer for mid-sized organisations, connecting the CRM, finance, service and line-of-business systems that most companies run rather than building product from scratch. We have watched a platform selected on connector breadth stall on a read-only connector for the one object that mattered, and we have also spent a week untangling a bidirectional sync where two systems overwrote each other because nobody had written down which one was authoritative. Both are why this article puts depth testing and the system of record table ahead of the feature comparison.
Matt Rosenthal, our CEO, applies a consistent test to platform decisions: who owns it in eighteen months, and how would they know it had stopped working. That is why observability and named ownership appear here as evaluation criteria rather than as operational afterthoughts.
Build your hardest integration before you sign anything
The organisations whose integration platforms are still serving them well in 2026 did not choose on the connector list. They wrote down the specific operations they needed, built the most awkward one during a trial, deliberately broke a target system to see what happened, and settled which system owned which data before wiring anything together. The decision took longer and the project did not stall in month four.
If you are evaluating now, the question that separates the shortlist is not how many systems a platform connects to. It is whether it can write your custom fields into your most awkward system, and a few days of trial answers it definitively.
Book a free strategy call and we will map your integration requirements and system of record positions with you.