

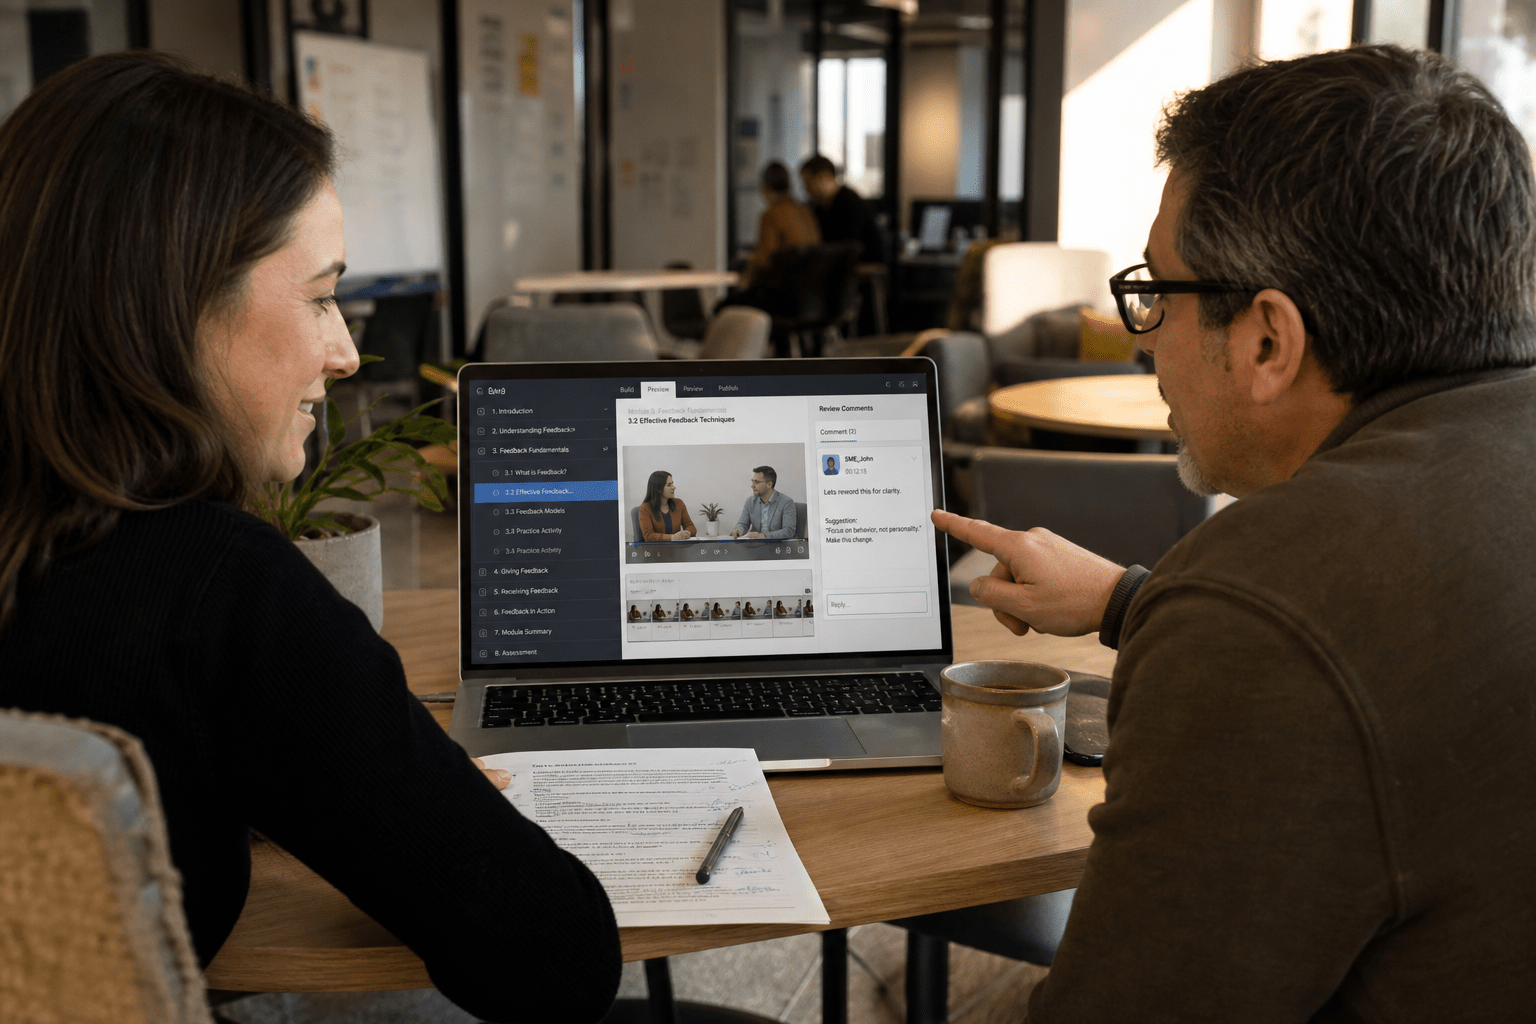
The best AI tools for training and development teams in 2026 fall into four working groups: synthetic video and voice for content that used to need a studio, authoring assistants that convert existing material into structured lessons, skills-inference platforms that read what your people actually do, and practice simulators that let someone rehearse a hard conversation before they have it. Each one removes a different bottleneck, and the bottleneck most L&D teams actually have is not production speed. It is the review loop with subject-matter experts, and the skills data underneath the whole program.
Five Points That Decide Whether L&D Tooling Pays Off
Our team has sat in enough learning-technology reviews to know where these purchases go wrong. Five points decide the outcome:
- The constraint is expert time, not authoring time. A course that takes two days to build and six weeks to get reviewed is a six-week course. Tools that shorten the review cycle beat tools that shorten the build.
- Skills data quality sets the ceiling. Skills-inference platforms infer against your job architecture. If your job titles are inconsistent across the HRIS, the recommendations will be too.
- Synthetic video changes maintenance economics, not just production. The reason it matters is not the first record. It is that a policy change no longer means booking the same presenter again.
- Completion rates are not evidence of behavior change. Any tool that only reports completions is reporting attendance.
- Identity and provisioning decide whether adoption sticks. If a learner has to remember a separate login, usage drops regardless of content quality.
This piece is written for L&D leads and heads of people development at firms of roughly 50 to 500 employees, where there is a real training function but no dedicated learning-engineering team.
Why Training and Development Teams Stall After the Tool Is Bought
Training programs stall because content production is only one stage of a pipeline, and AI has compressed that stage while leaving the stages around it untouched. We see the same pattern across clients: the team buys an authoring assistant, cuts first-draft time from three days to three hours, and ships the same number of courses per quarter as before. The queue moved somewhere else.
The subject-matter-expert review loop
The review loop is where most L&D calendars actually break, and no generation tool fixes it by default. A compliance module on wire-transfer verification needs the controller to confirm the thresholds. The controller has a close cycle. The draft sits for three weeks, comes back with four comments, and one of them changes the branching logic, which means the assessment has to be rebuilt.
The counterargument deserves airtime: faster first drafts do help here, because reviewers respond better to something concrete than to an outline. We have watched review comments get sharper when the reviewer is reacting to a finished screen. Both things are true at once. Faster drafting improves review quality without shortening review latency, and latency is what the calendar feels. The tools that move latency are the ones that let a reviewer record a thirty-second voice note that becomes a tracked change, rather than the ones that write more prose.
The re-record problem in video
Video maintenance is the second stall point, and it is the one synthetic presenters genuinely solve. A traditional recorded module ages badly. The moment a form changes, a system is renamed, or a threshold moves, the video is wrong, and fixing it means finding the original presenter, matching the wardrobe and the room, and re-recording a segment that has to cut cleanly against the old footage. Most teams simply let the module go stale and add a correction slide.
With avatar-based generation from platforms such as Synthesia, Colossyan, or Elai, that same fix is a text edit and a re-render. The trade is real and worth stating plainly. Avatar delivery lands acceptably for procedural and policy content, and it lands poorly for anything where the audience needs to feel a human took a position. Leadership messages and culture content still want a real person on camera.
Translation and accessibility backlogs
Localization is where a small L&D team quietly falls furthest behind. A firm with operations in Boca Raton and a service team in Manila runs the same onboarding twice, and the second version is usually eighteen months behind the first. Machine translation with human review has become good enough that the backlog is now a review-capacity question rather than a translation-cost question. Accessibility follows the same shape: automated captioning and audio description get you most of the way, and the remaining work is verifying that the caption timing matches what an assessment question refers to.
Best AI Tools for Training and Development Teams Across the Content Pipeline
The content pipeline breaks into four tool groups, and the useful way to compare them is by which manual step each one removes. Buying two tools from the same group is the most common overspend we correct.
Authoring and conversion assistants
Authoring assistants convert material you already own into structured lessons, which is where the fastest return sits for most teams. Articulate’s Rise with its AI assistant, Synthesia’s course workflow, and Docebo’s content generation all take a policy document, a recorded webinar, or a slide deck and produce a lesson skeleton with knowledge checks attached.
Where they earn their license is a decade of accumulated material that never got converted. Where they disappoint is net-new content on a topic your firm has no written position on yet. The assistant will produce something fluent and generic, and a reviewer will spend longer correcting a confident wrong draft than writing from a blank page. Our rule with clients: point conversion tools at documents that already carry your firm’s actual practice, and write from scratch when the practice itself is being decided.
Synthetic video and voice
Synthetic presenters remove the scheduling dependency from video production, and that is the change that compounds. A module recorded as text plus an avatar can be corrected the same afternoon a process changes. Voice cloning extends the same benefit to audio-only refreshers.
The honest limitation is trust calibration. Learners increasingly recognize avatar delivery, and in our experience that reads as fine for a systems walkthrough and slightly hollow for anything about conduct or values. Some teams split the difference by keeping a real executive introduction and using synthetic delivery for the procedural body of the same module. That pattern has held up well.
Skills inference and learning paths
Skills platforms such as Degreed, Gloat, and Cornerstone’s skills graph infer capability from work signals rather than from self-assessment, then recommend paths against gaps. This is the group with the widest spread between a good outcome and an expensive one.
They work when your job architecture is coherent. They fail quietly when it is not, and the failure mode is not an error message. It is plausible recommendations built on a taxonomy where “Account Manager” and “Client Manager” are separate roles with different inferred skill sets, so two people doing identical work get different paths. Before licensing one of these, we ask clients to reconcile titles in the HRIS first. That reconciliation is unglamorous and it determines whether the platform produces signal or noise.
Practice and coaching simulators
Role-play simulators let someone rehearse a difficult conversation against an AI counterpart that pushes back, and for sales and support training the evidence from our client base is encouraging. Tools in this group, including Second Nature and Hyperbound, score a rep on discovery questions asked, objections handled, and whether they stated pricing before establishing need.
The caution is scoring validity. A simulator rewards the behaviors it was configured to reward, so a team can improve its simulator scores while its actual close rate stays flat. We treat simulator scores as practice volume rather than as competence measurement, and we validate against a real outcome metric before anyone’s review depends on them.
What Your Data and Identity Stack Has to Support First
Learning tools inherit whatever mess exists in your identity and data plumbing, so the technical groundwork decides adoption more than the content does. Three items come up on nearly every implementation we run.
Single sign-on and automated provisioning come first. A learning platform behind a separate credential loses a measurable share of its audience, and manual seat management means leavers keep access for months. SCIM provisioning against your directory fixes both, and it is the same identity work that underpins a clean Microsoft Teams deployment, so it usually rides along with work already scoped.
Interoperability standards come second. SCORM packages record that someone finished something. xAPI statements record what they did, at what step, and with what result, written to a learning record store you control. If you expect to correlate training against a business outcome later, you need the statement-level data from day one, because you cannot reconstruct it afterward. Teams that skipped this arrive two years later with completion percentages and no way to answer whether the program worked.
Data residency and confidentiality come third, and this is where our security practice usually intervenes. A course-generation tool pointed at internal documents is an outbound data flow. We check whether prompts and uploaded material are retained, whether they train vendor models, and which region processes them. For a client under HIPAA or GLBA obligations, that review is not optional, and it belongs in the same conversation as security awareness training content itself.
Measuring Whether Any of It Worked
Measurement is the stage where AI tooling has helped least and where L&D credibility is won, so it deserves deliberate design rather than whatever the platform reports by default. Completion and satisfaction scores are easy to produce and prove almost nothing. Our approach with clients is to pick one operational metric per program before launch and instrument backward from it.
For a support team, that might be first-contact resolution on the ticket categories the training covered. For a finance team, exception volume on the process the module described. For a sales function, the ratio of discovery calls that reach a next step. None of these require a new platform. They require agreeing, in advance, which existing report will be read ninety days after launch, and making sure the xAPI data can be joined to it.
The one place AI genuinely helps measurement is qualitative synthesis. Reading four hundred free-text feedback responses used to be a week of someone’s life, so nobody did it, and the free-text field became decoration. Clustering that feedback and surfacing the recurring objection is now an afternoon. We have found more useful program signal in that pass than in any dashboard, particularly on the modules where satisfaction scores were fine and behavior had not moved.
Who Is Behind This Guidance
Mindcore has run learning-platform integrations, identity rollouts, and AI deployments for professional-services firms, healthcare providers, and manufacturers across New Jersey, Florida, and the Gulf region. Most of the L&D work we take on starts as a content problem and turns out to be an identity, data, or governance problem underneath, which is why our teams pair a learning-technology lead with a security engineer on these projects rather than treating them as a software install. We have seen enough of these programs to know which sequencing holds up over two years and which produces a strong first quarter and a stalled second year.
Matt Rosenthal, Mindcore’s chief executive, focuses the practice on AI adoption that survives contact with real operations, which in this domain means measurable behavior change and a defensible data posture rather than tool count. That perspective shapes how we scope every one of these engagements, including the ones where our recommendation is to fix the job architecture before buying anything.
Frequently Asked Questions
What are the best AI tools for training and development teams starting out?
Start with a conversion assistant pointed at material you already own, because that is where the return arrives fastest and the risk is lowest. Most teams get more value in the first quarter from converting a backlog of existing policy documents into structured lessons than from adding a skills platform. Skills inference and simulators are better second-year purchases, once the content library and job architecture can support them.
Can AI replace instructional designers?
No, and the pattern we observe is a shift in what the role spends time on rather than a reduction in headcount. Generation tools absorb first-draft production, which moves designer time toward learning architecture, assessment validity, and managing expert review. The teams getting the most from these tools have kept their designers and changed their job description.
How do synthetic video tools handle a policy change mid-year?
A synthetic module is corrected by editing the script and re-rendering the affected scene, which typically takes hours rather than the weeks a live re-record needs. That maintenance profile is the strongest argument for avatar-based delivery on procedural content. Keep a human presenter for leadership and conduct topics, where audiences respond to a real person taking a position.
Do we need xAPI if our LMS already reports completions?
If you ever intend to connect training to a business outcome, yes, because completion records cannot be decomposed into the behavior data that analysis needs. xAPI statements capture the individual interactions, written to a learning record store you own, and that history cannot be reconstructed later from completion logs. Teams that defer this decision usually regret it in year two.
What is the most common mistake in AI-assisted learning programs?
Buying two tools from the same functional group while leaving a different stage of the pipeline untouched. We regularly find a client running an authoring assistant and a separate course-generation feature inside their LMS, with no work done on expert review latency or skills data. Map the pipeline before the purchase and buy against the stage that is actually blocked.
Book a Free Strategy Call Before Your Next Platform Renewal
Training and development tooling in 2026 rewards teams that fix sequencing before they add software, and punishes the ones that buy against the loudest demo. The pattern that holds up is consistent: shorten expert review latency, reconcile the job architecture your skills data depends on, get single sign-on and statement-level analytics in place, then choose tools per pipeline stage rather than per vendor pitch. Firms that follow that order tend to keep their programs running two years later, and the ones that start with procurement tend to be rebuilding by then. The same logic applies to the adjacent decisions on your desk, whether that is choosing collaboration tools, weighing Microsoft Teams and its alternatives, unifying business communications onto one stack, or standing up Microsoft 365 training for the platform your people already have. If you want a second opinion on a renewal or a rollout plan, our AI implementation training practice runs these reviews regularly, and the same principles we apply to how we train AI agents with in-house teams apply here. Book a free strategy call and we will map your pipeline against the stage that is actually blocking you.

