Most AI usage audits produce a clean report about the wrong population. The register lists four approved tools, the audit tests those four, and the firm is actually running eleven, seven of which arrived through browser extensions, expense claims and features switched on inside software already licensed. Every control conclusion drawn from an incomplete register is drawn from the wrong universe, which is the same failure mode that invalidates a sample in any other audit. Discovery is not the preliminary step here. It is most of the work.
Overview: five reasons AI usage audits reach the wrong conclusion
- The register is not the population. What the firm approved and what the firm runs are different lists, and only one of them can be audited meaningfully.
- AI arrives as a feature, not a purchase. Suites the firm already pays for switch on assistants by default, so nothing appeared in procurement and nobody made a decision.
- Prompt logs are rarely retained. The record of what was sent to a model is the evidence an auditor needs, and most deployments keep none of it.
- Human oversight is asserted, not evidenced. A control saying outputs are reviewed before use needs an artifact showing a person reviewed a particular output on a particular day.
- Model changes leave no change record. A vendor updating a model behind an API alters system behaviour with no entry in any change log the firm controls.
This is written for compliance leads and operations directors at firms between 25 and 500 people who have been asked to demonstrate control over AI use, often by a customer questionnaire or an insurer. If your concern is securing agent deployments rather than auditing usage, our piece on enterprise AI compliance covers that side.
Why discovery decides the outcome of an AI usage audit
Shadow AI discovery is the step that determines whether the rest of the audit describes reality, and it is the step most methodologies compress into a single line about interviewing stakeholders. Interviews find what people remember using, which underreports badly.
Four discovery sources that each find different tools
Asking teams what they use finds the tools people think of as tools. It misses features inside existing software and anything somebody would rather not mention. Four sources together give a far better population than any one.
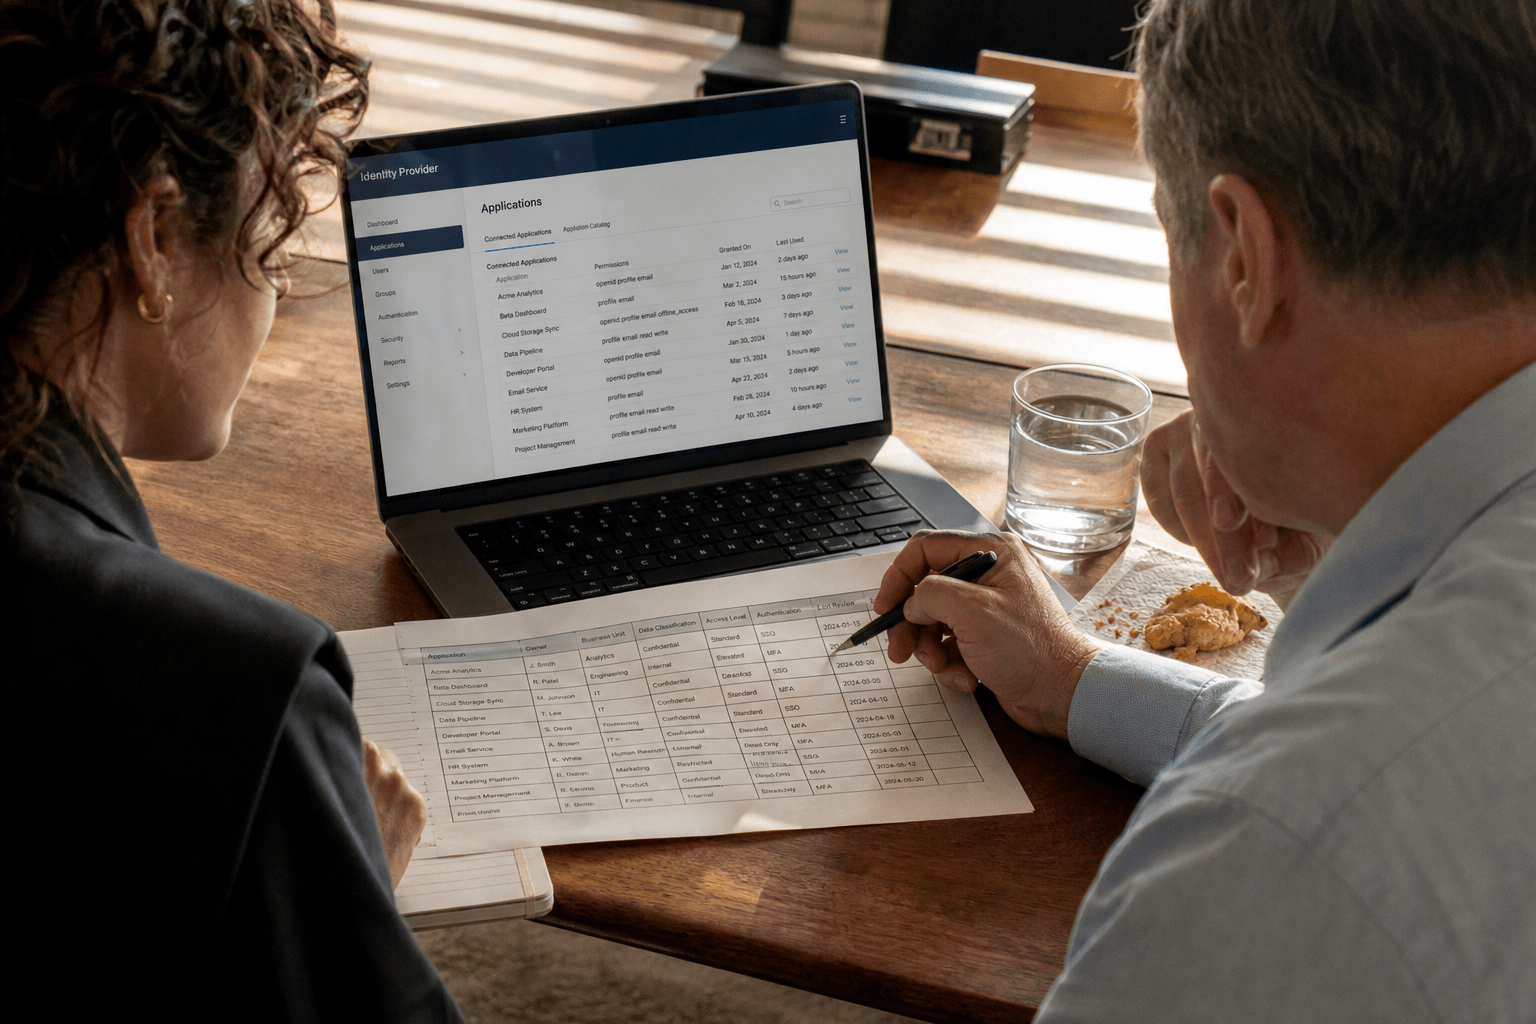
Identity provider OAuth grants show every third party application holding access to company data, including ones installed by individuals years ago. Expense and card data shows individual subscriptions bought outside procurement. Network or browser telemetry shows domains being reached. Licence consoles for the suites you already own show which assistant features are enabled and by how many people.
The objection that this is disproportionate for a fifty person firm is fair on effort and wrong on outcome. Three of the four are reports somebody can run in an afternoon, and the overlap between them is small enough that skipping one leaves a real gap. The access side of this overlaps with our guidance on auditing user access rights.
Features that arrived without a purchase decision
A meeting platform enabling automated notes, a CRM adding a summarisation panel, an email client offering drafting assistance: none of these went through procurement, none has an owner, and all of them process company content.
There is a genuine argument that these carry less risk than a standalone tool, because they sit under an agreement the firm already negotiated with a vendor it already assessed. That is often true and it does not remove them from the register. Record them, note the agreement that covers them, and move on. The work is inventory, not investigation.
Tools that left when the person did
Individually adopted tools frequently keep their access grant after the employee departs, because offboarding covers accounts the firm knows about. The OAuth grant list is where these show up, and it is why that list is worth reading rather than counting.
The reasonable pushback is that a suspended account cannot authorise anything, so the grant is inert. That holds for grants tied to the user session and does not hold for anything issued against a service account, a shared mailbox, or a workspace level install that outlives the person who set it up. Reading the list means checking which identity each grant sits against, which takes longer than counting rows and is the only version of the task worth doing.
The artifacts an AI usage audit actually needs
Prompt log retention and oversight records are the two evidence categories that most often do not exist, and both need a decision before the audit rather than during it. What follows is the artifact set that makes a usage control testable.
A use case register with a named owner per entry
The register should list each AI use case rather than each tool, because the same tool carries very different risk across uses. Drafting internal notes and screening job applicants are not the same control problem even inside one product.
Each entry needs an owner, the data categories involved, whether an output affects a person’s rights or access to a service, and the agreement covering the vendor. That last field is what turns the register from a list into something a customer questionnaire can be answered from. Our AI risk assessment work usually starts by building exactly this.
Prompt and output logs, retained long enough to sample
Testing whether a control operated requires looking at what actually happened on a given day, which means retaining inputs and outputs. Most deployments retain nothing by default, and enterprise tiers frequently offer retention that nobody has switched on.
The counter argument is real and important: prompt logs contain whatever staff typed, including personal and client information, so retaining them creates a new data holding with its own obligations. The resolution is scope, not avoidance. Retain for the use cases where an audit will genuinely ask, set a defined period, restrict access to the logs, and document that decision. Retaining everything indefinitely is its own finding.
Evidence that a human actually reviewed an output
Controls in this area almost always claim human oversight, and the artifact proving it almost never exists. A reviewer clicking accept in an interface that records nothing has performed the control and cannot evidence it.
Where the workflow passes through a system of record, the approval is captured for free. Where it does not, the practical fix is to route outputs that matter through something that timestamps a decision, even if that is a simple ticket. This mirrors the evidence discipline in our guidance on preparing for a compliance audit.
A change record for something you do not control
Traditional change management assumes the firm decides when systems change. Behind a hosted model API that assumption breaks: a vendor can alter behaviour, retire a version, or adjust a safety layer, and the first the firm knows is a shift in output quality.
Some argue this makes change control meaningless here, and the better reading is that it moves the record from authorisation to observation. Pin an explicit model version where the platform allows it, subscribe to the vendor’s change notifications, and log every version move you become aware of with a date and an impact note. That is a defensible record even though you did not approve the change.
Vendor terms captured alongside the use case
The agreement covering each entry is what answers the two questions a customer questionnaire always asks: whether inputs are used for training, and where processing occurs. Capturing those at register time rather than chasing them during an audit is the difference between a two day response and a two week one.
The complication is tiering inside a single vendor. The same product name can carry different terms on developer and enterprise plans, and a team that started on a trial may still be on it. Record the tier, not just the vendor, and check it against the invoice rather than the product page.
How to run the audit without stalling the business
An AI usage audit that arrives as a prohibition produces concealment, which makes the next audit worse. The firms that end up with accurate registers are the ones where declaring a tool was easier than hiding it.
Amnesty first, policy second
Running discovery with a stated amnesty, where nothing declared during the window is treated as a disciplinary matter, produces a materially better population than running it as an enforcement exercise. People know what they are using. Whether they tell you is a function of what happens next.
The objection is that amnesty signals tolerance for policy breaches, and for a firm with a clearly communicated existing policy that concern has weight. Where no policy existed, which is most firms, there was nothing to breach and treating it as misconduct is both unfair and counterproductive.
Tiering use cases so review effort lands where risk is
Auditing every use case to the same depth is how a programme becomes annual theatre. Tier by whether an output affects a person’s rights, touches regulated data, or reaches a customer, and review the top tier properly while recording the rest.
The risk of tiering is that everything gets classified low and the exercise becomes decorative. Guard against it by defining the tiers before you classify anything, and by having somebody other than the use case owner confirm the tier. Governance design for the higher tiers is covered in our piece on enterprise grade AI agent governance.
Setting a cadence that matches how fast this moves
Annual review is the default and it is too slow for a category where a vendor can change model behaviour in a release note. Quarterly discovery reruns, using the same four sources, catch new arrivals while they are still small.
Continuous monitoring is the stronger answer where the tooling supports it, and it is what our AI operations monitoring work provides for clients running production systems. For everybody else, a quarterly rerun of four reports is achievable and far better than nothing.
Frequently Asked Questions
What should an AI usage audit cover first?
Discovery, using at least the identity provider OAuth grant list, expense data, network or browser telemetry, and the licence consoles of suites you already own. A control conclusion drawn from an incomplete register is drawn from the wrong population, which invalidates everything downstream.
Do we need to retain prompt logs for AI compliance?
Retention is what makes a usage control testable, because an auditor samples what happened on specific dates. Scope it to the use cases where that question will genuinely be asked, set a defined period, restrict access, and document the decision rather than retaining everything indefinitely.
How do you evidence human oversight of AI outputs?
Route the outputs that matter through a system that timestamps who approved what and when. A reviewer accepting an output in an interface that records nothing has performed the control and cannot prove it, which is the most common gap in this area.
How often should AI usage be audited?
Quarterly discovery reruns work well for most firms at this size, because the same four reports can be regenerated quickly. Annual review alone is too slow for a category where vendors change model behaviour inside a normal release cycle.
Does AI usage compliance apply to features inside software we already license?
Yes, and those are the entries most often missing from a register. An assistant switched on inside an existing suite processes company content the same way a standalone tool does, even though nothing went through procurement.
Who is behind this guidance
Mindcore runs compliance and security programmes for small and mid sized firms across healthcare, legal, financial services and manufacturing, and most of our AI audit work begins with a discovery pass that finds two to three times what the client expected. The approach above comes from cybersecurity compliance and cyber security audit engagements where the register was the deliverable that mattered most.
Matt Rosenthal, our chief executive, focuses on how firms take on new capability without losing track of where their data goes. His position on AI audits is that the number people find uncomfortable, which is how many tools are actually in use, is the most useful output of the whole exercise.
Start with discovery, not with policy
The sequence that produces an accurate picture is short. Run the four discovery sources and reconcile them into one list. Offer an amnesty so people declare what the reports miss. Build a register by use case rather than by tool, with a named owner and the covering agreement on each entry. Decide retention deliberately for the use cases that will be sampled. Route consequential outputs through something that records who approved them. Then write the policy, informed by what you found rather than by what you assumed.
If you want help running that first discovery pass, book a free strategy call and we will pull the four reports with you.