

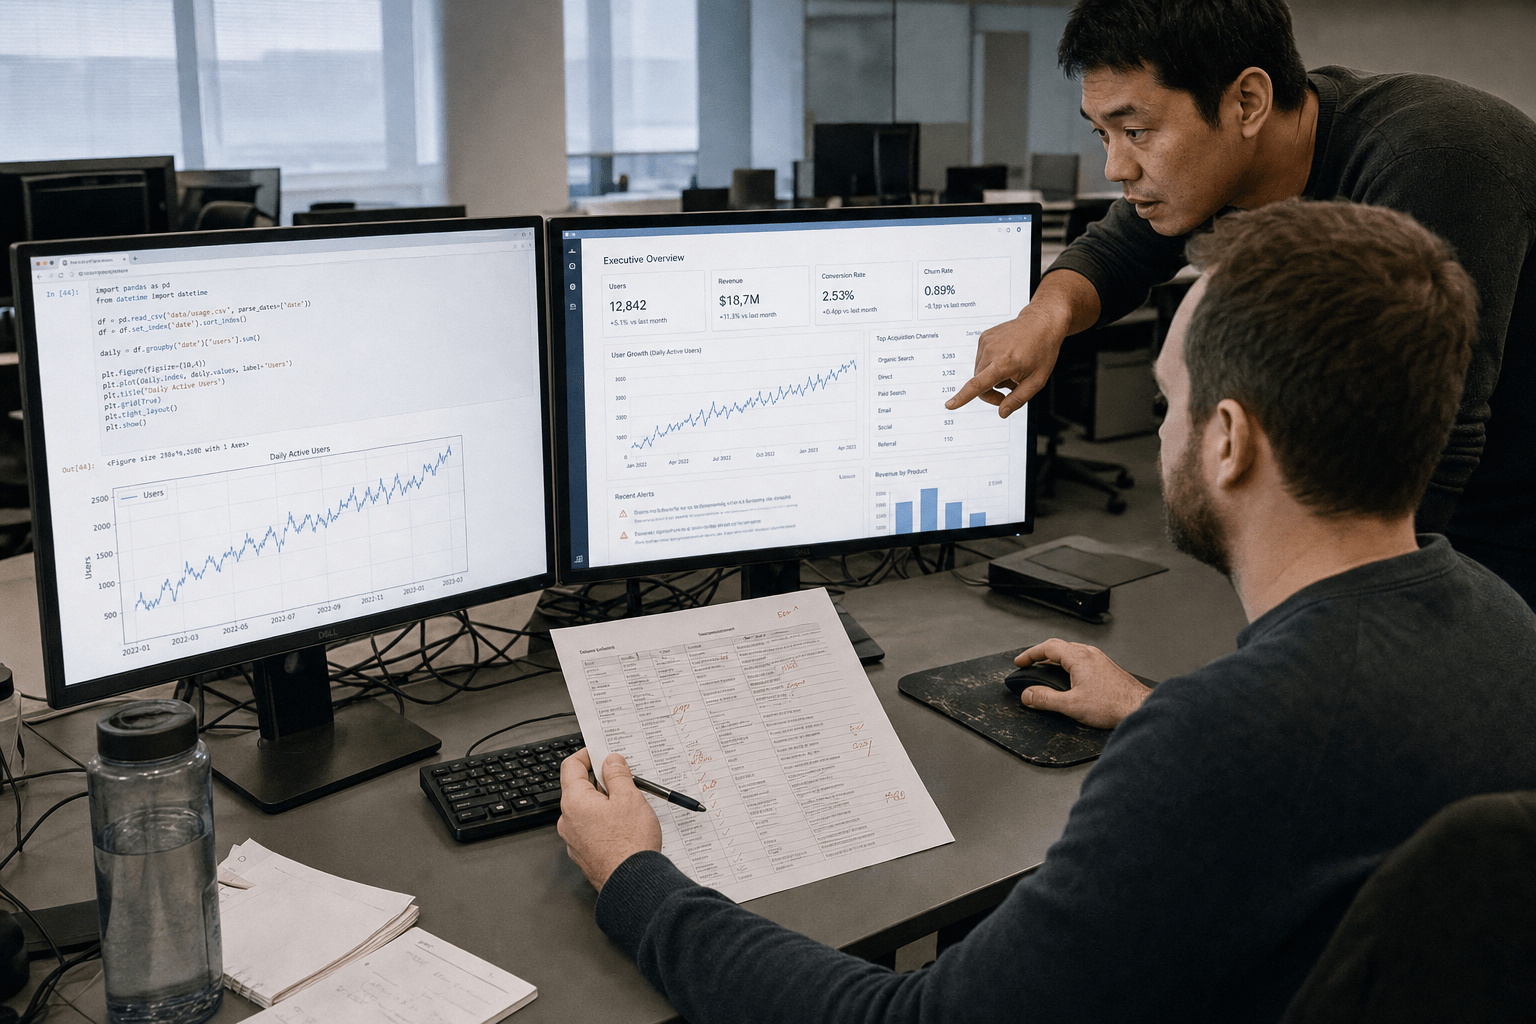
The best AI tools for data analysts in 2026 fall into three tiers. Conversational tools such as Julius let an analyst interrogate a spreadsheet or dataset in plain language, and general assistants including Claude, ChatGPT, and Gemini handle a wide range of exploratory work, with code execution behind the scenes for uploaded files. Notebook environments such as DataCamp DataLab pair managed Python, R, and SQL with an assistant that writes, explains, and repairs code. Enterprise platforms including Power BI Copilot and DataRobot sit closest to governed data. Producing an answer has stopped being the hard part. Knowing which answers hold up is the job now.
Five Things to Settle Before Adding a Tool
We put these five to analytics and data leaders, because they shape whether the tooling produces insight or confident noise.
- Fluent output is not validated output. These tools state results with equal confidence whether the underlying join was correct or quietly duplicated half the rows. Verification remains an analyst’s task.
- Uploading data is a governance decision. Dropping a customer export into a browser tool moves regulated data to a third party, and it takes about four seconds.
- Match the tool to where the data already lives. If everything sits in a warehouse behind access controls, a tool that requires uploading files fights your architecture rather than fitting it.
- Definitions matter more than models. If active customer means three things in three departments, every tool will confidently answer the wrong question.
- Reproducibility is what makes an answer defensible. A conversational session producing a number nobody can reproduce next quarter is not analysis, it is an anecdote.
The Constraint Moved From Producing Answers to Trusting Them
Analysis tooling has made generating a result nearly effortless, and in doing so it moved the bottleneck to verification, which is the part organizations have not staffed for. This is the shift worth understanding before buying anything. A business stakeholder can now upload a file, ask a question in plain language, and receive a chart with a narrative explanation inside a minute. Nothing in that interaction indicates whether the join multiplied rows, whether the date filter excluded a time zone edge, whether nulls were dropped silently, or whether the metric matches the definition finance uses. The output looks identical in every case. Analysts have always faced this, and their training and habits caught most of it. What changed is that people without that training now produce results at volume, and those results arrive in meetings carrying the same visual authority as a properly built analysis.
Semantic Definitions Are the Highest Leverage Fix
Agreeing what your core metrics actually mean returns more than any tool on this list, and most organizations have never written them down. The symptom is familiar. Marketing reports one customer count, finance reports another, and the operations dashboard shows a third, and each is correct under its own unstated definition. Introduce conversational analysis into that and the disagreement multiplies, because now anyone can generate a number in seconds and defend it with a chart. The fix is a documented semantic layer: one written definition per core metric covering inclusions, exclusions, and timing, agreed across the functions that use it, and implemented in the warehouse or BI layer so tools inherit it rather than each inventing its own. This is unglamorous work that competes poorly for attention against a new platform, and it is the difference between analytics that settles arguments and analytics that starts them. Our note on AI in data management covers the wider picture.
Reproducibility Separates Analysis From Anecdote
A result that cannot be reproduced is not usable for a decision anyone will be held to, and conversational tools make irreproducible results very easy to create. The pattern is subtle because nothing appears wrong. An analyst explores a question in a chat interface, iterates through several refinements, arrives at a compelling figure, and pastes it into a deck. Three months later somebody asks how it was calculated, and the session is gone or the underlying extract has been superseded. Nobody was careless. The medium simply does not preserve method the way a notebook or a version controlled query does. Teams that handle this well use conversational tools for exploration deliberately, then rebuild anything heading for a recurring report or a board pack in a reproducible form. Notebook environments help here precisely because they keep the code, the output, and the commentary together in one artifact somebody can rerun.
Best AI Tools for Data Analysts by Working Style
The best AI tools for data analysts divide by how the analyst works and where the data sits, rather than by capability rankings that ignore both. Exploration tools are judged on time to a first useful view. Notebook assistants are judged on whether they shorten the debugging loop. Enterprise platforms are judged on whether the answer inherits governed definitions. Here is where the field currently stands.
Conversational Exploration and General Assistants
Conversational tools have the lowest barrier and the widest reach. Julius is the fastest starting point for interrogating a spreadsheet or dataset in natural language, and it suits the question that arrives without warning and needs an answer this afternoon. Among general purpose options, Claude, ChatGPT, and Gemini all handle analytical work capably, with ChatGPT’s data analysis capability running Python behind the scenes across CSV, Excel, JSON, and image based data. Claude handles long, dense documents and large context work particularly well, which matters when the analysis involves specifications or reports alongside the numbers. The honest limitation applies to all of them equally. They work on what you upload, they do not see your warehouse, and they cannot know your business definitions unless you tell them. For exploration and for the ad hoc question they are excellent. For a recurring metric they are the wrong place to end up.
Notebook Environments and Code Assistance
Notebooks remain where serious analytical work lives, and AI has improved the experience considerably without changing the fundamentals. DataCamp DataLab provides a browser based notebook with managed Python, R, SQL, and database connections, plus an assistant that generates and edits code, explains errors, and turns an analysis into a shareable report. The genuine gain here is the debugging loop. An analyst who previously lost twenty minutes to an obscure library error now resolves it in two, and that compounds across a week far more than faster initial code generation does. Coupler works well for recurring data collection and reporting, and Powerdrill spans datasets and documents together. The discipline that makes this category valuable is unchanged from before AI arrived: keep the notebook runnable end to end, keep the data source referenced rather than pasted, and keep it somewhere a colleague can find it.
Enterprise BI and Automated Modelling
Enterprise platforms are the right answer when the data already sits under governance and the question needs to inherit that. Power BI Copilot is a strong fit for business analysts in Microsoft environments, integrating with Excel, Teams, and Azure while generating DAX, summarizing dashboards, and producing reports from natural language prompts. Its advantage over uploading a file to a browser tool is structural rather than cosmetic: the data stays inside the tenant, inherits the access controls already configured, and uses the semantic model the organization defined. DataRobot occupies different ground, automating the machine learning pipeline end to end by running many model configurations, ranking performance, and explaining results, which suits teams with a genuine prediction problem rather than a reporting one. Domo and similar platforms cover the governed dashboard layer. For most organizations this tier is where recurring reporting belongs, with the conversational tools reserved for exploration. A practical note on natural language querying in this tier, since expectations often run ahead of reality. These features work impressively against a well built semantic model with clear table relationships and sensible naming, and they perform poorly against a warehouse where tables carry cryptic names and relationships are implied rather than defined. The capability is real, and it is a multiplier on modelling work already done rather than a substitute for it. Organizations disappointed by a natural language feature have usually pointed it at an underlying model that a new analyst would also struggle to navigate, which is diagnostic: if a competent human needs a week to learn your warehouse, the assistant will not shortcut that.
Self Service Changes the Analyst’s Job Rather Than Removing It
When business users can generate their own analysis, the analytics team’s work shifts from producing answers to curating what people are analyzing, and teams that miss this shift get overwhelmed. The predictable sequence runs like this. Self service tooling arrives, the analytics queue shortens pleasingly, and within a quarter the team is spending its time adjudicating between conflicting numbers produced by different departments, each defended with a chart. That is not a failure of self service, it is the natural consequence of removing a bottleneck that was also, quietly, a consistency check. The teams that navigate it well change what they own. They build and maintain the curated datasets people analyze against, so that a business user asking a question starts from data that already carries the right definitions and the right filters. They publish a small number of certified metrics and make it clear which figures are authoritative. They spend their remaining time on the harder questions self service cannot reach. This is a more valuable role than answering routine requests, and it is worth naming explicitly during planning, because analysts who expected their job to get easier and instead find it changed shape tend to be the ones who leave.
What Analytics AI Needs From Data Governance
Analytics tooling multiplies whatever governance posture an organization already has, improving good ones and exposing weak ones quickly. The core exposure is easy to describe. An analyst with legitimate access to a customer dataset can move it to a third party platform in seconds, with no malice and often no awareness that the action has regulatory weight. Personal data, health information, and payment detail all carry obligations that follow the data rather than staying with the system it came from. The controls that work are practical: publish which tools may handle which data classifications, prefer platforms that connect to governed sources over those requiring uploads, and make the approved route easier than the workaround. Our guide to keeping cloud data secure covers the platform side, and gaining control over company data and devices covers the distributed working angle that makes this harder.
Two further points deserve naming because they are consistently underweighted. First, analytical work depends on data that is available, which makes backup and recovery an analytics concern rather than only an infrastructure one, and the value of a recovery plan is entirely determined by whether it has been tested, a point we cover in how often to test your backup and data recovery plan. Second, analysts often hold the broadest read access in the organization, spanning customer, financial, and operational systems, which makes those accounts a high value target and makes it worth knowing in advance how a compromise would be handled. Understanding the data breach response path before it is needed is considerably cheaper than improvising it, and the first hours of an incident are when the improvisation costs most.
Frequently Asked Questions
What are the best AI tools for data analysts right now?
Julius is the fastest conversational starting point for spreadsheets and datasets, with Claude, ChatGPT, and Gemini strong as general purpose options. DataCamp DataLab leads managed notebook environments. Power BI Copilot suits business analysts in Microsoft environments, and DataRobot automates modelling for genuine prediction problems.
Can AI replace a data analyst?
No, and the reason has shifted. Generating a result is now easy, so the analyst’s value has moved toward knowing which question to ask, whether the data supports the answer, and where a plausible looking number is wrong. Those judgments require understanding of the business and the data’s history that no tool holds.
Is it safe to upload company data to AI tools?
That depends entirely on the data and the tool. Customer records, health information, and payment detail carry obligations regardless of how convenient the upload is. Prefer tools that connect to governed sources over those requiring uploads, publish clear rules on data classifications, and confirm what each vendor retains and trains on.
What is the difference between conversational tools and BI platforms?
Conversational tools work on what you give them and excel at exploration and ad hoc questions. BI platforms connect to governed data, inherit existing access controls and metric definitions, and produce results that are reproducible. Use conversational tools to explore, and put anything recurring into the governed layer.
How do we stop AI producing wrong answers from our data?
Document your metric definitions and implement them in a semantic layer so tools inherit them rather than inventing their own, keep anything recurring in a reproducible form, and maintain the habit of validating a surprising result before acting on it. Most wrong answers trace to definitions or joins rather than to the model.
Who Is Behind This Guidance
Mindcore works with organizations on the data infrastructure analytics depends on: access control across the systems analysts read from, secure connectivity for distributed teams, backup and recovery that has actually been tested, and the vendor reviews that decide whether a platform should receive company data at all. That is why this article leads with definitions and reproducibility rather than with a product ranking. We have seen organizations adopt capable tooling and end up with more disagreement rather than less, because three departments were each confidently answering a slightly different question. Matt Rosenthal, who leads Mindcore, has aimed the company at organizations in exactly this position: data valuable enough that the obligations are real, teams lean enough that nobody internally has room to own the technology. The analysis and the judgment stay with your team. Making the foundations dependable is ours.
Book a Free Strategy Call Before Your Next Analytics Purchase
Choosing among these tools becomes far clearer once an organization knows where its data lives, which definitions are agreed, and what analysts are permitted to move. Exploration, notebook work, and governed reporting are three different needs, and a team that matches the tool to the need stops paying for capability it cannot safely use. Ahead of the next purchase, write down the definitions for your core metrics, decide which data classifications may leave governed systems, and check that the recovery plan behind your analytical data has been tested rather than merely documented. Those three determine whether the answers your tooling produces are ones the business can act on. If you want an outside read on where your environment stands, we will assess it and say plainly what to address first. Book a free strategy call with our team. Teams weighing the wider tooling question may also find how to choose the best team collaboration tools and our overview of IT tools for growing organizations worth reading.

