Document fraud detection is decided by where you set the threshold, not by which model reads the image. Every product in this category will tell you its accuracy on a benchmark set. What none of them can tell you is what a false positive costs your business, and that number governs everything: a wrongly rejected applicant is a lost customer and sometimes a complaint, while a missed forgery is a loss you can quantify after the fact. Teams that pick a product before deciding that trade end up tuning it by complaint volume, which is an expensive way to discover your own risk appetite. Here is what the tooling genuinely detects, where it fails, and how to set that threshold deliberately.
Overview: 5 Points to Settle Before Evaluating Products
- Decide the cost of both errors first. A false positive and a missed fraud have different costs, and the ratio between them is your threshold.
- Tampering and template forgery are different problems. Detecting an altered genuine document uses different signals from detecting a document that was never real.
- Image quality sets the ceiling. A phone photo at an angle in poor light limits what any model can conclude, and how the product behaves on bad input matters more than its best case accuracy.
- The review queue is part of the system. Every threshold produces a referral volume, and a queue nobody can staff means the detection quietly stops mattering.
- Retention of identity documents is a liability. Holding images of passports and licences longer than you need creates an obligation that outlasts the fraud they prevented.
Why Document Fraud Detection Is Harder Than It Looks
Detection is difficult because the adversary iterates and the honest customer does not. A fraudster testing a forged template learns immediately whether it passed, while a genuine applicant with a damaged licence simply gets rejected and goes elsewhere. Our enterprise AI integration practice works through the three problems below with clients before any product shortlist, because each changes what a good result looks like.
Altered documents and fabricated documents need different signals
An altered document is genuine underneath: a real bank statement with a changed balance, a real utility bill with a substituted address. The signals are internal inconsistencies, font mismatches within a line, compression artefacts around edited regions, metadata showing an editing application, and arithmetic that does not add up.
A fabricated document was never genuine. Here the signals are comparisons against known templates: layout geometry, security features, machine readable zone checksums, fonts specific to an issuing authority. Different analysis, different failure modes.
The argument for one product covering both is operational simplicity, and the better platforms genuinely do. The point of separating them is evaluation: test with both kinds of sample, because a product strong on template verification can be weak on subtle alteration and still show a single impressive accuracy figure. Ask which of the two a vendor’s headline number was measured on.
The false positive cost is real and usually unmeasured
Rejecting a genuine customer costs the acquisition spend, the lifetime value, and occasionally a regulatory complaint. Most organisations have never put a number on it, so the threshold gets set where the vendor’s default put it.
There is a fair argument that in high risk contexts the asymmetry runs the other way, and a rejected customer is far cheaper than a fraudulent account. That is true for some lending and payments work, and it is a reason to set the threshold deliberately rather than a reason to ignore the cost.
The practical method is to estimate both numbers even roughly. Take your fraud loss per incident, take your customer acquisition cost plus expected margin, and the ratio tells you how many false rejections one prevented fraud is worth. Most teams find the answer is a much lower number than their configuration implies. Financial services firms working through the same calculation will find context in our review of AI tools for financial services firms.
Capture quality limits everything downstream
Most document images arrive from a phone camera held by someone in a hurry. Glare across a hologram, a corner cut off, a shadow across the date of birth: all of these degrade analysis, and a model asked to judge a poor image will either guess or refuse.
Some teams respond by tightening capture requirements, rejecting images that fail a quality check and asking for another. That improves detection and adds friction at exactly the moment a customer is deciding whether to continue.
The better arrangement separates the two decisions. Judge capture quality first and coach the user through a retake with a clear reason, then run fraud analysis only on an image good enough to support a conclusion. That way a quality failure never masquerades as a fraud signal, which is the confusion that produces both wrongly rejected customers and unexplainable referral queues.
Where AI Vision Genuinely Helps
Three applications are mature enough to rely on, with the caveats attached.
Detecting alterations in structured financial documents
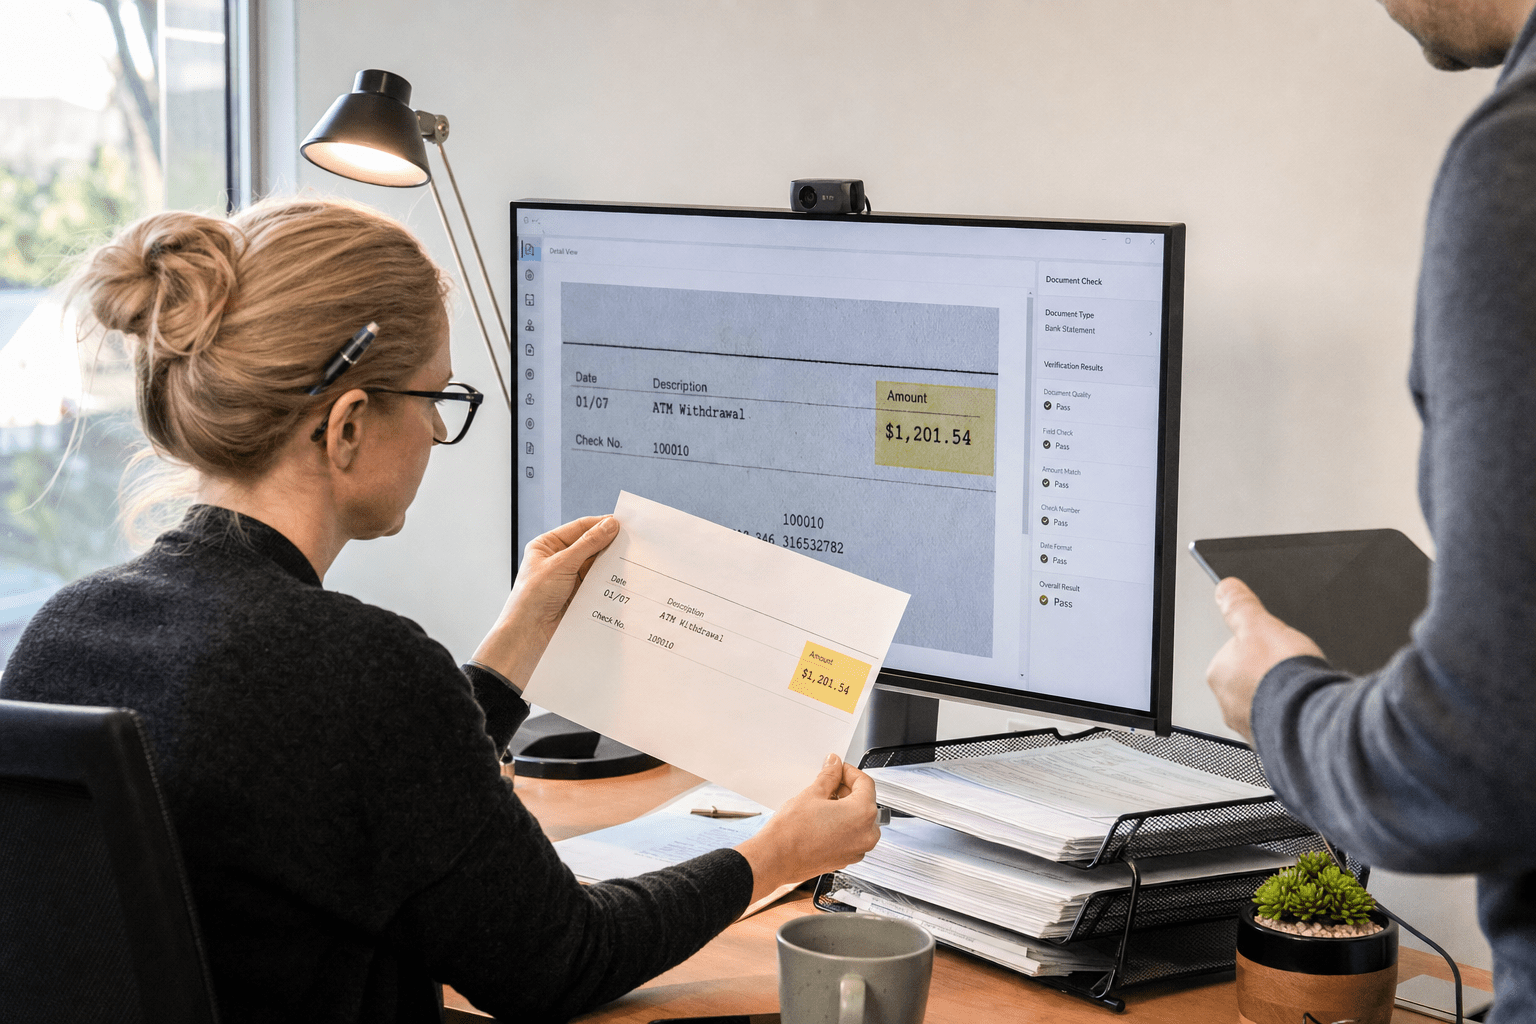
Bank statements, pay slips and invoices have predictable structure, and inconsistency in that structure is strong evidence. Totals that do not match line items, fonts that differ within a column, spacing anomalies where a number was replaced, and document metadata naming an editing tool are all detectable with high confidence and are explainable to a reviewer.
The honest limit is that a competent forger producing a document from scratch in the right template defeats internal consistency checks, because a fabricated statement is internally consistent by construction. Consistency analysis catches the common case, not the careful one. The technical distinctions here are covered in our comparison of AI document processing and traditional tools.
Accounts payable is the version of this problem most businesses actually meet, and it looks different from customer onboarding. The document is an invoice from a supplier you already work with, and the alteration is usually the bank details rather than the amount, since a changed account number attracts less attention than a changed total. The signals that help are cross document rather than within document: these bank details differ from the ones on file, this invoice number is out of sequence for this supplier, the layout differs subtly from their last twelve invoices. That comparison needs history, which means connecting the detection to your accounting system rather than running it on a single file in isolation. Treat any product that cannot see your supplier history as solving a different problem from the one you have.
Identity document verification against known templates
Passport and driving licence verification is the most mature part of this field. Checking layout against the issuing authority’s template, validating machine readable zone checksums, confirming fonts and security feature placement, and matching the portrait against a live selfie together produce a reliable result on good input.
Two cautions. Template coverage varies by country and by document version, so confirm coverage for the documents your customers actually present rather than accepting a headline count. And matching accuracy has historically varied across demographic groups, which is both a fairness problem and a business problem, so ask for performance broken down rather than as a single figure, and monitor referral rates by segment once live.
Presentation attacks are the third consideration and the one vendors describe least clearly. A photograph of a screen showing a licence, a printed copy held to the camera, or a deepfaked video in a liveness check are all attacks on the capture step rather than on the document, and they are countered by different techniques: screen glare and moire detection, depth cues, challenge prompts during capture. Ask which of those the product performs and whether liveness runs on the device or on the server, since a device side check can be bypassed by an attacker who controls the device. This field moves quickly enough that a control adequate last year deserves re-testing now.
Triaging a review queue rather than deciding alone
The strongest deployments use vision analysis to rank and explain rather than to accept or reject. A reviewer receives the document with the specific regions flagged and the reason stated, which turns a five minute judgement into a thirty second confirmation and leaves the decision with a person.
That design also degrades safely. If the model is wrong, a human sees why it thought otherwise, rather than a customer receiving an unexplained rejection. It is the same pattern that works across AI agents in financial services: the system assembles the evidence and a person owns the outcome.
Queue design is where this either works or quietly fails. A referral rate of three percent sounds small until it meets a volume of 900 applications a day, and a queue that grows faster than it is worked turns into an approval backlog that somebody eventually clears by batch approving. Size the referral rate to the reviewers you actually have, not to the risk appetite you would like, then work the threshold down as the review process gets faster. Track the age of the oldest item in the queue as the health metric rather than the count, because an average hides the applications that have been waiting three days and are already lost.
Monitoring for drift after go live
The performance measured during evaluation is the performance on that month’s fraud. Attack patterns change, issuing authorities reissue document designs, and a model that was accurate in January can quietly lose ground by August with nothing in the interface announcing it. The failure is silent because a missed fraud looks exactly like an honest customer until the loss appears, sometimes months later.
Build the feedback loop at deployment rather than after the first surprise. Every confirmed fraud that got through, and every referral a reviewer cleared as genuine, is a labelled example, and counting both monthly gives you a trend rather than an anecdote. Where the vendor retrains centrally, ask how often and whether you can see the effect on your own referral rate. Where they do not, the trend is the only warning you will get.
How to Compare AI Vision Tools for Document Fraud Detection
Five questions, tested with your own documents. What is the referral rate at the threshold you intend to use, measured on a sample of your real traffic. Does the output explain which region triggered the flag, in a form a reviewer can act on. What is the coverage for the exact document types and issuing countries you see. How does the product behave on poor capture, and is that reported separately from a fraud signal. How long are submitted images retained, where, and can that be configured.
The retention question is the one most likely to be answered vaguely, and it matters because identity documents are among the most sensitive data any business holds. Holding them longer than the decision requires converts a fraud control into a breach exposure, which belongs in the same review as the rest of your cybersecurity posture and, where you carry formal obligations, your compliance programme. The broader tooling picture is covered in our survey of AI cybersecurity tools.
Frequently Asked Questions
How accurate is AI document fraud detection?
Accuracy figures are only meaningful against a stated document mix and threshold. Ask what the referral rate would be on your traffic at the setting you plan to use, since that number determines both the fraud you catch and the customers you turn away.
Can it detect a document that was never genuine?
Template comparison catches most fabricated documents, including checksum and layout errors that are hard to reproduce. A well made forgery using a correct current template is the hardest case, and it is why identity verification usually combines document checks with a live portrait match.
What about documents from countries with limited template coverage?
Coverage is uneven and thinner outside major issuing countries. Confirm the specific documents your customers present, and plan a manual path for those outside coverage rather than letting them fail as suspected fraud.
Does this create a data protection problem?
It can. Identity images are sensitive, and retaining them past the decision creates an obligation. Set retention to the minimum your regulator and your dispute process require, and confirm the vendor’s retention matches yours rather than assuming it does.
Should the system reject applicants automatically?
For clear template failures and checksum errors, automatic rejection is defensible. For probabilistic signals such as subtle alteration, route to human review, because an unexplained rejection is costly and a reviewer with the flagged region resolves it in seconds.
The Team Behind This Guidance
Our team deploys these systems where somebody eventually has to explain a rejection to a customer or to a regulator, and that shapes what we recommend. Explainability outranks raw accuracy in our shortlists, because a flag a reviewer cannot interpret produces either rubber stamping or blanket rejection, and both are worse than a slightly less accurate model whose reasoning is visible. Matt Rosenthal, our chief executive, keeps the practice focused on operational resilience for growing firms, which here means a fraud control that holds up under scrutiny rather than one that merely performs well on a benchmark.
Set the Threshold Before You Pick the Product
Work out two numbers before any demonstration: your average fraud loss per incident and your cost of losing a genuine customer at the point of verification. The ratio between them is your threshold, and it is the single input that most changes which product suits you and how it should be configured. Vendors will not ask for it, because it is your number rather than theirs, and every evaluation that skips it ends up accepting a default set for somebody else’s risk appetite.
If you want help estimating those figures against your own data, or a review of how your current verification step is performing on real traffic, book a free strategy call with our team.